Переглянути джерело

chore: 整理当前代码并新增 3D 知识图谱界面

wangxi 1 місяць тому
батько
коміт
7698d7eaa0
44 змінених файлів з 4636 додано та 1283 видалено
  1. 1 0
      .gitignore
  2. 76 9
      README.md
  3. 0 243
      docs/DMS字段映射.md
  4. 273 0
      docs/DMS字段映射_最新范围.md
  5. 20 21
      docs/技术方案.md
  6. 690 0
      html/index.html
  7. 823 0
      html/knowledge_graph_3d.html
  8. 1045 0
      html/vendor/OrbitControls.js
  9. 5 0
      html/vendor/three.min.js
  10. BIN
      html/微信图片_20260817170012_14_2.png
  11. BIN
      meta_graph.png
  12. BIN
      meta_graph_project_self_loops.png
  13. BIN
      meta_graph_v2.png
  14. BIN
      meta_graph_v3.png
  15. BIN
      meta_graph_v4.png
  16. BIN
      meta_graph_v5.png
  17. BIN
      meta_graph_v6.png
  18. BIN
      meta_graph_v7.png
  19. 0 92
      scripts/analyze_temporal.py
  20. 0 67
      scripts/audit_template_sources.py
  21. 206 0
      scripts/build_field_association.py
  22. 1 1
      scripts/build_graph.py
  23. 128 0
      scripts/export_meta_schema.py
  24. 0 78
      scripts/fetch_dms_fields.py
  25. 0 306
      scripts/generate_dms_mapping.py
  26. 607 0
      scripts/generate_dms_supplement.py
  27. 0 252
      scripts/generate_manual_fill_workbook.py
  28. 76 75
      scripts/generate_templates.py
  29. 52 42
      scripts/generate_test_data.py
  30. 51 0
      scripts/render_project_self_loops.py
  31. 5 0
      src/knowledge_agent/agent/embedding.py
  32. 9 2
      src/knowledge_agent/agent/graph.py
  33. 43 7
      src/knowledge_agent/agent/nodes.py
  34. 86 7
      src/knowledge_agent/agent/schema_context.py
  35. 206 47
      src/knowledge_agent/api.py
  36. 5 1
      src/knowledge_agent/db.py
  37. 1 2
      src/knowledge_agent/graph/__init__.py
  38. 62 6
      src/knowledge_agent/graph/builder.py
  39. 2 2
      src/knowledge_agent/graph/pipeline.py
  40. 3 3
      src/knowledge_agent/graph/reader.py
  41. 71 3
      src/knowledge_agent/graph/schemas.py
  42. 34 3
      src/knowledge_agent/meta/render.py
  43. 7 8
      src/knowledge_agent/meta/schema.py
  44. 48 6
      src/knowledge_agent/retrieval/templates.py

+ 1 - 0
.gitignore

@@ -5,6 +5,7 @@ __pycache__/
 .uv-cache/
 .pytest_cache/
 *.log
+api_log/
 output/
 dist/
 

+ 76 - 9
README.md

@@ -6,7 +6,7 @@
 
 ## 功能特性
 
-- **知识图谱构建**:13 类数据模板(Excel)→ 字段校验 → 两阶段构建(先节点后关系)→ Neo4j;
+- **知识图谱构建**:15 类数据模板(Excel)→ 字段校验 → 两阶段构建(先节点后关系)→ Neo4j;
 - **Agent 问答**:问题理解(分类+槽位)→ 实体/概念/值 三层接地 → 能力拓展(派生属性推理)
   → 查询规划(含返回字段)→ 执行(按需返回字段)→ 规则+LLM 双层检查 → 带溯源回答;
 - **多轮对话**:同一会话内保留结构化上下文(问题/实体主键/回答),支持拆解式提问与指代;
@@ -52,14 +52,14 @@ DEEPSEEK_MODEL=deepseek-v4-flash
 
 ### 3. 准备嵌入模型
 
-将 Qwen3-Embedding-0.6B 放到 `models/Qwen3-Embedding-0.6B`(首次问答会加载,之后进程内缓存)。
+将 Qwen3-Embedding-0.6B 放到 `models/Qwen3-Embedding-0.6B`(API 服务启动时会预加载;CLI 首次问答会加载,之后进程内缓存)。
 
 ## 数据与图谱构建
 
 ### 生成模板与测试数据
 
 ```powershell
-uv run python scripts/generate_templates.py      # 生成 13 类数据模板(data/templates)
+uv run python scripts/generate_templates.py      # 生成 15 类数据模板(data/templates)
 uv run python scripts/generate_test_data.py      # 生成与模板对应的测试数据(data/test_data)
 ```
 
@@ -71,8 +71,8 @@ uv run python scripts/build_graph.py data/config_example.json --clear
 
 构建分两阶段(先创建全部节点,再创建全部关系),包含字段名写死校验、必填校验与引用存在性校验。
 
-> 真实数据接入:DMS 模型字段映射见 `docs/DMS字段映射.md`;需要人工补填的字段清单见
-> `data/manual_fill/人工补填清单.xlsx`(生成脚本 `scripts/generate_manual_fill_workbook.py`)。
+> 真实数据接入:按最新 DMS 范围的字段映射见 `docs/DMS字段映射_最新范围.md`;需要人工补填的字段清单见
+> `data/manual_fill/DMS补数字段清单.csv`(生成脚本 `scripts/generate_dms_supplement.py`)。
 
 ## Agent 问答(CLI)
 
@@ -138,6 +138,7 @@ SSE 进度事件说明(`event: progress` 的 `data` 含 `node` 与 `label`,`
 | node | label(处理阶段) |
 |---|---|
 | `understand` | 正在理解问题(分类 + 槽位抽取) |
+| `chat` | 正在生成回答 |
 | `reuse_check` | 正在判断是否可复用历史回答 |
 | `answer_reuse` | 正在基于历史回答推导答案 |
 | `ground` | 正在把问题实体对齐到知识图谱 |
@@ -152,6 +153,72 @@ SSE 进度事件说明(`event: progress` 的 `data` 含 `node` 与 `label`,`
 | `scope` | 正在缩小查询范围 |
 | `answer` | 正在生成回答 |
 
+回答生成时还会推送 `event: answer_chunk`(`data: {"text": "..."}`)——最终回答的**逐块增量**,
+前端可边收边追加显示(打字机效果);所有块拼接后与最终 `answer` 字段一致。
+闲聊回复(`chat` 节点)同样走该事件。
+
+### 前端接入示例(SSE 流式解析)
+
+```js
+// 用 fetch 流式读取 SSE(支持 POST /ask/stream)
+const res = await fetch("http://127.0.0.1:8000/ask/stream", {
+  method: "POST",
+  headers: { "Content-Type": "application/json" },
+  body: JSON.stringify({
+    thread_id: "user-001",
+    query: "青浦区图书馆3月份有加班的人是谁",
+    auto_confirm: true,
+    reuse_check: true,
+  }),
+});
+
+const reader = res.body.getReader();
+const decoder = new TextDecoder();
+let buffer = "";
+let answerText = "";
+
+function onEvent(event, data) {
+  if (event === "progress") {
+    // data: {node, label};node=answer/chat 时还带完整 answer
+    if (data.node !== "answer" && data.node !== "chat") setStatus(data.label); // 更新“正在…”状态
+  } else if (event === "answer_chunk") {
+    // data: {text}——最终回答增量,直接追加(打字机效果)
+    answerText += data.text;
+    appendAnswer(data.text);
+  } else if (event === "confirm") {
+    // data: {message, options}——需要人工确认,展示后调 /threads/{id}/resume
+    showConfirm(data);
+  } else if (event === "done") {
+    // data: 完整结果,answer 为最终回答(兜底,防丢块)
+    setAnswer(data.answer);
+  }
+}
+
+// 解析 SSE:按空行分隔事件,每事件含 "event: xxx" 与 "data: {...}"
+while (true) {
+  const { value, done } = await reader.read();
+  if (done) break;
+  buffer += decoder.decode(value, { stream: true });
+  let idx;
+  while ((idx = buffer.indexOf("\n\n")) >= 0) {
+    const raw = buffer.slice(0, idx);
+    buffer = buffer.slice(idx + 2);
+    const lines = raw.split("\n");
+    const event = lines.find((l) => l.startsWith("event: "))?.slice(7);
+    const dataLine = lines.find((l) => l.startsWith("data: "));
+    if (event && dataLine) onEvent(event, JSON.parse(dataLine.slice(6)));
+  }
+}
+```
+
+说明:
+
+- `progress`:更新处理状态(label 已是中文阶段说明);
+- `answer_chunk`:把 `text` 追加到回答区,实现逐字/逐块显示;拼接结果与 `done.answer` 一致;
+- `confirm`(`auto_confirm=false` 时):展示确认信息,用户确认后调 `POST /threads/{id}/resume`(`{reply: "确认"}` 或修改意见);
+- `done`:携带完整结果(含 `answer`、`plan`、`subgraph` 等),作为最终兜底;
+- 原生 `EventSource` 只支持 GET,若要用它,需要把接口改为 GET(当前为 POST,用上面的 fetch 流式方式即可)。
+
 ### curl 示例
 
 Windows PowerShell 下中文 body 建议写 UTF-8 文件避免编码问题:
@@ -197,9 +264,9 @@ knowledge_agent/
 ├── README.md
 ├── docs/                    # 技术方案、DMS 字段映射、架构图
 ├── data/
-│   ├── templates/           # 13 类数据模板(+填写说明)
+│   ├── templates/           # 15 类数据模板(+填写说明)
 │   ├── test_data/           # 测试数据(与模板一一对应)
-│   ├── manual_fill/         # 人工补填清单
+│   ├── manual_fill/         # DMS 补数字段清单 / 人工补填清单
 │   └── config_example.json  # 构建配置
 ├── models/Qwen3-Embedding-0.6B
 ├── scripts/                 # 模板/测试数据/构建/问答 CLI/DMS 映射等
@@ -227,5 +294,5 @@ knowledge_agent/
 | 端口无监听但服务已开 | 确认 `.env` 的 `NEO4J_URI` 与数据库实际端口一致 |
 | 局域网其他人访问不到 | 启动加 `--host 0.0.0.0`,并放行 Windows 防火墙 8000 端口 |
 | 回答数量对不上 / 结果为空 | 用 `--debug` 看执行详情(实参/丢弃参数/Cypher/行数)与检查报告 |
-| 首次运行慢 | 属正常:加载嵌入模型 + 多次 DeepSeek 调用;之后同进程会快 |
-| DMS token 过期 | 从 DMS 控制台重新复制 `vuejs_token`(见 `scripts/fetch_dms_fields.py`) |
+| 首次运行慢 | API 服务启动时会预加载嵌入模型;首次业务请求仍可能有实体索引构建和 DeepSeek 调用,之后同进程会快 |
+| DMS token 过期 | 从 DMS 控制台重新复制 `vuejs_token`(见 `scripts/generate_dms_supplement.py`) |

+ 0 - 243
docs/DMS字段映射.md

@@ -1,243 +0,0 @@
-# DMS 数据库字段映射(13 类模板)
-
-> 依据 DMS 模型元数据生成(模型:申勤物业数字化 / AMS枢元 相关)。来源分三类:① DMS来源 = 模型.字段(别名);② 源Excel来源(DMS未建模型)= 源 Excel 中确有、但 DMS 无对应模型,需人工从源 Excel 填入;③ 新增融合 = DMS 与源 Excel 均无,为图谱建模/关联额外添加。
-## 覆盖概览
-| 模板 | 字段数 | 有DMS来源 |
-|---|---|---|
-| 人员证书 | 6 | 4 |
-| 项目片区关系 | 5 | 4 |
-| 片区信息 | 5 | 4 |
-| 检查记录 | 11 | 3 |
-| 采购与维保 | 17 | 5 |
-| 设备信息 | 18 | 4 |
-| 岗位编制 | 8 | 4 |
-| 排班明细 | 7 | 3 |
-| 考勤与人员财务 | 15 | 3 |
-| 人员信息 | 18 | 15 |
-| 投标记录 | 11 | 7 |
-| 项目月度财务 | 9 | 3 |
-| 项目信息 | 29 | 24 |
-
-## 项目信息
-**说明**:专用模型:sq_project(申勤项目数据) + shenqin_project_annual_stat(年化统计) + sq_project_period(项目期次) + sq_xq(续签表)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | sq_project.c_jdbm 金蝶编码 | DMS来源 |
-| 项目名称 | sq_project.c_xmmc 项目名称 | DMS来源 |
-| 项目简称 | shenqin_project_annual_stat.c_project_short_name 项目简称 | DMS来源 |
-| 上级项目编号 | sq_project.c_father_code 父项目编码 | DMS来源 |
-| 续签前项目编号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 项目起止时间 | sq_project_period.c_c_date_range_text 日期区间 | DMS来源 |
-| 省份 | sq_project.c_sfzxs 省份(直辖市) | DMS来源 |
-| 市(区) | sq_project.c_sq 市(区) | DMS来源 |
-| 细分业态 | sq_project.c_xfyt 细分业态 | DMS来源 |
-| 汇总业态 | sq_project.c_hzyt 汇总业态 | DMS来源 |
-| 委托方式 | sq_project.c_wtfs 委托方式 | DMS来源 |
-| 计费方式 | sq_project.c_jffs 计费方式 | DMS来源 |
-| 合同面积 | sq_project.c_htmj 合同面积(平方米) | DMS来源 |
-| 合同金额 | shenqin_project_annual_stat.c_contract_amount 合同金额 | DMS来源 |
-| 年化合同额 | shenqin_project_annual_stat.c_annualized_amount 年化合同额 | DMS来源 |
-| 合同额具体信息 | shenqin_project_annual_stat.c_current_period_amount/预估/存量/新增 | DMS来源 |
-| 服务期限 | shenqin_project_annual_stat.c_service_period 服务期限 | DMS来源 |
-| 合同状况 | shenqin_project_annual_stat.c_contract_status_online/offline | DMS来源 |
-| 首次服务日期 | sq_project.c_scfwrq 首次服务日期 | DMS来源 |
-| 年化合同收入 | sq_project.c_nhhtsr 年化合同收入 | DMS来源 |
-| 客户满意度 | 源Excel:运营部\03 客户满意度及投诉记录\客户满意度\申勤物业服务满意度评价问卷报告(2025年度).docx → 满意度得分(聚合为项目属性) | 源Excel来源(DMS未建模型) |
-| 客户投诉 | 源Excel:运营部\03 客户满意度及投诉记录\客户投诉\SHSQ-JGJL-02-0301客户投诉受理单.doc 等 → 投诉条数 | 源Excel来源(DMS未建模型) |
-| 甲方名称 | shenqin_project_annual_stat.c_client_name 甲方名称 | DMS来源 |
-| 项目地址 | shenqin_project_annual_stat.c_project_address 项目地址 | DMS来源 |
-| 项目负责人 | sq_project.c_xmdzfzr 项目点状负责人 | DMS来源 |
-| 项目负责人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 实际毛利率 | sq_project.c_xmdnsjmll 项目当年实际毛利率 | DMS来源 |
-| 服务状态 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 项目月度财务
-**说明**:DMS 无月度开票/收款明细(仅年化/合同金额)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 年月 | 源Excel:财务部收费进程表(1-12月物业费/期内开票收款) | 源Excel来源(DMS未建模型) |
-| 开票金额 | 源Excel:财务部收费进程表(1-12月物业费/期内开票收款) | 源Excel来源(DMS未建模型) |
-| 收款金额 | 源Excel:财务部收费进程表(1-12月物业费/期内开票收款) | 源Excel来源(DMS未建模型) |
-| 口径说明 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 财务经办人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 财务经办人 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 投标记录
-**说明**:专用模型:shenqin_txb(投续标表) + shenqin_zbb(招标表) + sq_tender_intent/notice/result(招标意向/公告/结果)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | shenqin_txb.c_jdbm 金蝶编码 | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 年份 | sq_tender_notice.c_publish_time 发布时间 | DMS来源 |
-| 投标类型 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 中标结果 | sq_tender_result.c_winning_suppliers 中标供应商名称 | DMS来源 |
-| 中标日期 | sq_project(申勤项目数据).c_xmzbrq(项目中标日期(中标函)) | DMS来源 |
-| 投标金额 | shenqin_txb.tbbj 投标报价 | DMS来源 |
-| 文档路径 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 投标经办人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 投标经办人 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 人员信息
-**说明**:专用模型:sq_employee(申勤员工)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 姓名 | sq_employee.c_xm 姓名 | DMS来源 |
-| 工号 | sq_employee.c_ygbm 员工编码 | DMS来源 |
-| 组织名称 | sq_employee(申勤员工).c_sszzmc(所属组织名称) | DMS来源 |
-| 岗位名称 | sq_employee.c_gwmc 岗位名称 | DMS来源 |
-| 当前服务项目编号 | sq_employee.c_xmmc 项目名称(五级公司) | DMS来源 |
-| 服务起始年月 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 服务结束年月 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 职级 | sq_employee.c_zj 职级 | DMS来源 |
-| 员工层级 | sq_employee.c_ygcj 员工层级 | DMS来源 |
-| 所属组织名称 | sq_employee.c_sszzmc 所属组织名称 | DMS来源 |
-| 入职日期 | sq_employee.c_rzrq 入职日期 | DMS来源 |
-| 离职日期 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 司龄 | sq_employee.c_sl 司龄 | DMS来源 |
-| 性别 | sq_employee.c_xb 性别 | DMS来源 |
-| 出生日期 | sq_employee.c_csrq 出生日期 | DMS来源 |
-| 政治面貌 | sq_employee.c_zzmm 政治面貌 | DMS来源 |
-| 联系电话 | sq_employee.c_sjhm 手机号码 | DMS来源 |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 考勤与人员财务
-**说明**:DMS 中未发现考勤专用模型(姓名/工号等为跨模型公共字段)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 姓名 | sq_employee(申勤员工).c_xm(姓名) | DMS来源 |
-| 工号 | 源Excel:人事部考勤表「员工编码」列(13 份考勤 xls/xlsx) | 源Excel来源(DMS未建模型) |
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 年月 | 源Excel:考勤表工作表名/表头(如 青浦-赵巷公园-员工岗位考勤表2026年1月-4月员工岗位考勤表.xls →「2026年×月」) | 源Excel来源(DMS未建模型) |
-| 1-31日 | 源Excel:考勤表 1~31 日列,班次标记(常/日/夜/日1 等) | 源Excel来源(DMS未建模型) |
-| 上班天数 | 源Excel:考勤表「上班天数」列 | 源Excel来源(DMS未建模型) |
-| 平时加班小时 | 源Excel:考勤表「平时加班小时」列 | 源Excel来源(DMS未建模型) |
-| 国定加班小时 | 源Excel:考勤表「国定加班小时」列 | 源Excel来源(DMS未建模型) |
-| 餐费补助金额 | 源Excel:考勤表「餐费补助金额」列 | 源Excel来源(DMS未建模型) |
-| 加班超时费金额 | 源Excel:考勤表「加班超时费金额」列 | 源Excel来源(DMS未建模型) |
-| 国定加班费金额 | 源Excel:考勤表「国定加班费金额」列 | 源Excel来源(DMS未建模型) |
-| 值班费金额 | 源Excel:考勤表「值班费金额」列 | 源Excel来源(DMS未建模型) |
-| 税后工资 | 源Excel:考勤表末尾金额列(表头为「员工签字」,实际填月度税后工资,如 4896.25) | 源Excel来源(DMS未建模型) |
-| 备注 | 源Excel:考勤表「备注」列 | 源Excel来源(DMS未建模型) |
-
-## 排班明细
-**说明**:DMS 中未发现排班专用模型
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 姓名 | sq_employee(申勤员工).c_xm(姓名) | DMS来源 |
-| 工号 | 源Excel:人事部排班 xlsx「工号(Employee ID)」列 | 源Excel来源(DMS未建模型) |
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 年月 | 源Excel:排班 xlsx 日期列(2026-01-01 … 2026-01-31),如 排班:青浦-赵巷公园、赵巷文体中心、赵巷镇政府、赵巷品牌公司系统排班(2026年1-4月).xlsx | 源Excel来源(DMS未建模型) |
-| 1-31日班次 | 源Excel:排班 xlsx 1~31 日「班次代码(Shift Code)」列(OFF/A003/SQ-104/M11-033 等) | 源Excel来源(DMS未建模型) |
-| 备注 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-
-## 岗位编制
-**说明**:DMS 无编制/在岗模型(sq_project 仅有定岗人数,为预算口径)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 岗位 | sq_employee(申勤员工).c_gwmc(岗位名称) | DMS来源 |
-| 预算编制 | 源Excel:运营部 9-项目岗位编制汇总.xlsx | 源Excel来源(DMS未建模型) |
-| 项目编制 | 源Excel:运营部 9-项目岗位编制汇总.xlsx | 源Excel来源(DMS未建模型) |
-| 标准工时人数 | 源Excel:运营部 9-项目岗位编制汇总.xlsx | 源Excel来源(DMS未建模型) |
-| 在岗人数 | 源Excel:运营部 9-项目岗位编制汇总.xlsx | 源Excel来源(DMS未建模型) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 设备信息
-**说明**:DMS 中未发现设备台账模型
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 设备编号 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 设备类型 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 规格型号参数 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 制造厂商 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 安装位置 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 出厂日期 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 启用日期 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 入项目日期 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 退项目日期 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 出厂编号 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 完好状况 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 原值 | 源Excel:运营部设备台账(如 青浦工业园区/徐汇环境监测中心) | 源Excel来源(DMS未建模型) |
-| 设备责任人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 设备责任人 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 采购与维保
-**说明**:DMS 中未发现采购/维保模型
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 记录类型 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 供应商名称 | sq_tender_result(结果公告).c_winning_suppliers({"alias":"中标供应商名称","customType":"","defaultValue":"","describe":"中标供应商名称","frontType":"text","id":28,"must":false,"name":"c_winning_suppliers","searchType":"2","sequence":28,"showParam":"name,alias,desc,type,front_type,must,default_value","type":"text"}) | DMS来源 |
-| 供应商编号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 类别 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 名称/合同名称 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 数量 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 单位 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 单价 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 金额 | sq_xq(续签表).c_htje(合同金额) | DMS来源 |
-| 合同年限 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 月份/日期 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 当前状态 | 源Excel:采购部 耗材汇总/维保合同台账/固定资产台账 | 源Excel来源(DMS未建模型) |
-| 经办人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 经办人 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 检查记录
-**说明**:DMS 中未发现品质/安全检查模型
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 检查类型 | 源Excel:运营部品质巡检及整改记录台账 | 源Excel来源(DMS未建模型) |
-| 检查日期 | 源Excel:运营部品质巡检及整改记录台账 | 源Excel来源(DMS未建模型) |
-| 检查得分 | 源Excel:运营部品质巡检及整改记录台账 | 源Excel来源(DMS未建模型) |
-| 问题描述 | 源Excel:运营部品质巡检及整改记录台账 | 源Excel来源(DMS未建模型) |
-| 整改情况 | 源Excel:运营部品质巡检及整改记录台账 | 源Excel来源(DMS未建模型) |
-| 整改完成日期 | 源Excel:运营部品质巡检及整改记录台账 | 源Excel来源(DMS未建模型) |
-| 检查人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 检查人 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 片区信息
-**说明**:专用模型:xzbm(行政编码及片区)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 片区编号 | xzbm.c_part_code 片区编码 | DMS来源 |
-| 片区名称 | xzbm.c_part_name 片区名称 | DMS来源 |
-| 片区负责人工号 | DMS 与源 Excel 均无,图谱建模/关联用 | 新增融合(图谱关联字段) |
-| 片区负责人 | sq_project(申勤项目数据).c_pjfzr(片区负责人) | DMS来源 |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 项目片区关系
-**说明**:无专用关联表:可基于 sq_project.管理区域 / xzbm 行政编码 推导
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 项目编号 | shenqin_txb(投续标表).zbxmbh(招标项目编号) | DMS来源 |
-| 项目名称 | sq_employee(申勤员工).c_xmmc(项目名称) | DMS来源 |
-| 片区编号 | 源Excel:业务大表「管理区域」推导(M:N) | 源Excel来源(DMS未建模型) |
-| 片区名称 | xzbm(行政编码及片区).c_part_name(片区名称) | DMS来源 |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |
-
-## 人员证书
-**说明**:专用模型:sq_personnel_certificate(AMS枢元/人员证书)
-| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |
-|---|---|---|
-| 工号 | sq_personnel_certificate.c_c_person_id 人员ID | DMS来源 |
-| 姓名 | sq_employee(申勤员工).c_xm(姓名) | DMS来源 |
-| 专业类别 | 源Excel:合景悠活职称及资格证书管理登记表 | 源Excel来源(DMS未建模型) |
-| 证书类别 | sq_personnel_certificate.c_c_cert_type 证书类型 | DMS来源 |
-| 证书名称 | 源Excel:合景悠活职称及资格证书管理登记表 | 源Excel来源(DMS未建模型) |
-| 备注 | sq_employee(申勤员工).c_bz(备注) | DMS来源 |

+ 273 - 0
docs/DMS字段映射_最新范围.md

@@ -0,0 +1,273 @@
+# DMS 数据库字段映射(最新范围)
+
+> 依据本次指定的 DMS 数据范围重新生成:
+> 1. 申勤物业数字化:申勤物业项目清单、申勤员工
+> 2. AMS枢元 -- 申勤数字化改造(全部模型)
+
+## 总览
+
+- 范围内 DMS 模型数:24
+- 15 类模板字段总数:177
+- DMS 已有字段:75
+- DMS 无字段(需业务补充):102(源Excel可搬运 67 / 需新增或人工确认 35)
+- 连接字段:31(DMS已有但 Excel 需带 17 / 需补充 14)
+- 补充 Excel 需包含字段总数:119
+
+## 覆盖概览
+
+| 模板 | 字段数 | DMS已有 | DMS无 | 需放入补充Excel |
+|---|---:|---:|---:|---:|
+| 项目信息 | 29 | 22 | 7 | 8 |
+| 项目月度财务 | 9 | 2 | 7 | 8 |
+| 月度快照 | 9 | 2 | 7 | 8 |
+| 科目余额 | 9 | 2 | 7 | 8 |
+| 投标记录 | 11 | 5 | 6 | 7 |
+| 人员信息 | 18 | 16 | 2 | 3 |
+| 考勤与人员财务 | 15 | 4 | 11 | 13 |
+| 排班月报 | 7 | 4 | 3 | 5 |
+| 岗位编制 | 8 | 4 | 4 | 6 |
+| 设备信息 | 18 | 2 | 16 | 17 |
+| 采购与维保 | 17 | 2 | 15 | 16 |
+| 检查记录 | 11 | 2 | 9 | 10 |
+| 片区信息 | 5 | 2 | 3 | 3 |
+| 项目片区关系 | 5 | 3 | 2 | 3 |
+| 人员证书 | 6 | 3 | 3 | 4 |
+
+## 字段级映射
+
+### 项目信息
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 项目简称 | 是 | shenqin_project_annual_stat.c_project_short_name(项目简称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_short_name(项目简称) |
+| 上级项目编号 | 否 | — | 业务字段(源Excel补充) | 否 | 可由业务大表层级/委托方式推导后回填 |
+| 续签前项目编号 | 否 | — | 业务字段(源Excel补充) | 否 | 可由续签链/档案目录推导后回填 |
+| 项目起止时间 | 是 | shenqin_project_annual_stat.c_contract_period(合同起止日期) / sq_project_period.c_c_date_range_text(日期区间) | DMS已有 | 否 | shenqin_project_annual_stat.c_contract_period(合同起止日期) / sq_project_period.c_c_date_range_text(日期区间) |
+| 省份 | 是 | ams_sq_project.c_sfzxs(省份/直辖市) | DMS已有 | 否 | ams_sq_project.c_sfzxs(省份/直辖市) |
+| 市(区) | 是 | ams_sq_project.c_sq(市/区) | DMS已有 | 否 | ams_sq_project.c_sq(市/区) |
+| 细分业态 | 是 | ams_sq_project.c_xfyt(细分业态) | DMS已有 | 否 | ams_sq_project.c_xfyt(细分业态) |
+| 汇总业态 | 是 | ams_sq_project.c_hzyt(汇总业态) | DMS已有 | 否 | ams_sq_project.c_hzyt(汇总业态) |
+| 委托方式 | 是 | ams_sq_project.c_wtfs(委托方式) | DMS已有 | 否 | ams_sq_project.c_wtfs(委托方式) |
+| 计费方式 | 是 | ams_sq_project.c_jffs(计费方式) | DMS已有 | 否 | ams_sq_project.c_jffs(计费方式) |
+| 合同面积 | 是 | shenqin_project_annual_stat.c_building_area_sqm(建筑面积) / ams_sq_project.c_htmj(合同面积) | DMS已有 | 否 | shenqin_project_annual_stat.c_building_area_sqm(建筑面积) / ams_sq_project.c_htmj(合同面积) |
+| 合同金额 | 是 | shenqin_project_annual_stat.c_contract_amount(合同金额) | DMS已有 | 否 | shenqin_project_annual_stat.c_contract_amount(合同金额) |
+| 年化合同额 | 是 | shenqin_project_annual_stat.c_annualized_amount(年化合同额) | DMS已有 | 否 | shenqin_project_annual_stat.c_annualized_amount(年化合同额) |
+| 合同额具体信息 | 是 | shenqin_project_annual_stat.c_current_period_amount / c_stock_amount / c_new_amount / c_estimated_amount | DMS已有 | 否 | shenqin_project_annual_stat.c_current_period_amount / c_stock_amount / c_new_amount / c_estimated_amount |
+| 服务期限 | 是 | shenqin_project_annual_stat.c_service_period(服务期限) | DMS已有 | 否 | shenqin_project_annual_stat.c_service_period(服务期限) |
+| 合同状况 | 是 | shenqin_project_annual_stat.c_contract_status_online / c_contract_status_offline | DMS已有 | 否 | shenqin_project_annual_stat.c_contract_status_online / c_contract_status_offline |
+| 首次服务日期 | 是 | ams_sq_project.c_scfwrq(首次服务日期) | DMS已有 | 否 | ams_sq_project.c_scfwrq(首次服务日期) |
+| 年化合同收入 | 是 | ams_sq_project.c_nhhtsr(年化合同收入) | DMS已有 | 否 | ams_sq_project.c_nhhtsr(年化合同收入) |
+| 客户满意度 | 否 | — | 业务字段(源Excel补充) | 否 | 市场部项目管理表 / 业务大表 |
+| 客户投诉 | 否 | — | 业务字段(源Excel补充) | 否 | 市场部项目管理表 / 业务大表 |
+| 甲方名称 | 是 | shenqin_project_annual_stat.c_client_name(甲方名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_client_name(甲方名称) |
+| 项目地址 | 是 | shenqin_project_annual_stat.c_project_address(项目地址) / ams_sq_project.c_xmdz(项目地址) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_address(项目地址) / ams_sq_project.c_xmdz(项目地址) |
+| 项目负责人 | 是 | ams_sq_project.c_xmdzfzr(项目点状负责人) | DMS已有 | 否 | ams_sq_project.c_xmdzfzr(项目点状负责人) |
+| 项目负责人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 有项目负责人姓名;工号需按姓名在员工花名册中匹配 |
+| 实际毛利率 | 是 | ams_sq_project.c_xmdnsjmll(项目当年实际毛利率) | DMS已有 | 否 | ams_sq_project.c_xmdnsjmll(项目当年实际毛利率) |
+| 服务状态 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 项目月度财务
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 年月 | 否 | — | 连接字段(需补充) | 是 | 财务部收费进程表(1-12月物业费/期内开票收款) |
+| 开票金额 | 否 | — | 业务字段(源Excel补充) | 否 | 财务部收费进程表(1-12月物业费/期内开票收款) |
+| 收款金额 | 否 | — | 业务字段(源Excel补充) | 否 | 财务部收费进程表(1-12月物业费/期内开票收款) |
+| 口径说明 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 财务经办人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 财务经办人 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 月度快照
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 年月 | 否 | — | 连接字段(需补充) | 是 | 由考勤/排班/项目月度财务汇总生成(可参考 scripts/sample_snapshot.py) |
+| 在岗人数 | 否 | — | 业务字段(源Excel补充) | 否 | 优先按考勤明细不同工号数统计,并与岗位编制在岗人数核对 |
+| 排班人次 | 否 | — | 业务字段(源Excel补充) | 否 | 排班月报按项目+年月汇总行数 |
+| 考勤人次 | 否 | — | 业务字段(源Excel补充) | 否 | 考勤明细按项目+年月汇总行数 |
+| 开票金额 | 否 | — | 业务字段(源Excel补充) | 否 | 由考勤/排班/项目月度财务汇总生成(可参考 scripts/sample_snapshot.py) |
+| 收款金额 | 否 | — | 业务字段(源Excel补充) | 否 | 由考勤/排班/项目月度财务汇总生成(可参考 scripts/sample_snapshot.py) |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 科目余额
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 期间 | 否 | — | 连接字段(需补充) | 是 | 财务部科目余额表(科目编码/名称/借贷发生额/期末余额) |
+| 科目编码 | 否 | — | 连接字段(需补充) | 是 | 财务科目编码,同一项目同一期间内唯一 |
+| 科目名称 | 否 | — | 业务字段(源Excel补充) | 否 | 与科目编码配套的中文科目名称 |
+| 借方发生额 | 否 | — | 业务字段(源Excel补充) | 否 | 财务部科目余额表(科目编码/名称/借贷发生额/期末余额) |
+| 贷方发生额 | 否 | — | 业务字段(源Excel补充) | 否 | 财务部科目余额表(科目编码/名称/借贷发生额/期末余额) |
+| 期末余额 | 否 | — | 业务字段(源Excel补充) | 否 | 财务部科目余额表(科目编码/名称/借贷发生额/期末余额) |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 投标记录
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 年份 | 否 | — | 连接字段(需补充) | 是 | 业务大表中标情况 / 档案目录 |
+| 投标类型 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 中标结果 | 是 | ams_sq_project.c_zbjgrzbdrhxsj(中标结果) | DMS已有 | 否 | ams_sq_project.c_zbjgrzbdrhxsj(中标结果) |
+| 中标日期 | 是 | ams_sq_project.c_xmzbrq(项目中标日期) | DMS已有 | 否 | ams_sq_project.c_xmzbrq(项目中标日期) |
+| 投标金额 | 否 | — | 业务字段(源Excel补充) | 否 | 业务大表中标情况 / 档案目录 |
+| 文档路径 | 是 | sq_project_file.c_c_abs_path(绝对路径) / sq_bid_archive_scan.c_c_abs_path(标书扫描绝对路径) | DMS已有 | 否 | sq_project_file.c_c_abs_path(绝对路径) / sq_bid_archive_scan.c_c_abs_path(标书扫描绝对路径) |
+| 投标经办人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 投标经办人 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 人员信息
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 姓名 | 是 | sq_employee.c_xm(姓名) | DMS已有 | 否 | sq_employee.c_xm(姓名) |
+| 工号 | 是 | sq_employee.c_ygbm(员工编码) | 连接字段(DMS已有,Excel需带) | 是 | sq_employee.c_ygbm(员工编码) |
+| 组织名称 | 是 | sq_employee.c_sszzmc(所属组织名称) | DMS已有 | 否 | sq_employee.c_sszzmc(所属组织名称) |
+| 岗位名称 | 是 | sq_employee.c_gwmc(岗位名称) | DMS已有 | 否 | sq_employee.c_gwmc(岗位名称) |
+| 当前服务项目编号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS sq_employee 只有项目名称/GUID,编号需按项目名称映射 |
+| 服务起始年月 | 是 | sq_employee.c_htksrq(合同开始日期,口径需确认) | DMS已有 | 否 | sq_employee.c_htksrq(合同开始日期,口径需确认) |
+| 服务结束年月 | 是 | sq_employee.c_htjsrq(合同结束日期,口径需确认) | DMS已有 | 否 | sq_employee.c_htjsrq(合同结束日期,口径需确认) |
+| 职级 | 是 | sq_employee.c_zj(职级) | DMS已有 | 否 | sq_employee.c_zj(职级) |
+| 员工层级 | 是 | sq_employee.c_ygcj(员工层级) | DMS已有 | 否 | sq_employee.c_ygcj(员工层级) |
+| 所属组织名称 | 是 | sq_employee.c_sszzmc(所属组织名称) | DMS已有 | 否 | sq_employee.c_sszzmc(所属组织名称) |
+| 入职日期 | 是 | sq_employee.c_rzrq(入职日期) | DMS已有 | 否 | sq_employee.c_rzrq(入职日期) |
+| 离职日期 | 否 | — | 业务字段(源Excel补充) | 否 | DMS 只有合同结束日期,不是离职日期,需人工补 |
+| 司龄 | 是 | sq_employee.c_sl(司龄) | DMS已有 | 否 | sq_employee.c_sl(司龄) |
+| 性别 | 是 | sq_employee.c_xb(性别) | DMS已有 | 否 | sq_employee.c_xb(性别) |
+| 出生日期 | 是 | sq_employee.c_csrq(出生日期) | DMS已有 | 否 | sq_employee.c_csrq(出生日期) |
+| 政治面貌 | 是 | sq_employee.c_zzmm(政治面貌) | DMS已有 | 否 | sq_employee.c_zzmm(政治面貌) |
+| 联系电话 | 是 | sq_employee.c_sjhm(手机号码) | DMS已有 | 否 | sq_employee.c_sjhm(手机号码) |
+| 备注 | 是 | sq_employee.c_bz(备注) | DMS已有 | 否 | sq_employee.c_bz(备注) |
+
+### 考勤与人员财务
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 姓名 | 是 | sq_employee.c_xm(姓名) | DMS已有 | 否 | sq_employee.c_xm(姓名) |
+| 工号 | 是 | sq_employee.c_ygbm(员工编码) | 连接字段(DMS已有,Excel需带) | 是 | sq_employee.c_ygbm(员工编码) |
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / sq_employee.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / sq_employee.c_xmmc(项目名称) |
+| 年月 | 否 | — | 连接字段(需补充) | 是 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 1-31日 | 否 | — | 业务字段(源Excel补充) | 否 | 值为 常/日/夜/日1 等班次标记,原样搬运 |
+| 上班天数 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 平时加班小时 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 国定加班小时 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 餐费补助金额 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 加班超时费金额 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 国定加班费金额 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 值班费金额 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+| 税后工资 | 否 | — | 业务字段(源Excel补充) | 否 | 源考勤表无该列名,部分文件金额填在表头为「员工签字」的列 |
+| 备注 | 否 | — | 业务字段(源Excel补充) | 否 | 人事部考勤表(13份考勤 xls/xlsx) |
+
+### 排班月报
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 姓名 | 是 | sq_employee.c_xm(姓名) | DMS已有 | 否 | sq_employee.c_xm(姓名) |
+| 工号 | 是 | sq_employee.c_ygbm(员工编码) | 连接字段(DMS已有,Excel需带) | 是 | sq_employee.c_ygbm(员工编码) |
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / sq_employee.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / sq_employee.c_xmmc(项目名称) |
+| 年月 | 否 | — | 连接字段(需补充) | 是 | 人事部排班文件(每日班次代码) |
+| 1-31日班次 | 否 | — | 业务字段(源Excel补充) | 否 | 值为班次代码,如 OFF/A003/SQ-104/M11-033;OFF=休息 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 岗位编制
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 岗位 | 是 | sq_position_salary.c_c_position_name(岗位名称) / sq_employee.c_gwmc(岗位名称) | 连接字段(DMS已有,Excel需带) | 是 | sq_position_salary.c_c_position_name(岗位名称) / sq_employee.c_gwmc(岗位名称) |
+| 预算编制 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部 9-项目岗位编制汇总.xlsx |
+| 项目编制 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部 9-项目岗位编制汇总.xlsx |
+| 标准工时人数 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部 9-项目岗位编制汇总.xlsx |
+| 在岗人数 | 是 | ams_sq_project.c_xmygrs(项目员工人数,需按岗位拆分) | DMS已有 | 否 | ams_sq_project.c_xmygrs(项目员工人数,需按岗位拆分) |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 设备信息
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 设备编号 | 否 | — | 连接字段(需补充) | 是 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 设备类型 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 名称 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 规格型号参数 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 制造厂商 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 安装位置 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 出厂日期 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 启用日期 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 入项目日期 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 退项目日期 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 出厂编号 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 完好状况 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 原值 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部设备台账(青浦工业园区/徐汇环境监测中心) |
+| 设备责任人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | 模板必填;源台账可能有责任人姓名,工号需匹配花名册 |
+| 设备责任人 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 采购与维保
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 记录类型 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 供应商名称 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 供应商编号 | 否 | — | 业务字段(新增/人工确认) | 否 | 用于关联供应商主数据;DMS 范围内无供应商模型,需新编或另建 |
+| 类别 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 名称/合同名称 | 否 | — | 连接字段(需补充) | 是 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 数量 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 单位 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 单价 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 金额 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 合同年限 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 月份/日期 | 否 | — | 连接字段(需补充) | 是 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 当前状态 | 否 | — | 业务字段(源Excel补充) | 否 | 采购部耗材汇总/维保合同台账/固定资产台账 |
+| 经办人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 经办人 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 检查记录
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 检查类型 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部品质巡检及整改记录台账 |
+| 检查日期 | 否 | — | 连接字段(需补充) | 是 | 运营部品质巡检及整改记录台账 |
+| 检查得分 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部品质巡检及整改记录台账 |
+| 问题描述 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部品质巡检及整改记录台账 |
+| 整改情况 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部品质巡检及整改记录台账 |
+| 整改完成日期 | 否 | — | 业务字段(源Excel补充) | 否 | 运营部品质巡检及整改记录台账 |
+| 检查人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 检查人 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 片区信息
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 片区编号 | 否 | — | 连接字段(需补充) | 是 | 最新 DMS 范围内没有 xzbm 片区模型,需人工统一编码 |
+| 片区名称 | 是 | ams_sq_project.c_glqynbkj(管理区域内部口径) / sq_shenqin_project.c_c_region(区域) | DMS已有 | 否 | ams_sq_project.c_glqynbkj(管理区域内部口径) / sq_shenqin_project.c_c_region(区域) |
+| 片区负责人工号 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+| 片区负责人 | 是 | ams_sq_project.c_pjfzr(片区负责人) | DMS已有 | 否 | ams_sq_project.c_pjfzr(片区负责人) |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 项目片区关系
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 项目编号 | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) | 连接字段(DMS已有,Excel需带) | 是 | shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号) |
+| 项目名称 | 是 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) | DMS已有 | 否 | shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称) |
+| 片区编号 | 否 | — | 连接字段(需补充) | 是 | 同上,需与片区信息表保持一致 |
+| 片区名称 | 是 | ams_sq_project.c_glqynbkj(管理区域内部口径) / sq_shenqin_project.c_c_region(区域) | DMS已有 | 否 | ams_sq_project.c_glqynbkj(管理区域内部口径) / sq_shenqin_project.c_c_region(区域) |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |
+
+### 人员证书
+| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |
+|---|---|---|---|---|---|
+| 工号 | 是 | sq_personnel_certificate.c_c_person_id(人员ID,需与 sq_employee.c_ygbm 核对映射) | 连接字段(DMS已有,Excel需带) | 是 | sq_personnel_certificate.c_c_person_id(人员ID,需与 sq_employee.c_ygbm 核对映射) |
+| 姓名 | 是 | sq_personnel_material.c_c_name(姓名) / sq_employee.c_xm(姓名) | DMS已有 | 否 | sq_personnel_material.c_c_name(姓名) / sq_employee.c_xm(姓名) |
+| 专业类别 | 否 | — | 业务字段(源Excel补充) | 否 | 合景悠活职称及资格证书管理登记表 |
+| 证书类别 | 是 | sq_personnel_certificate.c_c_cert_type(证书类型) | DMS已有 | 否 | sq_personnel_certificate.c_c_cert_type(证书类型) |
+| 证书名称 | 否 | — | 连接字段(需补充) | 是 | DMS 证书表只有证书类型/证书号掩码,证书全称需补充 |
+| 备注 | 否 | — | 业务字段(新增/人工确认) | 否 | DMS 范围内无对应字段,需人工确认 |

+ 20 - 21
docs/技术方案.md

@@ -1,7 +1,7 @@
 # 知识图谱 Agent 问答系统 —— 技术方案
 
 > 状态:**已定稿**,作为后续开发的唯一权威依据;任何变更需同步更新本文档。
-> 最后更新:2026-08-12(与当前 13 类数据模板、两阶段构建器、检索层实现保持一致)
+> 最后更新:2026-08-14(与当前 15 类数据模板、两阶段构建器、检索层实现保持一致)
 
 ## 1. 项目概述
 
@@ -26,8 +26,8 @@
 | 维保/采购 | 维保合同台账、耗材汇总、固定资产台账 | 采购部常用表格 |
 | 岗位薪资标准 | 区域 × 岗位 税前/税后区间 | 各管理处岗位薪资1.xlsx(系统侧参考,不进模板) |
 | 人员证书 | 一人多行(华东区域/申勤两 sheet),含 工号/职位/专业类别/证书类别/证书名称 | 合景悠活职称及资格证书管理登记表(2026年第一季度) |
-| **数据模板** | 13 类、每份一个数据表(+填写说明),含必填唯一标识与字段依据 | data/templates |
-| **测试数据** | 13 类与模板一一对应(16 项目/34 人员/33 考勤/9 证书等) | data/test_data |
+| **数据模板** | 15 类、每份一个数据表(+填写说明),含必填唯一标识与字段依据 | data/templates |
+| **测试数据** | 15 类与模板一一对应(16 项目/34 人员/33 考勤/9 证书等) | data/test_data |
 | 时间覆盖 | 2026-01 ~ 2026-04(科创含 25.12) | — |
 
 ## 2. 技术选型
@@ -52,7 +52,7 @@ graph TB
   DMS[DMS 16 个申勤模型] --> FETCH[字段映射/数据拉取]
   MAN[人工补填清单<br/>data/manual_fill] --> MERGE[按键合并<br/>merge_dms_to_templates]
   FETCH --> MERGE
-  MERGE --> TPL[13 类模板 Excel]
+  MERGE --> TPL[15 类模板 Excel]
   TPL --> CHECK1[字段名写死校验<br/>graph/reader]
   CHECK1 --> NODES[阶段一:创建全部节点]
   NODES --> EDGES[阶段二:创建全部关系]
@@ -73,7 +73,7 @@ graph TB
 </details>
 
 > 状态:🟧 **橙色 = 规划中**(DMS 模型元数据已识别,但数据值拉取脚本、`merge_dms_to_templates`
-> 合并脚本、人工实际填写补填清单尚未完成);🟩 **绿色 = 已实现**(13 类模板与测试数据、
+> 合并脚本、人工实际填写补填清单尚未完成);🟩 **绿色 = 已实现**(15 类模板与测试数据、
 > `graph/reader` 字段名写死校验、两阶段构建、引用存在性校验,测试数据端到端跑通)。
 
 ### 3.2 问答 Agent 流程(LangGraph)
@@ -220,7 +220,7 @@ graph TB
 - 唯一约束:项目.编号、人员.工号、片区.编号;设备 (项目编号, 设备编号) 节点键。
 - 导入策略:MERGE 幂等,可全量重建;构建分两阶段(先节点后关系),避免顺序依赖。
 
-### 4.6 数据模板(13 类,每份一个数据表 + 填写说明)
+### 4.6 数据模板(15 类,每份一个数据表 + 填写说明)
 
 | 模板 | 必填列 | 字段依据 |
 |---|---|---|
@@ -229,7 +229,7 @@ graph TB
 | 投标记录 | 项目编号 / 年份 / 投标经办人工号 | 同上 |
 | 人员信息 | 姓名 / 工号 / 岗位名称 | 同上 |
 | 考勤与人员财务 | 姓名 / 工号 / 项目编号 / 年月 | 同上(1-31 日状态代码含义见说明) |
-| 排班明细 | 姓名 / 工号 / 项目编号 / 年月 | 同上(1-31 日班次代码 + 常用对照见说明) |
+| 排班月报 | 姓名 / 工号 / 项目编号 / 年月 | 同上(1-31 日班次代码 + 常用对照见说明) |
 | 岗位编制 | 项目编号 / 岗位 | 同上 |
 | 设备信息 | 项目编号 / 设备编号 / 设备责任人工号 | 同上 |
 | 采购与维保 | 记录类型 / 项目编号 / 经办人工号 | 同上(供应商/维保合同/耗材采购/固定资产四类共用) |
@@ -238,7 +238,7 @@ graph TB
 | 项目片区关系 | 项目编号 / 片区编号 | 同上 |
 | 人员证书 | 工号 / 证书名称 | 同上(登记表申勤 sheet 缺工号,需按姓名在花名册补全) |
 
-模板生成脚本:`scripts/generate_templates.py`;字段来源审计:`scripts/audit_template_sources.py`
+模板生成脚本:`scripts/generate_templates.py`;字段来源说明由该脚本生成模板时维护
 
 ## 5. 数据构建管线(graph/ 模块)
 
@@ -268,8 +268,8 @@ graph TB
 
 ### 5.5 DMS 数据 → 模板 合并(数据接入管线)
 
-**最终目标**:DMS 已有数据 + 员工人工补填 → 生成 13 类模板样式文件 → 图谱构建。
-模板字段按来源分三类(见 `docs/DMS字段映射.md`):
+**最终目标**:DMS 已有数据 + 员工人工补填 → 生成 15 类模板样式文件 → 图谱构建。
+模板字段按来源分三类(见 `docs/DMS字段映射_最新范围.md`):
 
 | 来源类型 | 含义 | 处理方式 |
 |---|---|---|
@@ -277,8 +277,8 @@ graph TB
 | 源Excel搬运(DMS未建模型) | 源 Excel 有、DMS 无模型(考勤/排班/设备/检查/月度财务等) | 人工从源文件搬运到模板 |
 | 新增融合 | DMS 与源 Excel 均无,为图谱关联/可读性添加 | 人工确认填写(工号/项目编号/片区编号等) |
 
-**人工补填清单**:`data/manual_fill/人工补填清单.xlsx`
-(生成脚本 `scripts/generate_manual_fill_workbook.py`),列出全部 76 个需人工补填字段:
+**人工补填清单**:`data/manual_fill/DMS补数字段清单.csv`
+(生成脚本 `scripts/generate_dms_supplement.py`),列出全部需人工补填字段:
 51 个源Excel搬运 + 25 个新增融合,逐字段标注来源文件+列、与 DMS 的对齐键、是否必填。
 
 **合并流程**:
@@ -461,10 +461,10 @@ knowledge_agent/
 ├── .env                     # NEO4J_* / DEEPSEEK_*(不入库)
 ├── docs/技术方案.md
 ├── data/
-│   ├── templates/           # 13 类单表模板(+填写说明)
+│   ├── templates/           # 15 类单表模板(+填写说明)
 │   ├── test_data/           # 与模板一一对应的测试数据
 │   ├── manual_fill/         # 人工补填清单(DMS 无模型字段的填写任务)
-│   └── config_example.json  # 13 类文件数组示例配置
+│   └── config_example.json  # 15 类文件数组示例配置
 ├── src/knowledge_agent/
 │   ├── config.py
 │   ├── meta/                # 元知识图谱(schema/builder/render)
@@ -473,9 +473,8 @@ knowledge_agent/
 │   └── agent/               # LangGraph:分类/槽位/接地/确认/计划/执行/审查/范围/问答
 ├── scripts/
 │   ├── generate_templates.py / generate_test_data.py
-│   ├── audit_template_sources.py
-│   ├── fetch_dms_fields.py / generate_dms_mapping.py   # DMS 模型字段映射
-│   ├── generate_manual_fill_workbook.py                # 人工补填清单
+│   ├── generate_dms_supplement.py                      # DMS 补数字段清单
+│   ├── export_meta_schema.py                           # 元知识图谱 JSON 导出
 │   ├── build_graph.py       # CLI 图谱构建
 │   ├── test_retrieval.py    # 检索层冒烟测试
 │   ├── ask.py               # 交互式问答 CLI(含确认/范围收缩)
@@ -488,7 +487,7 @@ knowledge_agent/
 | 阶段 | 内容 | 状态 |
 |---|---|---|
 | P0 数据准备 | 项目别名表、组织代码映射、档案目录续签链、口径清单 | 部分完成(续签链/排班归属分析脚本就绪) |
-| P1 全量图谱 | 13 类模板解析 + 两阶段构建 + 校验 + CLI | ✅ 已实现,测试数据端到端跑通 |
+| P1 全量图谱 | 15 类模板解析 + 两阶段构建 + 校验 + CLI | ✅ 已实现,测试数据端到端跑通 |
 | P2 实体索引 | 内存索引 + 分层匹配 + 置信度 + 服务中优先 | ✅ 已实现 |
 | P3 模板工具集 | 查询函数 + 聚合统计/缺勤分析 + LLM 槽位抽取(DeepSeek JSON) | ✅ 已实现(6.1-6.3) |
 | P4 Agent 检索 | Plan/Execute/Reflect + trace + 槽位确认/范围收缩/上下文记忆 + --debug | ✅ 已实现(CLI 交互 + --auto/--debug) |
@@ -497,7 +496,7 @@ knowledge_agent/
 
 ## 9. 已确认的默认决策
 
-1. 模板结构:**13 类、每份一个数据表**(避免多 sheet 跨表填写);关联用 项目编号/工号 必填;
+1. 模板结构:**15 类、每份一个数据表**(避免多 sheet 跨表填写);关联用 项目编号/工号 必填;
 2. 当事人必填:项目负责人、检查人、投标/采购/财务经办人、设备责任人、片区负责人 均需工号;
 3. 岗位名称与岗位编制统一规范名;员工层级为分类(岗位字典映射校验);
 4. 财务口径:开票/收款分字段存储,口径待财务确认;
@@ -590,7 +589,7 @@ knowledge_agent/
 | S-4 | 输入安全 | 防提示词注入:输入规范化、恶意指令检测、系统提示词边界强化 | `agent/llm.py` + 输入预处理 | ⬜ |
 | S-5 | 输出安全 | 回答后校验:不输出敏感字段、不产生"已修改/已删除"类误导 | `nodes.answer` 后处理 | ⬜ |
 | S-6 | Neo4j 只读账号 | 问答用只读凭据,构建用写凭据,账号级隔离写权限 | `.env` + `config.py` + `retrieval/templates.py` | ⬜ |
-| S-7 | DMS token 管理 | 把硬编码 token 移入 `.env`,到期提醒/自动刷新 | `scripts/fetch_dms_fields.py` | 🟡 |
+| S-7 | DMS token 管理 | 把硬编码 token 移入 `.env`,到期提醒/自动刷新 | `scripts/generate_dms_supplement.py` | 🟡 |
 | S-8 | API 认证与限流 | FastAPI + JWT,`user_id` 从 token 取;角色映射;限流/配额 | API 层(规划) | ⬜ |
 | S-9 | 敏感字段清单维护 | 集中维护敏感字段/意图,增删一处生效 | `data/permissions.json` | ✅ |
 
@@ -603,4 +602,4 @@ knowledge_agent/
 | `src/knowledge_agent/agent/llm.py` | SYSTEM_SAFETY 只读约束 |
 | `src/knowledge_agent/agent/nodes.py` | permission_check / denied 节点(待接线) |
 | `.env` / `.env.example` | 凭据(Neo4j / DeepSeek / 后续 DMS token) |
-| `scripts/fetch_dms_fields.py` | DMS 模型字段拉取(token 待移入 .env) |
+| `scripts/generate_dms_supplement.py` | DMS 补数字段清单生成(token 待移入 .env) |

+ 690 - 0
html/index.html

@@ -0,0 +1,690 @@
+<!doctype html>
+<html lang="zh-CN">
+<head>
+  <meta charset="utf-8">
+  <meta name="viewport" content="width=device-width, initial-scale=1">
+  <title>申勤物业知识助手</title>
+  <style>
+    :root {
+      --bg: #f5f7fb;
+      --panel: #ffffff;
+      --border: #d9e1ec;
+      --primary: #2f5597;
+      --primary-dark: #24426f;
+      --text: #22303f;
+      --muted: #7a8794;
+      --user-bubble: #e7f0ff;
+      --assistant-bubble: #ffffff;
+      --danger: #c0392b;
+      --warn-bg: #fff7e6;
+    }
+
+    * { box-sizing: border-box; }
+
+    body {
+      margin: 0;
+      background: var(--bg);
+      color: var(--text);
+      font-family: "Microsoft YaHei", "PingFang SC", system-ui, sans-serif;
+      height: 100vh;
+      display: flex;
+      justify-content: center;
+      align-items: center;
+    }
+
+    .app {
+      width: min(960px, 96vw);
+      height: min(900px, 94vh);
+      background: var(--panel);
+      border: 1px solid var(--border);
+      border-radius: 16px;
+      box-shadow: 0 18px 50px rgba(35, 48, 63, 0.12);
+      display: flex;
+      flex-direction: column;
+      overflow: hidden;
+    }
+
+    header {
+      padding: 14px 18px;
+      border-bottom: 1px solid var(--border);
+      background: #ffffff;
+    }
+
+    header h1 {
+      margin: 0 0 10px;
+      font-size: 18px;
+      color: var(--primary-dark);
+    }
+
+    .controls {
+      display: flex;
+      flex-wrap: wrap;
+      gap: 10px;
+      align-items: center;
+    }
+
+    .controls .spacer {
+      flex: 1;
+    }
+
+    label {
+      display: flex;
+      flex-direction: column;
+      gap: 6px;
+      font-size: 13px;
+      color: var(--muted);
+    }
+
+    input[type="text"],
+    input[type="url"],
+    textarea {
+      width: 100%;
+      border: 1px solid var(--border);
+      border-radius: 9px;
+      padding: 9px 10px;
+      font-size: 14px;
+      font-family: inherit;
+      resize: vertical;
+      background: #fff;
+    }
+
+    input:focus,
+    textarea:focus {
+      outline: none;
+      border-color: var(--primary);
+      box-shadow: 0 0 0 3px rgba(47, 85, 151, 0.12);
+    }
+
+    .check-line {
+      flex-direction: row;
+      align-items: center;
+      gap: 7px;
+      color: var(--text);
+      font-size: 13px;
+      white-space: nowrap;
+    }
+
+    .composer {
+      display: flex;
+      gap: 10px;
+      padding: 12px 16px;
+      border-top: 1px solid var(--border);
+      background: #ffffff;
+    }
+
+    .composer textarea {
+      flex: 1;
+      min-height: 42px;
+      max-height: 150px;
+    }
+
+    .btn {
+      border: 0;
+      border-radius: 9px;
+      padding: 10px 14px;
+      font-size: 14px;
+      cursor: pointer;
+      transition: background 0.2s ease;
+      font-family: inherit;
+      white-space: nowrap;
+    }
+
+    .btn-primary {
+      background: var(--primary);
+      color: #ffffff;
+    }
+
+    .btn-primary:hover { background: var(--primary-dark); }
+    .btn-primary:disabled { opacity: 0.55; cursor: not-allowed; }
+
+    .btn-ghost {
+      background: #eef2f7;
+      color: var(--text);
+    }
+
+    .btn-ghost:hover { background: #e0e7f0; }
+
+    #chat {
+      flex: 1;
+      overflow-y: auto;
+      padding: 22px;
+      background: var(--bg);
+      position: relative;
+    }
+
+    .message-row {
+      position: relative;
+      z-index: 2;
+    }
+
+    .message-row {
+      display: flex;
+      align-items: flex-start;
+      gap: 10px;
+      margin-bottom: 16px;
+    }
+
+    .message-row.user {
+      flex-direction: row-reverse;
+    }
+
+    .avatar {
+      width: 34px;
+      height: 34px;
+      border-radius: 50%;
+      object-fit: cover;
+      flex: none;
+      border: 1px solid var(--border);
+    }
+
+    .user-avatar {
+      display: flex;
+      align-items: center;
+      justify-content: center;
+      background: var(--primary);
+      color: #fff;
+      font-size: 13px;
+    }
+
+    .message {
+      max-width: 78%;
+      padding: 12px 14px;
+      border-radius: 12px;
+      line-height: 1.65;
+      font-size: 14px;
+      white-space: pre-wrap;
+      word-break: break-word;
+      border: 1px solid var(--border);
+    }
+
+    .message.user {
+      background: var(--user-bubble);
+      border-color: #c9dcff;
+    }
+
+    .message.assistant {
+      background: var(--assistant-bubble);
+      border-color: var(--border);
+    }
+
+    .message.error {
+      background: #fdecea;
+      border-color: #f5c6c0;
+      color: var(--danger);
+    }
+
+    .message.system {
+      max-width: 100%;
+      background: #ffffff;
+      color: var(--muted);
+      font-size: 13px;
+      border-style: dashed;
+    }
+
+    #status {
+      padding: 8px 22px;
+      min-height: 26px;
+      border-top: 1px solid var(--border);
+      color: var(--muted);
+      font-size: 13px;
+      background: #ffffff;
+    }
+
+    .progress-flow {
+      display: flex;
+      flex-wrap: wrap;
+      gap: 6px;
+      padding: 0 0 8px;
+      background: transparent;
+      border: none;
+    }
+
+    .answer-text {
+      min-height: 1em;
+    }
+
+    .step-chip {
+      display: inline-flex;
+      align-items: center;
+      gap: 4px;
+      border: 1px solid var(--border);
+      border-radius: 999px;
+      padding: 4px 9px;
+      font-size: 12px;
+      color: var(--muted);
+      background: #ffffff;
+    }
+
+    .step-chip.active {
+      border-color: var(--primary);
+      color: var(--primary-dark);
+      background: #e7f0ff;
+    }
+
+    .step-chip.done {
+      opacity: 0.72;
+      background: #f0f3f7;
+    }
+
+    #confirmPanel {
+      display: none;
+      margin: 0 22px 16px;
+      padding: 14px;
+      border: 1px solid #f1d18b;
+      background: var(--warn-bg);
+      border-radius: 12px;
+    }
+
+    #confirmPanel.show { display: block; }
+
+    #confirmMessage {
+      white-space: pre-wrap;
+      margin-bottom: 12px;
+      font-size: 14px;
+      line-height: 1.6;
+    }
+
+    .option-list {
+      display: flex;
+      flex-wrap: wrap;
+      gap: 8px;
+      margin-bottom: 12px;
+    }
+
+    .option-chip {
+      border: 1px solid #d9b76c;
+      background: #fff8e1;
+      border-radius: 999px;
+      padding: 6px 10px;
+      font-size: 13px;
+      cursor: pointer;
+    }
+
+    .option-chip:hover { background: #ffedb3; }
+
+    .confirm-actions {
+      display: flex;
+      gap: 8px;
+      align-items: center;
+    }
+
+    .confirm-actions input {
+      flex: 1;
+    }
+  </style>
+</head>
+<body>
+  <main class="app">
+    <header>
+      <h1>申勤物业知识助手</h1>
+      <div class="controls">
+        <label class="check-line" title="开启后系统自动确认查询条件与查询计划;关闭后需要你在页面确认或修改。">
+          <input id="autoConfirm" type="checkbox" checked />
+          <span>自动确认</span>
+        </label>
+        <label class="check-line" title="开启后优先判断是否可复用同一会话中的历史回答;关闭后每次都重新查询知识图谱。">
+          <input id="reuseCheck" type="checkbox" checked />
+          <span>复用历史</span>
+        </label>
+        <div class="spacer"></div>
+        <button id="newSessionBtn" class="btn btn-ghost">新会话</button>
+      </div>
+    </header>
+
+    <div id="chat" aria-live="polite"></div>
+
+    <div id="confirmPanel">
+      <div id="confirmMessage"></div>
+      <div id="confirmOptions" class="option-list"></div>
+      <div class="confirm-actions">
+        <input id="confirmReply" type="text" placeholder="回复:确认 / 或说明修改" />
+        <button id="confirmSendBtn" class="btn btn-primary">继续</button>
+      </div>
+    </div>
+
+    <footer class="composer">
+      <textarea id="questionInput" rows="1" placeholder="输入问题,Ctrl + Enter 发送"></textarea>
+      <button id="sendBtn" class="btn btn-primary">发送</button>
+    </footer>
+
+    <div id="status">准备就绪</div>
+  </main>
+
+  <script>
+    const $ = (id) => document.getElementById(id);
+    const chatEl = $("chat");
+    const statusEl = $("status");
+    const sendBtn = $("sendBtn");
+    const questionInput = $("questionInput");
+    const autoConfirmInput = $("autoConfirm");
+    const reuseCheckInput = $("reuseCheck");
+    const confirmPanel = $("confirmPanel");
+    let activeProgressEl = null;
+
+
+
+    const THREAD_KEY = "kg_thread_id";
+
+    function getThreadId() {
+      let id = sessionStorage.getItem(THREAD_KEY);
+      if (!id) {
+        id = typeof crypto !== "undefined" && crypto.randomUUID
+          ? crypto.randomUUID()
+          : "thread-" + Date.now() + "-" + Math.random().toString(16).slice(2);
+        sessionStorage.setItem(THREAD_KEY, id);
+      }
+      return id;
+    }
+
+    function newThreadId() {
+      const id = typeof crypto !== "undefined" && crypto.randomUUID
+        ? crypto.randomUUID()
+        : "thread-" + Date.now() + "-" + Math.random().toString(16).slice(2);
+      sessionStorage.setItem(THREAD_KEY, id);
+      return id;
+    }
+
+    function apiBase() {
+      if (location.protocol === "http:" || location.protocol === "https:") {
+        return location.origin;
+      }
+      return "http://127.0.0.1:8000";
+    }
+
+    function setStatus(text) {
+      statusEl.textContent = text;
+    }
+
+    function addProgressStep(node, label, container) {
+      const chips = Array.from(container.querySelectorAll(".step-chip"));
+      chips.forEach((chip) => chip.classList.remove("active"));
+      chips.forEach((chip) => chip.classList.add("done"));
+      const chip = document.createElement("span");
+      chip.className = "step-chip active";
+      chip.textContent = label || node;
+      chip.title = node;
+      container.appendChild(chip);
+      container.scrollLeft = container.scrollWidth;
+    }
+
+    function finishProgressFlow(container, label) {
+      const chips = Array.from(container.querySelectorAll(".step-chip"));
+      chips.forEach((chip) => chip.classList.remove("active"));
+      chips.forEach((chip) => chip.classList.add("done"));
+      const chip = document.createElement("span");
+      chip.className = "step-chip done";
+      chip.textContent = label || "完成";
+      container.appendChild(chip);
+      container.scrollLeft = container.scrollWidth;
+    }
+
+    function appendMessage(role, text) {
+      const row = document.createElement("div");
+      row.className = `message-row ${role}`;
+
+      if (role === "assistant") {
+        const img = document.createElement("img");
+        img.className = "avatar";
+        img.src = "微信图片_20260817170012_14_2.png";
+        img.alt = "AI";
+        row.appendChild(img);
+      } else if (role === "user") {
+        const avatar = document.createElement("div");
+        avatar.className = "avatar user-avatar";
+        avatar.textContent = "我";
+        row.appendChild(avatar);
+      }
+
+      const div = document.createElement("div");
+      div.className = `message ${role}`;
+      div.textContent = text || "";
+      row.appendChild(div);
+      chatEl.appendChild(row);
+      chatEl.scrollTop = chatEl.scrollHeight;
+      return div;
+    }
+
+    function appendSystem(text) {
+      return appendMessage("system", text);
+    }
+
+    function appendError(text) {
+      const div = appendMessage("error", text);
+      setStatus("处理失败");
+      return div;
+    }
+
+    function hideConfirm() {
+      confirmPanel.classList.remove("show");
+      $("confirmReply").value = "";
+      $("confirmOptions").innerHTML = "";
+    }
+
+    function showConfirm(message, options) {
+      $("confirmMessage").textContent = message || "请确认查询条件";
+      const box = $("confirmOptions");
+      box.innerHTML = "";
+      (options || []).forEach((opt) => {
+        const chip = document.createElement("span");
+        chip.className = "option-chip";
+        chip.textContent = opt;
+        chip.onclick = () => { $("confirmReply").value = opt; };
+        box.appendChild(chip);
+      });
+      confirmPanel.classList.add("show");
+      $("confirmReply").focus();
+      setStatus("等待人工确认");
+      confirmPanel.scrollIntoView({ behavior: "smooth", block: "center" });
+    }
+
+    function parseSseLine(line) {
+      if (line.startsWith("event: ")) return ["event", line.slice(7).trim()];
+      if (line.startsWith("data: ")) return ["data", line.slice(6)];
+      return null;
+    }
+
+    async function askStream(question, autoConfirm, reuseCheck) {
+      const threadId = getThreadId();
+      const controller = new AbortController();
+      const response = await fetch(`${apiBase()}/ask/stream`, {
+        method: "POST",
+        headers: { "Content-Type": "application/json" },
+        body: JSON.stringify({
+          thread_id: threadId,
+          query: question,
+          auto_confirm: autoConfirm,
+          reuse_check: reuseCheck,
+        }),
+        signal: controller.signal,
+      });
+      if (!response.ok || !response.body) {
+        throw new Error(`HTTP ${response.status}`);
+      }
+
+      const reader = response.body.getReader();
+      const decoder = new TextDecoder();
+      let buffer = "";
+      let event = "";
+      let data = "";
+
+      const assistantRow = document.createElement("div");
+      assistantRow.className = "message-row assistant";
+      const avatar = document.createElement("img");
+      avatar.className = "avatar";
+      avatar.src = "微信图片_20260817170012_14_2.png";
+      avatar.alt = "AI";
+      assistantRow.appendChild(avatar);
+
+      const assistantBubble = document.createElement("div");
+      assistantBubble.className = "message assistant";
+      const progressEl = document.createElement("div");
+      progressEl.className = "progress-flow";
+      activeProgressEl = progressEl;
+      const answerEl = document.createElement("div");
+      answerEl.className = "answer-text";
+      assistantBubble.appendChild(progressEl);
+      assistantBubble.appendChild(answerEl);
+      assistantRow.appendChild(assistantBubble);
+      chatEl.appendChild(assistantRow);
+      chatEl.scrollTop = chatEl.scrollHeight;
+
+      let gotAnswer = false;
+
+      const handleEvent = () => {
+        if (!event) return;
+        if (event === "progress") {
+          try {
+            const payload = JSON.parse(data);
+            addProgressStep(payload.node, payload.label, progressEl);
+            setStatus(payload.label || "处理中");
+          } catch (_) {}
+        } else if (event === "answer_chunk") {
+          try {
+            const payload = JSON.parse(data);
+            if (!gotAnswer) {
+              addProgressStep("answer", "正在生成回答", progressEl);
+              setStatus("正在生成回答");
+            }
+            answerEl.textContent += payload.text || "";
+            chatEl.scrollTop = chatEl.scrollHeight;
+            gotAnswer = true;
+          } catch (_) {}
+        } else if (event === "confirm") {
+          try {
+            const payload = JSON.parse(data);
+            addProgressStep("confirm", "等待人工确认", progressEl);
+            showConfirm(payload.message, payload.options);
+          } catch (_) {}
+        } else if (event === "done") {
+          try {
+            const payload = JSON.parse(data);
+            if (!gotAnswer && payload.answer) {
+              answerEl.textContent = payload.answer;
+            }
+            finishProgressFlow(progressEl, "完成");
+            setStatus(`完成,耗时 ${payload.elapsed_sec || 0} 秒`);
+          } catch (_) {}
+        } else if (event === "error") {
+          try {
+            const payload = JSON.parse(data);
+            assistantBubble.className = "message error";
+            progressEl.style.display = "none";
+            answerEl.textContent = payload.message || "请求失败";
+            finishProgressFlow(progressEl, "失败");
+            progressEl.style.display = "flex";
+            setStatus("处理失败");
+          } catch (_) {}
+        }
+        event = "";
+        data = "";
+      };
+
+      while (true) {
+        const { value, done } = await reader.read();
+        if (done) break;
+        buffer += decoder.decode(value, { stream: true });
+        let idx;
+        while ((idx = buffer.indexOf("\n\n")) >= 0) {
+          const raw = buffer.slice(0, idx);
+          buffer = buffer.slice(idx + 2);
+          const lines = raw.split("\n");
+          event = "";
+          data = "";
+          for (const line of lines) {
+            const parsed = parseSseLine(line);
+            if (!parsed) continue;
+            if (parsed[0] === "event") event = parsed[1];
+            else if (parsed[0] === "data") data = parsed[1];
+          }
+          handleEvent();
+        }
+      }
+      // 处理最后可能没有结尾空行的数据
+      if (buffer.trim()) {
+        const parsed = parseSseLine(buffer.trim());
+        if (parsed) {
+          if (parsed[0] === "event") event = parsed[1];
+          else if (parsed[0] === "data") data = parsed[1];
+          handleEvent();
+        }
+      }
+      return { threadId };
+    }
+
+    async function resumeThread(reply) {
+      const threadId = getThreadId();
+      const res = await fetch(`${apiBase()}/threads/${encodeURIComponent(threadId)}/resume`, {
+        method: "POST",
+        headers: { "Content-Type": "application/json" },
+        body: JSON.stringify({ reply }),
+      });
+      const payload = await res.json();
+      if (payload.status === "need_confirm") {
+        if (activeProgressEl) addProgressStep("confirm", "等待人工确认", activeProgressEl);
+        showConfirm(payload.message, payload.options);
+      } else if (payload.status === "ok") {
+        hideConfirm();
+        if (activeProgressEl) finishProgressFlow(activeProgressEl, "完成");
+        appendMessage("assistant", payload.answer || "");
+        setStatus(`完成,耗时 ${payload.elapsed_sec || 0} 秒`);
+      } else {
+        hideConfirm();
+        if (activeProgressEl) finishProgressFlow(activeProgressEl, "失败");
+        appendError(payload.message || "恢复会话失败");
+      }
+    }
+
+    async function sendQuestion() {
+      const question = questionInput.value.trim();
+      if (!question) return;
+      appendMessage("user", question);
+      questionInput.value = "";
+      hideConfirm();
+      sendBtn.disabled = true;
+      setStatus("正在发送...");
+      try {
+        await askStream(question, autoConfirmInput.checked, reuseCheckInput.checked);
+      } catch (err) {
+        appendError(err.message || String(err));
+      } finally {
+        sendBtn.disabled = false;
+        questionInput.focus();
+      }
+    }
+
+    sendBtn.addEventListener("click", sendQuestion);
+    questionInput.addEventListener("keydown", (e) => {
+      if (e.key === "Enter" && (e.ctrlKey || e.metaKey)) {
+        e.preventDefault();
+        sendQuestion();
+      }
+    });
+
+    $("confirmSendBtn").addEventListener("click", async () => {
+      const btn = $("confirmSendBtn");
+      btn.disabled = true;
+      btn.textContent = "处理中...";
+      const reply = $("confirmReply").value.trim() || "确认";
+      setStatus("正在恢复会话...");
+      try {
+        await resumeThread(reply);
+      } catch (err) {
+        appendError(err.message || String(err));
+      } finally {
+        btn.disabled = false;
+        btn.textContent = "继续";
+      }
+    });
+
+    $("newSessionBtn").addEventListener("click", () => {
+      newThreadId();
+      chatEl.innerHTML = "";
+      hideConfirm();
+      setStatus(`新会话已创建:${getThreadId()}`);
+      appendSystem("已创建新会话。当前 thread_id 会在本浏览器标签页内保持不变。");
+    });
+
+    appendSystem(`当前会话 thread_id:${getThreadId()}`);
+  </script>
+</body>
+</html>

+ 823 - 0
html/knowledge_graph_3d.html

@@ -0,0 +1,823 @@
+<!doctype html>
+<html lang="zh-CN">
+<head>
+  <meta charset="utf-8">
+  <meta name="viewport" content="width=device-width, initial-scale=1">
+  <title>申勤物业元知识图谱 3D</title>
+  <style>
+    :root {
+      --bg: #f4f7fb;
+      --panel: #ffffff;
+      --border: #d9e1ec;
+      --primary: #2f5597;
+      --text: #22303f;
+      --muted: #7a8794;
+    }
+
+    * { box-sizing: border-box; }
+
+    body {
+      margin: 0;
+      font-family: "Microsoft YaHei", "PingFang SC", system-ui, sans-serif;
+      background: var(--bg);
+      color: var(--text);
+      height: 100vh;
+      display: flex;
+      flex-direction: column;
+      overflow: hidden;
+    }
+
+    header {
+      height: 58px;
+      padding: 0 18px;
+      display: flex;
+      align-items: center;
+      gap: 10px;
+      border-bottom: 1px solid var(--border);
+      background: #fff;
+    }
+
+    header h1 {
+      margin: 0;
+      font-size: 18px;
+      color: var(--primary);
+    }
+
+    .spacer { flex: 1; }
+
+    button {
+      border: 1px solid var(--border);
+      background: #fff;
+      border-radius: 9px;
+      padding: 8px 12px;
+      cursor: pointer;
+      font-size: 13px;
+      font-family: inherit;
+    }
+
+    button:hover { background: #eef3fb; }
+
+    .workspace {
+      flex: 1;
+      position: relative;
+      overflow: hidden;
+    }
+
+    #graph3D {
+      position: absolute;
+      inset: 0;
+      background:
+        radial-gradient(circle at 50% 42%, rgba(255, 255, 255, 0.88) 0%, rgba(239, 245, 252, 0.86) 45%, rgba(222, 232, 245, 0.92) 100%),
+        radial-gradient(circle at 16% 18%, rgba(47, 85, 151, 0.16), transparent 32%),
+        radial-gradient(circle at 82% 16%, rgba(14, 116, 144, 0.14), transparent 28%),
+        radial-gradient(circle at 72% 84%, rgba(124, 58, 237, 0.12), transparent 34%),
+        radial-gradient(circle at 25% 78%, rgba(217, 119, 6, 0.08), transparent 30%),
+        linear-gradient(rgba(47, 85, 151, 0.045) 1px, transparent 1px),
+        linear-gradient(90deg, rgba(47, 85, 151, 0.045) 1px, transparent 1px);
+      background-size: auto, auto, auto, auto, auto, 42px 42px, 42px 42px;
+    }
+
+    #graph3D canvas {
+      display: block;
+      cursor: grab;
+    }
+
+    #graph3D canvas:active {
+      cursor: grabbing;
+    }
+
+    #nodePanel {
+      position: absolute;
+      top: 16px;
+      right: 16px;
+      width: 330px;
+      max-height: calc(100% - 32px);
+      overflow: auto;
+      background: var(--panel);
+      border: 1px solid var(--border);
+      border-radius: 14px;
+      box-shadow: 0 14px 36px rgba(35, 48, 63, 0.16);
+      padding: 16px;
+      display: none;
+    }
+
+    #nodePanel.show { display: block; }
+
+    #nodePanel h2 { margin: 0 0 10px; font-size: 20px; color: var(--primary); }
+
+    .meta-list {
+      display: grid;
+      grid-template-columns: 96px 1fr;
+      row-gap: 8px;
+      column-gap: 8px;
+      font-size: 13px;
+    }
+
+    .meta-list dt { color: var(--muted); }
+
+    .meta-list dd {
+      margin: 0;
+      word-break: break-word;
+    }
+
+    .attrs-title {
+      margin: 16px 0 8px;
+      font-size: 14px;
+      color: var(--primary);
+    }
+
+    .attrs {
+      display: flex;
+      flex-wrap: wrap;
+      gap: 7px;
+      margin-top: 0;
+    }
+
+    .attr-tag {
+      background: #eef3fb;
+      color: var(--primary);
+      border: 1px solid #ccdbf5;
+      border-radius: 999px;
+      padding: 5px 9px;
+      font-size: 12px;
+    }
+
+    #errorOverlay {
+      position: absolute;
+      inset: 0;
+      display: none;
+      align-items: center;
+      justify-content: center;
+      color: #c0392b;
+      background: rgba(244, 247, 251, 0.94);
+      font-size: 15px;
+      text-align: center;
+      padding: 24px;
+    }
+
+    #errorOverlay.show { display: flex; }
+
+    .chat-dock {
+      position: absolute;
+      right: 18px;
+      bottom: 18px;
+      width: 430px;
+      height: 620px;
+      max-width: calc(100% - 36px);
+      max-height: calc(100% - 36px);
+      display: flex;
+      flex-direction: column;
+      background: #ffffff;
+      border: 1px solid var(--border);
+      border-radius: 16px;
+      box-shadow: 0 18px 50px rgba(35, 48, 63, 0.18);
+      overflow: hidden;
+    }
+
+    .chat-resize-handle {
+      position: absolute;
+      z-index: 6;
+      touch-action: none;
+      user-select: none;
+      -webkit-user-select: none;
+    }
+
+    .chat-resize-handle.nw { top: 0; left: 0; width: 16px; height: 16px; cursor: nwse-resize; }
+    .chat-resize-handle.n { top: 0; left: 20px; right: 20px; height: 8px; cursor: ns-resize; }
+    .chat-resize-handle.ne { top: 0; right: 0; width: 16px; height: 16px; cursor: nesw-resize; }
+    .chat-resize-handle.e { top: 20px; right: 0; bottom: 20px; width: 8px; cursor: ew-resize; }
+    .chat-resize-handle.se { bottom: 0; right: 0; width: 16px; height: 16px; cursor: nwse-resize; }
+    .chat-resize-handle.s { bottom: 0; left: 20px; right: 20px; height: 8px; cursor: ns-resize; }
+    .chat-resize-handle.sw { bottom: 0; left: 0; width: 16px; height: 16px; cursor: nesw-resize; }
+    .chat-resize-handle.w { top: 20px; left: 0; bottom: 20px; width: 8px; cursor: ew-resize; }
+
+    .chat-dock.collapsed {
+      display: none;
+    }
+
+    .chat-fab {
+      position: absolute;
+      right: 18px;
+      bottom: 18px;
+      width: 58px;
+      height: 58px;
+      border-radius: 50%;
+      border: 2px solid var(--primary);
+      padding: 0;
+      overflow: hidden;
+      cursor: pointer;
+      box-shadow: 0 10px 24px rgba(35, 48, 63, 0.22);
+      z-index: 7;
+      display: none;
+    }
+
+    .chat-fab.show {
+      display: block;
+    }
+
+    .chat-fab img {
+      width: 100%;
+      height: 100%;
+      object-fit: cover;
+      display: block;
+    }
+
+    .chat-dock.collapsed .chat-resize-handle {
+      display: none;
+    }
+
+    .chat-dock-header {
+      height: 42px;
+      padding: 0 24px;
+      display: flex;
+      align-items: center;
+      gap: 8px;
+      background: var(--primary);
+      color: #fff;
+      font-size: 14px;
+      cursor: move;
+      user-select: none;
+      -webkit-user-select: none;
+      touch-action: none;
+    }
+
+    .chat-dock-header .spacer { flex: 1; }
+
+    .chat-toggle {
+      background: rgba(255, 255, 255, 0.15);
+      color: #fff;
+      border: 1px solid rgba(255, 255, 255, 0.28);
+      padding: 5px 9px;
+      border-radius: 8px;
+      cursor: pointer;
+    }
+
+    #chatFrame {
+      flex: 1;
+      border: 0;
+      display: block;
+    }
+
+    .chat-dock.collapsed #chatFrame {
+      display: none;
+    }
+  </style>
+</head>
+<body>
+  <header>
+    <h1>申勤物业元知识图谱 3D</h1>
+    <div class="spacer"></div>
+    <button id="resetBtn">重置视角</button>
+    <button onclick="location.href='index.html'">返回聊天</button>
+  </header>
+
+  <div class="workspace">
+    <div id="graph3D"></div>
+    <div id="errorOverlay"></div>
+
+    <aside id="nodePanel">
+      <h2 id="panelTitle"></h2>
+      <dl class="meta-list" id="panelMeta"></dl>
+      <h3 class="attrs-title">属性</h3>
+      <div class="attrs" id="panelAttrs"></div>
+    </aside>
+
+    <button id="chatFab" class="chat-fab" title="展开聊天窗口">
+      <img src="微信图片_20260817170012_14_2.png" alt="打开聊天" />
+    </button>
+
+    <div id="chatDock" class="chat-dock">
+      <div class="chat-resize-handle nw" data-resize="nw" title="缩放"></div>
+      <div class="chat-resize-handle n" data-resize="n" title="上下缩放"></div>
+      <div class="chat-resize-handle ne" data-resize="ne" title="缩放"></div>
+      <div class="chat-resize-handle e" data-resize="e" title="左右缩放"></div>
+      <div class="chat-resize-handle se" data-resize="se" title="缩放"></div>
+      <div class="chat-resize-handle s" data-resize="s" title="上下缩放"></div>
+      <div class="chat-resize-handle sw" data-resize="sw" title="缩放"></div>
+      <div class="chat-resize-handle w" data-resize="w" title="左右缩放"></div>
+      <div class="chat-dock-header">
+        <span>申勤物业知识助手</span>
+        <div class="spacer"></div>
+        <button id="chatToggle" class="chat-toggle">收起</button>
+      </div>
+      <iframe id="chatFrame" src="index.html" title="申勤物业知识助手"></iframe>
+    </div>
+  </div>
+
+  <script src="vendor/three.min.js"></script>
+  <script src="vendor/OrbitControls.js"></script>
+  <script>
+    const $ = (id) => document.getElementById(id);
+    const container = $("graph3D");
+    const nodePanel = $("nodePanel");
+    const panelTitle = $("panelTitle");
+    const panelMeta = $("panelMeta");
+    const panelAttrs = $("panelAttrs");
+    const chatDock = $("chatDock");
+    const chatToggle = $("chatToggle");
+    const errorOverlay = $("errorOverlay");
+    const chatResizeHandles = Array.from(document.querySelectorAll(".chat-resize-handle"));
+    const chatHeader = document.querySelector(".chat-dock-header");
+    const chatFab = $("chatFab");
+    let resizeState = null;
+    let chatDragState = null;
+
+    const departmentColors = {
+      "市场部": "#d97706",
+      "人事部": "#7c3aed",
+      "运营部": "#2f855a",
+      "财务部": "#c0392b",
+      "采购部": "#0e7490",
+    };
+    const fallbackColors = ["#4c78a8", "#b45309", "#6d28d9", "#15803d", "#be123c", "#0369a1", "#b45309"];
+
+    function apiBase() {
+      if (location.protocol === "http:" || location.protocol === "https:") {
+        return location.origin;
+      }
+      return "http://127.0.0.1:8000";
+    }
+
+    function showError(message) {
+      errorOverlay.textContent = message;
+      errorOverlay.classList.add("show");
+    }
+
+    function colorForNode(node) {
+      const department = Array.isArray(node.department) && node.department.length
+        ? node.department[0]
+        : "未分类";
+      const known = departmentColors[department];
+      if (known) return known;
+
+      let hash = 0;
+      const key = String(node.id || node.name || "");
+      for (let i = 0; i < key.length; i += 1) {
+        hash = (hash * 31 + key.charCodeAt(i)) >>> 0;
+      }
+      return fallbackColors[hash % fallbackColors.length];
+    }
+
+    function hexToNumber(hex) {
+      return parseInt(hex.slice(1), 16);
+    }
+
+    function showNode(node) {
+      panelTitle.textContent = node.name;
+      panelMeta.innerHTML = "";
+      const attributes = node.attributes || [];
+      const meta = [
+        ["所属部门", (node.department || []).join("、")],
+        ["是否中心节点", node.is_hub ? "是" : "否"],
+        ["是否启用", node.active ? "是" : "否"],
+        ["是否建议节点", node.suggested ? "是" : "否"],
+        ["属性数量", String(attributes.length)],
+      ];
+      const description = (node.description || "").trim();
+      const attributesText = attributes.join(" / ");
+      if (description && description.replace(/\s+/g, "") !== attributesText.replace(/\s+/g, "")) {
+        meta.push(["说明", description]);
+      }
+      meta.forEach(([k, v]) => {
+        const dt = document.createElement("dt");
+        dt.textContent = k;
+        const dd = document.createElement("dd");
+        dd.textContent = v;
+        panelMeta.appendChild(dt);
+        panelMeta.appendChild(dd);
+      });
+      panelAttrs.innerHTML = "";
+      if (!attributes.length) {
+        const empty = document.createElement("span");
+        empty.className = "attr-tag";
+        empty.textContent = "暂无属性";
+        panelAttrs.appendChild(empty);
+      } else {
+        attributes.forEach((attr) => {
+          const tag = document.createElement("span");
+          tag.className = "attr-tag";
+          tag.textContent = attr;
+          tag.title = attr;
+          panelAttrs.appendChild(tag);
+        });
+      }
+      nodePanel.classList.add("show");
+    }
+
+    function init() {
+      if (typeof THREE === "undefined" || typeof THREE.OrbitControls === "undefined") {
+        showError("3D 渲染库加载失败,请确认 html/vendor 目录下的 three.min.js 和 OrbitControls.js 存在。");
+        return;
+      }
+
+      const scene = new THREE.Scene();
+      const camera = new THREE.PerspectiveCamera(
+        50,
+        container.clientWidth / Math.max(container.clientHeight, 1),
+        0.1,
+        5000,
+      );
+      camera.position.set(0, 180, 780);
+
+      const renderer = new THREE.WebGLRenderer({ antialias: true, alpha: true });
+      renderer.setPixelRatio(Math.min(window.devicePixelRatio || 1, 2));
+      renderer.setSize(container.clientWidth, container.clientHeight);
+      renderer.setClearColor(0xf4f7fb, 0);
+      container.appendChild(renderer.domElement);
+
+      const controls = new THREE.OrbitControls(camera, renderer.domElement);
+      controls.enableDamping = true;
+      controls.dampingFactor = 0.08;
+      controls.minDistance = 240;
+      controls.maxDistance = 1500;
+      controls.autoRotate = true;
+      controls.autoRotateSpeed = 0.75;
+      controls.target.set(0, 0, 0);
+
+      const ambient = new THREE.AmbientLight(0xffffff, 0.78);
+      scene.add(ambient);
+
+      const keyLight = new THREE.DirectionalLight(0xffffff, 1.0);
+      keyLight.position.set(360, 520, 520);
+      scene.add(keyLight);
+
+      const fillLight = new THREE.DirectionalLight(0xffffff, 0.35);
+      fillLight.position.set(-420, -180, -360);
+      scene.add(fillLight);
+
+      const graphGroup = new THREE.Group();
+      scene.add(graphGroup);
+
+      const nodeMeshes = new Map();
+      const edgeItems = [];
+
+      function buildLayout(nodes) {
+        const positions = new Map();
+        const n = nodes.length || 1;
+        const R = 290;
+        const goldenAngle = Math.PI * (3 - Math.sqrt(5));
+
+        nodes.forEach((node, i) => {
+          let y;
+          let radiusAtY;
+          if (n === 1) {
+            y = 0;
+            radiusAtY = 1;
+          } else {
+            y = 1 - (i / (n - 1)) * 2;
+            radiusAtY = Math.sqrt(Math.max(0, 1 - y * y));
+          }
+          const theta = goldenAngle * i;
+          positions.set(node.id, new THREE.Vector3(
+            Math.cos(theta) * radiusAtY * R,
+            y * R * 0.72,
+            Math.sin(theta) * radiusAtY * R,
+          ));
+        });
+
+        return positions;
+      }
+
+      function makeTextSprite(text, options) {
+        const opts = options || {};
+        const width = opts.width || 256;
+        const height = opts.height || 64;
+        const canvas = document.createElement("canvas");
+        canvas.width = width;
+        canvas.height = height;
+        const ctx = canvas.getContext("2d");
+        ctx.clearRect(0, 0, width, height);
+        ctx.font = `${opts.weight || 600} ${opts.fontSize || 28}px "Microsoft YaHei", "PingFang SC", sans-serif`;
+        ctx.textAlign = "center";
+        ctx.textBaseline = "middle";
+        ctx.lineWidth = opts.strokeWidth || 6;
+        ctx.strokeStyle = opts.stroke || "rgba(255, 255, 255, 0.95)";
+        ctx.strokeText(text, width / 2, height / 2);
+        ctx.fillStyle = opts.color || "#1f2a3a";
+        ctx.fillText(text, width / 2, height / 2);
+
+        const texture = new THREE.CanvasTexture(canvas);
+        texture.minFilter = THREE.LinearFilter;
+        const material = new THREE.SpriteMaterial({
+          map: texture,
+          depthTest: false,
+          depthWrite: false,
+          transparent: true,
+        });
+        const sprite = new THREE.Sprite(material);
+        sprite.scale.set(opts.scaleX || 120, opts.scaleY || 30, 1);
+        return sprite;
+      }
+
+      function selfLoopPoints(position, offset) {
+        const points = [];
+        const steps = 72;
+        for (let i = 0; i <= steps; i += 1) {
+          const angle = (Math.PI * 2 * i) / steps;
+          points.push(new THREE.Vector3(
+            position.x + Math.cos(angle) * 22,
+            position.y + offset,
+            position.z + Math.sin(angle) * 22,
+          ));
+        }
+        return points;
+      }
+
+      function buildGraph(data) {
+        const nodes = data?.nodes || [];
+        const relations = data?.relations || [];
+        const positions = buildLayout(nodes);
+        const edgeMaterial = new THREE.LineBasicMaterial({
+          color: 0x8fa3c0,
+          transparent: true,
+          opacity: 0.52,
+        });
+
+        const selfLoopCounts = {};
+        relations.forEach((rel) => {
+          const a = positions.get(rel.source);
+          const b = positions.get(rel.target);
+          if (!a || !b) return;
+
+          if (rel.source === rel.target) {
+            const count = selfLoopCounts[rel.source] || 0;
+            selfLoopCounts[rel.source] = count + 1;
+            const offset = 34 + count * 22;
+            const geometry = new THREE.BufferGeometry().setFromPoints(selfLoopPoints(a, offset));
+            const line = new THREE.Line(geometry, edgeMaterial);
+            graphGroup.add(line);
+            const label = makeTextSprite(rel.type, {
+              fontSize: 20,
+              color: "#1f2a3a",
+              stroke: "rgba(244, 247, 251, 0.95)",
+              strokeWidth: 5,
+              scaleX: 82,
+              scaleY: 20,
+            });
+            label.position.set(a.x, a.y + offset + 12, a.z);
+            graphGroup.add(label);
+            edgeItems.push({ line, label, a, b, self: true, offset });
+          } else {
+            const geometry = new THREE.BufferGeometry().setFromPoints([a, b]);
+            const line = new THREE.Line(geometry, edgeMaterial);
+            graphGroup.add(line);
+            const mid = new THREE.Vector3().addVectors(a, b).multiplyScalar(0.5);
+            const label = makeTextSprite(rel.type, {
+              fontSize: 20,
+              color: "#1f2a3a",
+              stroke: "rgba(244, 247, 251, 0.95)",
+              strokeWidth: 5,
+              scaleX: 82,
+              scaleY: 20,
+            });
+            label.position.copy(mid);
+            graphGroup.add(label);
+            edgeItems.push({ line, label, a, b, self: false, offset: 0 });
+          }
+        });
+
+        const sphereGeometry = new THREE.SphereGeometry(1, 40, 28);
+        nodes.forEach((node) => {
+          const p = positions.get(node.id);
+          if (!p) return;
+          const radius = node.is_hub ? 22 : 14;
+          const material = new THREE.MeshPhongMaterial({
+            color: hexToNumber(colorForNode(node)),
+            emissive: new THREE.Color(hexToNumber(colorForNode(node))).multiplyScalar(0.16),
+            shininess: 28,
+            specular: 0x556677,
+          });
+          const mesh = new THREE.Mesh(sphereGeometry, material);
+          mesh.position.copy(p);
+          mesh.scale.setScalar(radius);
+          mesh.userData = { node };
+          graphGroup.add(mesh);
+          nodeMeshes.set(node.id, mesh);
+
+          const label = makeTextSprite(node.name, {
+            fontSize: 28,
+            color: "#1f2a3a",
+            stroke: "rgba(255, 255, 255, 0.95)",
+            strokeWidth: 6,
+            scaleX: 132,
+            scaleY: 34,
+          });
+          label.position.set(p.x, p.y + radius + 18, p.z);
+          graphGroup.add(label);
+        });
+      }
+
+      const raycaster = new THREE.Raycaster();
+      const pointer = new THREE.Vector2();
+      let pointerDown = null;
+
+      function pickNode(event) {
+        const rect = renderer.domElement.getBoundingClientRect();
+        pointer.x = ((event.clientX - rect.left) / rect.width) * 2 - 1;
+        pointer.y = -((event.clientY - rect.top) / rect.height) * 2 + 1;
+        raycaster.setFromCamera(pointer, camera);
+        const hits = raycaster.intersectObjects(Array.from(nodeMeshes.values()), false);
+        if (hits.length) {
+          showNode(hits[0].object.userData.node);
+        }
+      }
+
+      renderer.domElement.addEventListener("pointerdown", (event) => {
+        pointerDown = { x: event.clientX, y: event.clientY };
+      });
+
+      renderer.domElement.addEventListener("pointerup", (event) => {
+        if (!pointerDown) return;
+        const moved = Math.hypot(event.clientX - pointerDown.x, event.clientY - pointerDown.y);
+        pointerDown = null;
+        if (moved < 6) pickNode(event);
+      });
+
+      renderer.domElement.addEventListener("pointermove", (event) => {
+        const rect = renderer.domElement.getBoundingClientRect();
+        pointer.x = ((event.clientX - rect.left) / rect.width) * 2 - 1;
+        pointer.y = -((event.clientY - rect.top) / rect.height) * 2 + 1;
+        raycaster.setFromCamera(pointer, camera);
+        const hits = raycaster.intersectObjects(Array.from(nodeMeshes.values()), false);
+        renderer.domElement.style.cursor = hits.length ? "pointer" : "grab";
+      });
+
+      $("resetBtn").addEventListener("click", () => {
+        camera.position.set(0, 180, 780);
+        controls.target.set(0, 0, 0);
+        controls.update();
+      });
+
+      window.addEventListener("resize", () => {
+        const width = container.clientWidth;
+        const height = container.clientHeight;
+        camera.aspect = width / Math.max(height, 1);
+        camera.updateProjectionMatrix();
+        renderer.setSize(width, height);
+      });
+
+      async function load() {
+        const res = await fetch(`${apiBase()}/output/meta_graph_schema_display.json`);
+        if (!res.ok) throw new Error(`HTTP ${res.status}`);
+        const data = await res.json();
+        buildGraph(data);
+      }
+
+      load().catch((err) => {
+        showError(`图谱加载失败:${err.message}`);
+      });
+
+      function animate() {
+        requestAnimationFrame(animate);
+        controls.update();
+        renderer.render(scene, camera);
+      }
+      animate();
+    }
+
+    function ensureDockPosition() {
+      const workspace = chatDock.parentElement;
+      const dockRect = chatDock.getBoundingClientRect();
+      const workspaceRect = workspace.getBoundingClientRect();
+      const left = dockRect.left - workspaceRect.left;
+      const top = dockRect.top - workspaceRect.top;
+      setDockPosition(left, top);
+      return { left, top };
+    }
+
+    function endChatResize(e) {
+      if (!resizeState) return;
+      const handle = resizeState.handle;
+      resizeState = null;
+      if (e && handle && handle.hasPointerCapture && handle.hasPointerCapture(e.pointerId)) {
+        handle.releasePointerCapture(e.pointerId);
+      }
+    }
+
+    chatResizeHandles.forEach((handle) => {
+      handle.addEventListener("pointerdown", (e) => {
+        if (chatDock.classList.contains("collapsed")) return;
+        const position = ensureDockPosition();
+        resizeState = {
+          handle,
+          direction: handle.getAttribute("data-resize") || "",
+          pointerId: e.pointerId,
+          startX: e.clientX,
+          startY: e.clientY,
+          startLeft: position.left,
+          startTop: position.top,
+          startWidth: chatDock.offsetWidth,
+          startHeight: chatDock.offsetHeight,
+        };
+        handle.setPointerCapture(e.pointerId);
+        if (e.cancelable) e.preventDefault();
+      });
+
+      handle.addEventListener("pointermove", (e) => {
+        if (!resizeState || resizeState.handle !== handle || e.pointerId !== resizeState.pointerId) return;
+        if (e.cancelable) e.preventDefault();
+        const workspace = chatDock.parentElement;
+        const direction = resizeState.direction;
+        const minWidth = 280;
+        const minHeight = 320;
+        let left = resizeState.startLeft;
+        let top = resizeState.startTop;
+        let width = resizeState.startWidth;
+        let height = resizeState.startHeight;
+        const dx = e.clientX - resizeState.startX;
+        const dy = e.clientY - resizeState.startY;
+
+        if (direction.includes("e")) {
+          width = Math.min(workspace.clientWidth - resizeState.startLeft, Math.max(minWidth, resizeState.startWidth + dx));
+        }
+        if (direction.includes("w")) {
+          width = Math.min(resizeState.startLeft + resizeState.startWidth, Math.max(minWidth, resizeState.startWidth - dx));
+          left = resizeState.startLeft + resizeState.startWidth - width;
+        }
+        if (direction.includes("s")) {
+          height = Math.min(workspace.clientHeight - resizeState.startTop, Math.max(minHeight, resizeState.startHeight + dy));
+        }
+        if (direction.includes("n")) {
+          height = Math.min(resizeState.startTop + resizeState.startHeight, Math.max(minHeight, resizeState.startHeight - dy));
+          top = resizeState.startTop + resizeState.startHeight - height;
+        }
+
+        chatDock.style.left = `${left}px`;
+        chatDock.style.top = `${top}px`;
+        chatDock.style.width = `${width}px`;
+        chatDock.style.height = `${height}px`;
+      });
+
+      handle.addEventListener("pointerup", endChatResize);
+      handle.addEventListener("pointercancel", endChatResize);
+      handle.addEventListener("lostpointercapture", endChatResize);
+    });
+
+    function setDockPosition(left, top) {
+      chatDock.style.left = `${left}px`;
+      chatDock.style.top = `${top}px`;
+      chatDock.style.right = "auto";
+      chatDock.style.bottom = "auto";
+    }
+
+    function endChatDrag(e) {
+      if (!chatDragState) return;
+      chatDragState = null;
+      if (e && chatHeader.hasPointerCapture && chatHeader.hasPointerCapture(e.pointerId)) {
+        chatHeader.releasePointerCapture(e.pointerId);
+      }
+    }
+
+    chatHeader.addEventListener("pointerdown", (e) => {
+      if (e.target.closest("button")) return;
+      const workspace = chatDock.parentElement;
+      const dockRect = chatDock.getBoundingClientRect();
+      const workspaceRect = workspace.getBoundingClientRect();
+      const left = dockRect.left - workspaceRect.left;
+      const top = dockRect.top - workspaceRect.top;
+      setDockPosition(left, top);
+      chatDragState = {
+        pointerId: e.pointerId,
+        startX: e.clientX,
+        startY: e.clientY,
+        originLeft: left,
+        originTop: top,
+      };
+      chatHeader.setPointerCapture(e.pointerId);
+      if (e.cancelable) e.preventDefault();
+    });
+
+    chatHeader.addEventListener("pointermove", (e) => {
+      if (!chatDragState || e.pointerId !== chatDragState.pointerId) return;
+      if (e.cancelable) e.preventDefault();
+      const workspace = chatDock.parentElement;
+      const maxLeft = Math.max(0, workspace.clientWidth - chatDock.offsetWidth);
+      const maxTop = Math.max(0, workspace.clientHeight - chatDock.offsetHeight);
+      const left = Math.min(maxLeft, Math.max(0, chatDragState.originLeft + (e.clientX - chatDragState.startX)));
+      const top = Math.min(maxTop, Math.max(0, chatDragState.originTop + (e.clientY - chatDragState.startY)));
+      chatDock.style.left = `${left}px`;
+      chatDock.style.top = `${top}px`;
+    });
+
+    chatHeader.addEventListener("pointerup", endChatDrag);
+    chatHeader.addEventListener("pointercancel", endChatDrag);
+    chatHeader.addEventListener("lostpointercapture", endChatDrag);
+
+    function setChatCollapsed(collapsed) {
+      chatDock.classList.toggle("collapsed", collapsed);
+      chatFab.classList.toggle("show", collapsed);
+      chatToggle.textContent = collapsed ? "展开" : "收起";
+    }
+
+    chatToggle.addEventListener("click", () => {
+      setChatCollapsed(!chatDock.classList.contains("collapsed"));
+    });
+
+    chatFab.addEventListener("click", () => {
+      setChatCollapsed(false);
+    });
+
+    init();
+  </script>
+</body>
+</html>

+ 1045 - 0
html/vendor/OrbitControls.js

@@ -0,0 +1,1045 @@
+( function () {
+
+	// Unlike TrackballControls, it maintains the "up" direction object.up (+Y by default).
+	//
+	//    Orbit - left mouse / touch: one-finger move
+	//    Zoom - middle mouse, or mousewheel / touch: two-finger spread or squish
+	//    Pan - right mouse, or left mouse + ctrl/meta/shiftKey, or arrow keys / touch: two-finger move
+
+	const _changeEvent = {
+		type: 'change'
+	};
+	const _startEvent = {
+		type: 'start'
+	};
+	const _endEvent = {
+		type: 'end'
+	};
+
+	class OrbitControls extends THREE.EventDispatcher {
+
+		constructor( object, domElement ) {
+
+			super();
+			if ( domElement === undefined ) console.warn( 'THREE.OrbitControls: The second parameter "domElement" is now mandatory.' );
+			if ( domElement === document ) console.error( 'THREE.OrbitControls: "document" should not be used as the target "domElement". Please use "renderer.domElement" instead.' );
+			this.object = object;
+			this.domElement = domElement; // Set to false to disable this control
+
+			this.enabled = true; // "target" sets the location of focus, where the object orbits around
+
+			this.target = new THREE.Vector3(); // How far you can dolly in and out ( PerspectiveCamera only )
+
+			this.minDistance = 0;
+			this.maxDistance = Infinity; // How far you can zoom in and out ( OrthographicCamera only )
+
+			this.minZoom = 0;
+			this.maxZoom = Infinity; // How far you can orbit vertically, upper and lower limits.
+			// Range is 0 to Math.PI radians.
+
+			this.minPolarAngle = 0; // radians
+
+			this.maxPolarAngle = Math.PI; // radians
+			// How far you can orbit horizontally, upper and lower limits.
+			// If set, the interval [ min, max ] must be a sub-interval of [ - 2 PI, 2 PI ], with ( max - min < 2 PI )
+
+			this.minAzimuthAngle = - Infinity; // radians
+
+			this.maxAzimuthAngle = Infinity; // radians
+			// Set to true to enable damping (inertia)
+			// If damping is enabled, you must call controls.update() in your animation loop
+
+			this.enableDamping = false;
+			this.dampingFactor = 0.05; // This option actually enables dollying in and out; left as "zoom" for backwards compatibility.
+			// Set to false to disable zooming
+
+			this.enableZoom = true;
+			this.zoomSpeed = 1.0; // Set to false to disable rotating
+
+			this.enableRotate = true;
+			this.rotateSpeed = 1.0; // Set to false to disable panning
+
+			this.enablePan = true;
+			this.panSpeed = 1.0;
+			this.screenSpacePanning = true; // if false, pan orthogonal to world-space direction camera.up
+
+			this.keyPanSpeed = 7.0; // pixels moved per arrow key push
+			// Set to true to automatically rotate around the target
+			// If auto-rotate is enabled, you must call controls.update() in your animation loop
+
+			this.autoRotate = false;
+			this.autoRotateSpeed = 2.0; // 30 seconds per orbit when fps is 60
+			// The four arrow keys
+
+			this.keys = {
+				LEFT: 'ArrowLeft',
+				UP: 'ArrowUp',
+				RIGHT: 'ArrowRight',
+				BOTTOM: 'ArrowDown'
+			}; // Mouse buttons
+
+			this.mouseButtons = {
+				LEFT: THREE.MOUSE.ROTATE,
+				MIDDLE: THREE.MOUSE.DOLLY,
+				RIGHT: THREE.MOUSE.PAN
+			}; // Touch fingers
+
+			this.touches = {
+				ONE: THREE.TOUCH.ROTATE,
+				TWO: THREE.TOUCH.DOLLY_PAN
+			}; // for reset
+
+			this.target0 = this.target.clone();
+			this.position0 = this.object.position.clone();
+			this.zoom0 = this.object.zoom; // the target DOM element for key events
+
+			this._domElementKeyEvents = null; //
+			// public methods
+			//
+
+			this.getPolarAngle = function () {
+
+				return spherical.phi;
+
+			};
+
+			this.getAzimuthalAngle = function () {
+
+				return spherical.theta;
+
+			};
+
+			this.listenToKeyEvents = function ( domElement ) {
+
+				domElement.addEventListener( 'keydown', onKeyDown );
+				this._domElementKeyEvents = domElement;
+
+			};
+
+			this.saveState = function () {
+
+				scope.target0.copy( scope.target );
+				scope.position0.copy( scope.object.position );
+				scope.zoom0 = scope.object.zoom;
+
+			};
+
+			this.reset = function () {
+
+				scope.target.copy( scope.target0 );
+				scope.object.position.copy( scope.position0 );
+				scope.object.zoom = scope.zoom0;
+				scope.object.updateProjectionMatrix();
+				scope.dispatchEvent( _changeEvent );
+				scope.update();
+				state = STATE.NONE;
+
+			}; // this method is exposed, but perhaps it would be better if we can make it private...
+
+
+			this.update = function () {
+
+				const offset = new THREE.Vector3(); // so camera.up is the orbit axis
+
+				const quat = new THREE.Quaternion().setFromUnitVectors( object.up, new THREE.Vector3( 0, 1, 0 ) );
+				const quatInverse = quat.clone().invert();
+				const lastPosition = new THREE.Vector3();
+				const lastQuaternion = new THREE.Quaternion();
+				const twoPI = 2 * Math.PI;
+				return function update() {
+
+					const position = scope.object.position;
+					offset.copy( position ).sub( scope.target ); // rotate offset to "y-axis-is-up" space
+
+					offset.applyQuaternion( quat ); // angle from z-axis around y-axis
+
+					spherical.setFromVector3( offset );
+
+					if ( scope.autoRotate && state === STATE.NONE ) {
+
+						rotateLeft( getAutoRotationAngle() );
+
+					}
+
+					if ( scope.enableDamping ) {
+
+						spherical.theta += sphericalDelta.theta * scope.dampingFactor;
+						spherical.phi += sphericalDelta.phi * scope.dampingFactor;
+
+					} else {
+
+						spherical.theta += sphericalDelta.theta;
+						spherical.phi += sphericalDelta.phi;
+
+					} // restrict theta to be between desired limits
+
+
+					let min = scope.minAzimuthAngle;
+					let max = scope.maxAzimuthAngle;
+
+					if ( isFinite( min ) && isFinite( max ) ) {
+
+						if ( min < - Math.PI ) min += twoPI; else if ( min > Math.PI ) min -= twoPI;
+						if ( max < - Math.PI ) max += twoPI; else if ( max > Math.PI ) max -= twoPI;
+
+						if ( min <= max ) {
+
+							spherical.theta = Math.max( min, Math.min( max, spherical.theta ) );
+
+						} else {
+
+							spherical.theta = spherical.theta > ( min + max ) / 2 ? Math.max( min, spherical.theta ) : Math.min( max, spherical.theta );
+
+						}
+
+					} // restrict phi to be between desired limits
+
+
+					spherical.phi = Math.max( scope.minPolarAngle, Math.min( scope.maxPolarAngle, spherical.phi ) );
+					spherical.makeSafe();
+					spherical.radius *= scale; // restrict radius to be between desired limits
+
+					spherical.radius = Math.max( scope.minDistance, Math.min( scope.maxDistance, spherical.radius ) ); // move target to panned location
+
+					if ( scope.enableDamping === true ) {
+
+						scope.target.addScaledVector( panOffset, scope.dampingFactor );
+
+					} else {
+
+						scope.target.add( panOffset );
+
+					}
+
+					offset.setFromSpherical( spherical ); // rotate offset back to "camera-up-vector-is-up" space
+
+					offset.applyQuaternion( quatInverse );
+					position.copy( scope.target ).add( offset );
+					scope.object.lookAt( scope.target );
+
+					if ( scope.enableDamping === true ) {
+
+						sphericalDelta.theta *= 1 - scope.dampingFactor;
+						sphericalDelta.phi *= 1 - scope.dampingFactor;
+						panOffset.multiplyScalar( 1 - scope.dampingFactor );
+
+					} else {
+
+						sphericalDelta.set( 0, 0, 0 );
+						panOffset.set( 0, 0, 0 );
+
+					}
+
+					scale = 1; // update condition is:
+					// min(camera displacement, camera rotation in radians)^2 > EPS
+					// using small-angle approximation cos(x/2) = 1 - x^2 / 8
+
+					if ( zoomChanged || lastPosition.distanceToSquared( scope.object.position ) > EPS || 8 * ( 1 - lastQuaternion.dot( scope.object.quaternion ) ) > EPS ) {
+
+						scope.dispatchEvent( _changeEvent );
+						lastPosition.copy( scope.object.position );
+						lastQuaternion.copy( scope.object.quaternion );
+						zoomChanged = false;
+						return true;
+
+					}
+
+					return false;
+
+				};
+
+			}();
+
+			this.dispose = function () {
+
+				scope.domElement.removeEventListener( 'contextmenu', onContextMenu );
+				scope.domElement.removeEventListener( 'pointerdown', onPointerDown );
+				scope.domElement.removeEventListener( 'wheel', onMouseWheel );
+				scope.domElement.removeEventListener( 'touchstart', onTouchStart );
+				scope.domElement.removeEventListener( 'touchend', onTouchEnd );
+				scope.domElement.removeEventListener( 'touchmove', onTouchMove );
+				scope.domElement.ownerDocument.removeEventListener( 'pointermove', onPointerMove );
+				scope.domElement.ownerDocument.removeEventListener( 'pointerup', onPointerUp );
+
+				if ( scope._domElementKeyEvents !== null ) {
+
+					scope._domElementKeyEvents.removeEventListener( 'keydown', onKeyDown );
+
+				} //scope.dispatchEvent( { type: 'dispose' } ); // should this be added here?
+
+			}; //
+			// internals
+			//
+
+
+			const scope = this;
+			const STATE = {
+				NONE: - 1,
+				ROTATE: 0,
+				DOLLY: 1,
+				PAN: 2,
+				TOUCH_ROTATE: 3,
+				TOUCH_PAN: 4,
+				TOUCH_DOLLY_PAN: 5,
+				TOUCH_DOLLY_ROTATE: 6
+			};
+			let state = STATE.NONE;
+			const EPS = 0.000001; // current position in spherical coordinates
+
+			const spherical = new THREE.Spherical();
+			const sphericalDelta = new THREE.Spherical();
+			let scale = 1;
+			const panOffset = new THREE.Vector3();
+			let zoomChanged = false;
+			const rotateStart = new THREE.Vector2();
+			const rotateEnd = new THREE.Vector2();
+			const rotateDelta = new THREE.Vector2();
+			const panStart = new THREE.Vector2();
+			const panEnd = new THREE.Vector2();
+			const panDelta = new THREE.Vector2();
+			const dollyStart = new THREE.Vector2();
+			const dollyEnd = new THREE.Vector2();
+			const dollyDelta = new THREE.Vector2();
+
+			function getAutoRotationAngle() {
+
+				return 2 * Math.PI / 60 / 60 * scope.autoRotateSpeed;
+
+			}
+
+			function getZoomScale() {
+
+				return Math.pow( 0.95, scope.zoomSpeed );
+
+			}
+
+			function rotateLeft( angle ) {
+
+				sphericalDelta.theta -= angle;
+
+			}
+
+			function rotateUp( angle ) {
+
+				sphericalDelta.phi -= angle;
+
+			}
+
+			const panLeft = function () {
+
+				const v = new THREE.Vector3();
+				return function panLeft( distance, objectMatrix ) {
+
+					v.setFromMatrixColumn( objectMatrix, 0 ); // get X column of objectMatrix
+
+					v.multiplyScalar( - distance );
+					panOffset.add( v );
+
+				};
+
+			}();
+
+			const panUp = function () {
+
+				const v = new THREE.Vector3();
+				return function panUp( distance, objectMatrix ) {
+
+					if ( scope.screenSpacePanning === true ) {
+
+						v.setFromMatrixColumn( objectMatrix, 1 );
+
+					} else {
+
+						v.setFromMatrixColumn( objectMatrix, 0 );
+						v.crossVectors( scope.object.up, v );
+
+					}
+
+					v.multiplyScalar( distance );
+					panOffset.add( v );
+
+				};
+
+			}(); // deltaX and deltaY are in pixels; right and down are positive
+
+
+			const pan = function () {
+
+				const offset = new THREE.Vector3();
+				return function pan( deltaX, deltaY ) {
+
+					const element = scope.domElement;
+
+					if ( scope.object.isPerspectiveCamera ) {
+
+						// perspective
+						const position = scope.object.position;
+						offset.copy( position ).sub( scope.target );
+						let targetDistance = offset.length(); // half of the fov is center to top of screen
+
+						targetDistance *= Math.tan( scope.object.fov / 2 * Math.PI / 180.0 ); // we use only clientHeight here so aspect ratio does not distort speed
+
+						panLeft( 2 * deltaX * targetDistance / element.clientHeight, scope.object.matrix );
+						panUp( 2 * deltaY * targetDistance / element.clientHeight, scope.object.matrix );
+
+					} else if ( scope.object.isOrthographicCamera ) {
+
+						// orthographic
+						panLeft( deltaX * ( scope.object.right - scope.object.left ) / scope.object.zoom / element.clientWidth, scope.object.matrix );
+						panUp( deltaY * ( scope.object.top - scope.object.bottom ) / scope.object.zoom / element.clientHeight, scope.object.matrix );
+
+					} else {
+
+						// camera neither orthographic nor perspective
+						console.warn( 'WARNING: OrbitControls.js encountered an unknown camera type - pan disabled.' );
+						scope.enablePan = false;
+
+					}
+
+				};
+
+			}();
+
+			function dollyOut( dollyScale ) {
+
+				if ( scope.object.isPerspectiveCamera ) {
+
+					scale /= dollyScale;
+
+				} else if ( scope.object.isOrthographicCamera ) {
+
+					scope.object.zoom = Math.max( scope.minZoom, Math.min( scope.maxZoom, scope.object.zoom * dollyScale ) );
+					scope.object.updateProjectionMatrix();
+					zoomChanged = true;
+
+				} else {
+
+					console.warn( 'WARNING: OrbitControls.js encountered an unknown camera type - dolly/zoom disabled.' );
+					scope.enableZoom = false;
+
+				}
+
+			}
+
+			function dollyIn( dollyScale ) {
+
+				if ( scope.object.isPerspectiveCamera ) {
+
+					scale *= dollyScale;
+
+				} else if ( scope.object.isOrthographicCamera ) {
+
+					scope.object.zoom = Math.max( scope.minZoom, Math.min( scope.maxZoom, scope.object.zoom / dollyScale ) );
+					scope.object.updateProjectionMatrix();
+					zoomChanged = true;
+
+				} else {
+
+					console.warn( 'WARNING: OrbitControls.js encountered an unknown camera type - dolly/zoom disabled.' );
+					scope.enableZoom = false;
+
+				}
+
+			} //
+			// event callbacks - update the object state
+			//
+
+
+			function handleMouseDownRotate( event ) {
+
+				rotateStart.set( event.clientX, event.clientY );
+
+			}
+
+			function handleMouseDownDolly( event ) {
+
+				dollyStart.set( event.clientX, event.clientY );
+
+			}
+
+			function handleMouseDownPan( event ) {
+
+				panStart.set( event.clientX, event.clientY );
+
+			}
+
+			function handleMouseMoveRotate( event ) {
+
+				rotateEnd.set( event.clientX, event.clientY );
+				rotateDelta.subVectors( rotateEnd, rotateStart ).multiplyScalar( scope.rotateSpeed );
+				const element = scope.domElement;
+				rotateLeft( 2 * Math.PI * rotateDelta.x / element.clientHeight ); // yes, height
+
+				rotateUp( 2 * Math.PI * rotateDelta.y / element.clientHeight );
+				rotateStart.copy( rotateEnd );
+				scope.update();
+
+			}
+
+			function handleMouseMoveDolly( event ) {
+
+				dollyEnd.set( event.clientX, event.clientY );
+				dollyDelta.subVectors( dollyEnd, dollyStart );
+
+				if ( dollyDelta.y > 0 ) {
+
+					dollyOut( getZoomScale() );
+
+				} else if ( dollyDelta.y < 0 ) {
+
+					dollyIn( getZoomScale() );
+
+				}
+
+				dollyStart.copy( dollyEnd );
+				scope.update();
+
+			}
+
+			function handleMouseMovePan( event ) {
+
+				panEnd.set( event.clientX, event.clientY );
+				panDelta.subVectors( panEnd, panStart ).multiplyScalar( scope.panSpeed );
+				pan( panDelta.x, panDelta.y );
+				panStart.copy( panEnd );
+				scope.update();
+
+			}
+
+			function handleMouseUp( ) { // no-op
+			}
+
+			function handleMouseWheel( event ) {
+
+				if ( event.deltaY < 0 ) {
+
+					dollyIn( getZoomScale() );
+
+				} else if ( event.deltaY > 0 ) {
+
+					dollyOut( getZoomScale() );
+
+				}
+
+				scope.update();
+
+			}
+
+			function handleKeyDown( event ) {
+
+				let needsUpdate = false;
+
+				switch ( event.code ) {
+
+					case scope.keys.UP:
+						pan( 0, scope.keyPanSpeed );
+						needsUpdate = true;
+						break;
+
+					case scope.keys.BOTTOM:
+						pan( 0, - scope.keyPanSpeed );
+						needsUpdate = true;
+						break;
+
+					case scope.keys.LEFT:
+						pan( scope.keyPanSpeed, 0 );
+						needsUpdate = true;
+						break;
+
+					case scope.keys.RIGHT:
+						pan( - scope.keyPanSpeed, 0 );
+						needsUpdate = true;
+						break;
+
+				}
+
+				if ( needsUpdate ) {
+
+					// prevent the browser from scrolling on cursor keys
+					event.preventDefault();
+					scope.update();
+
+				}
+
+			}
+
+			function handleTouchStartRotate( event ) {
+
+				if ( event.touches.length == 1 ) {
+
+					rotateStart.set( event.touches[ 0 ].pageX, event.touches[ 0 ].pageY );
+
+				} else {
+
+					const x = 0.5 * ( event.touches[ 0 ].pageX + event.touches[ 1 ].pageX );
+					const y = 0.5 * ( event.touches[ 0 ].pageY + event.touches[ 1 ].pageY );
+					rotateStart.set( x, y );
+
+				}
+
+			}
+
+			function handleTouchStartPan( event ) {
+
+				if ( event.touches.length == 1 ) {
+
+					panStart.set( event.touches[ 0 ].pageX, event.touches[ 0 ].pageY );
+
+				} else {
+
+					const x = 0.5 * ( event.touches[ 0 ].pageX + event.touches[ 1 ].pageX );
+					const y = 0.5 * ( event.touches[ 0 ].pageY + event.touches[ 1 ].pageY );
+					panStart.set( x, y );
+
+				}
+
+			}
+
+			function handleTouchStartDolly( event ) {
+
+				const dx = event.touches[ 0 ].pageX - event.touches[ 1 ].pageX;
+				const dy = event.touches[ 0 ].pageY - event.touches[ 1 ].pageY;
+				const distance = Math.sqrt( dx * dx + dy * dy );
+				dollyStart.set( 0, distance );
+
+			}
+
+			function handleTouchStartDollyPan( event ) {
+
+				if ( scope.enableZoom ) handleTouchStartDolly( event );
+				if ( scope.enablePan ) handleTouchStartPan( event );
+
+			}
+
+			function handleTouchStartDollyRotate( event ) {
+
+				if ( scope.enableZoom ) handleTouchStartDolly( event );
+				if ( scope.enableRotate ) handleTouchStartRotate( event );
+
+			}
+
+			function handleTouchMoveRotate( event ) {
+
+				if ( event.touches.length == 1 ) {
+
+					rotateEnd.set( event.touches[ 0 ].pageX, event.touches[ 0 ].pageY );
+
+				} else {
+
+					const x = 0.5 * ( event.touches[ 0 ].pageX + event.touches[ 1 ].pageX );
+					const y = 0.5 * ( event.touches[ 0 ].pageY + event.touches[ 1 ].pageY );
+					rotateEnd.set( x, y );
+
+				}
+
+				rotateDelta.subVectors( rotateEnd, rotateStart ).multiplyScalar( scope.rotateSpeed );
+				const element = scope.domElement;
+				rotateLeft( 2 * Math.PI * rotateDelta.x / element.clientHeight ); // yes, height
+
+				rotateUp( 2 * Math.PI * rotateDelta.y / element.clientHeight );
+				rotateStart.copy( rotateEnd );
+
+			}
+
+			function handleTouchMovePan( event ) {
+
+				if ( event.touches.length == 1 ) {
+
+					panEnd.set( event.touches[ 0 ].pageX, event.touches[ 0 ].pageY );
+
+				} else {
+
+					const x = 0.5 * ( event.touches[ 0 ].pageX + event.touches[ 1 ].pageX );
+					const y = 0.5 * ( event.touches[ 0 ].pageY + event.touches[ 1 ].pageY );
+					panEnd.set( x, y );
+
+				}
+
+				panDelta.subVectors( panEnd, panStart ).multiplyScalar( scope.panSpeed );
+				pan( panDelta.x, panDelta.y );
+				panStart.copy( panEnd );
+
+			}
+
+			function handleTouchMoveDolly( event ) {
+
+				const dx = event.touches[ 0 ].pageX - event.touches[ 1 ].pageX;
+				const dy = event.touches[ 0 ].pageY - event.touches[ 1 ].pageY;
+				const distance = Math.sqrt( dx * dx + dy * dy );
+				dollyEnd.set( 0, distance );
+				dollyDelta.set( 0, Math.pow( dollyEnd.y / dollyStart.y, scope.zoomSpeed ) );
+				dollyOut( dollyDelta.y );
+				dollyStart.copy( dollyEnd );
+
+			}
+
+			function handleTouchMoveDollyPan( event ) {
+
+				if ( scope.enableZoom ) handleTouchMoveDolly( event );
+				if ( scope.enablePan ) handleTouchMovePan( event );
+
+			}
+
+			function handleTouchMoveDollyRotate( event ) {
+
+				if ( scope.enableZoom ) handleTouchMoveDolly( event );
+				if ( scope.enableRotate ) handleTouchMoveRotate( event );
+
+			}
+
+			function handleTouchEnd( ) { // no-op
+			} //
+			// event handlers - FSM: listen for events and reset state
+			//
+
+
+			function onPointerDown( event ) {
+
+				if ( scope.enabled === false ) return;
+
+				switch ( event.pointerType ) {
+
+					case 'mouse':
+					case 'pen':
+						onMouseDown( event );
+						break;
+        // TODO touch
+
+				}
+
+			}
+
+			function onPointerMove( event ) {
+
+				if ( scope.enabled === false ) return;
+
+				switch ( event.pointerType ) {
+
+					case 'mouse':
+					case 'pen':
+						onMouseMove( event );
+						break;
+        // TODO touch
+
+				}
+
+			}
+
+			function onPointerUp( event ) {
+
+				switch ( event.pointerType ) {
+
+					case 'mouse':
+					case 'pen':
+						onMouseUp( event );
+						break;
+        // TODO touch
+
+				}
+
+			}
+
+			function onMouseDown( event ) {
+
+				// Prevent the browser from scrolling.
+				event.preventDefault(); // Manually set the focus since calling preventDefault above
+				// prevents the browser from setting it automatically.
+
+				scope.domElement.focus ? scope.domElement.focus() : window.focus();
+				let mouseAction;
+
+				switch ( event.button ) {
+
+					case 0:
+						mouseAction = scope.mouseButtons.LEFT;
+						break;
+
+					case 1:
+						mouseAction = scope.mouseButtons.MIDDLE;
+						break;
+
+					case 2:
+						mouseAction = scope.mouseButtons.RIGHT;
+						break;
+
+					default:
+						mouseAction = - 1;
+
+				}
+
+				switch ( mouseAction ) {
+
+					case THREE.MOUSE.DOLLY:
+						if ( scope.enableZoom === false ) return;
+						handleMouseDownDolly( event );
+						state = STATE.DOLLY;
+						break;
+
+					case THREE.MOUSE.ROTATE:
+						if ( event.ctrlKey || event.metaKey || event.shiftKey ) {
+
+							if ( scope.enablePan === false ) return;
+							handleMouseDownPan( event );
+							state = STATE.PAN;
+
+						} else {
+
+							if ( scope.enableRotate === false ) return;
+							handleMouseDownRotate( event );
+							state = STATE.ROTATE;
+
+						}
+
+						break;
+
+					case THREE.MOUSE.PAN:
+						if ( event.ctrlKey || event.metaKey || event.shiftKey ) {
+
+							if ( scope.enableRotate === false ) return;
+							handleMouseDownRotate( event );
+							state = STATE.ROTATE;
+
+						} else {
+
+							if ( scope.enablePan === false ) return;
+							handleMouseDownPan( event );
+							state = STATE.PAN;
+
+						}
+
+						break;
+
+					default:
+						state = STATE.NONE;
+
+				}
+
+				if ( state !== STATE.NONE ) {
+
+					scope.domElement.ownerDocument.addEventListener( 'pointermove', onPointerMove );
+					scope.domElement.ownerDocument.addEventListener( 'pointerup', onPointerUp );
+					scope.dispatchEvent( _startEvent );
+
+				}
+
+			}
+
+			function onMouseMove( event ) {
+
+				if ( scope.enabled === false ) return;
+				event.preventDefault();
+
+				switch ( state ) {
+
+					case STATE.ROTATE:
+						if ( scope.enableRotate === false ) return;
+						handleMouseMoveRotate( event );
+						break;
+
+					case STATE.DOLLY:
+						if ( scope.enableZoom === false ) return;
+						handleMouseMoveDolly( event );
+						break;
+
+					case STATE.PAN:
+						if ( scope.enablePan === false ) return;
+						handleMouseMovePan( event );
+						break;
+
+				}
+
+			}
+
+			function onMouseUp( event ) {
+
+				scope.domElement.ownerDocument.removeEventListener( 'pointermove', onPointerMove );
+				scope.domElement.ownerDocument.removeEventListener( 'pointerup', onPointerUp );
+				if ( scope.enabled === false ) return;
+				handleMouseUp( event );
+				scope.dispatchEvent( _endEvent );
+				state = STATE.NONE;
+
+			}
+
+			function onMouseWheel( event ) {
+
+				if ( scope.enabled === false || scope.enableZoom === false || state !== STATE.NONE && state !== STATE.ROTATE ) return;
+				event.preventDefault();
+				scope.dispatchEvent( _startEvent );
+				handleMouseWheel( event );
+				scope.dispatchEvent( _endEvent );
+
+			}
+
+			function onKeyDown( event ) {
+
+				if ( scope.enabled === false || scope.enablePan === false ) return;
+				handleKeyDown( event );
+
+			}
+
+			function onTouchStart( event ) {
+
+				if ( scope.enabled === false ) return;
+				event.preventDefault(); // prevent scrolling
+
+				switch ( event.touches.length ) {
+
+					case 1:
+						switch ( scope.touches.ONE ) {
+
+							case THREE.TOUCH.ROTATE:
+								if ( scope.enableRotate === false ) return;
+								handleTouchStartRotate( event );
+								state = STATE.TOUCH_ROTATE;
+								break;
+
+							case THREE.TOUCH.PAN:
+								if ( scope.enablePan === false ) return;
+								handleTouchStartPan( event );
+								state = STATE.TOUCH_PAN;
+								break;
+
+							default:
+								state = STATE.NONE;
+
+						}
+
+						break;
+
+					case 2:
+						switch ( scope.touches.TWO ) {
+
+							case THREE.TOUCH.DOLLY_PAN:
+								if ( scope.enableZoom === false && scope.enablePan === false ) return;
+								handleTouchStartDollyPan( event );
+								state = STATE.TOUCH_DOLLY_PAN;
+								break;
+
+							case THREE.TOUCH.DOLLY_ROTATE:
+								if ( scope.enableZoom === false && scope.enableRotate === false ) return;
+								handleTouchStartDollyRotate( event );
+								state = STATE.TOUCH_DOLLY_ROTATE;
+								break;
+
+							default:
+								state = STATE.NONE;
+
+						}
+
+						break;
+
+					default:
+						state = STATE.NONE;
+
+				}
+
+				if ( state !== STATE.NONE ) {
+
+					scope.dispatchEvent( _startEvent );
+
+				}
+
+			}
+
+			function onTouchMove( event ) {
+
+				if ( scope.enabled === false ) return;
+				event.preventDefault(); // prevent scrolling
+
+				switch ( state ) {
+
+					case STATE.TOUCH_ROTATE:
+						if ( scope.enableRotate === false ) return;
+						handleTouchMoveRotate( event );
+						scope.update();
+						break;
+
+					case STATE.TOUCH_PAN:
+						if ( scope.enablePan === false ) return;
+						handleTouchMovePan( event );
+						scope.update();
+						break;
+
+					case STATE.TOUCH_DOLLY_PAN:
+						if ( scope.enableZoom === false && scope.enablePan === false ) return;
+						handleTouchMoveDollyPan( event );
+						scope.update();
+						break;
+
+					case STATE.TOUCH_DOLLY_ROTATE:
+						if ( scope.enableZoom === false && scope.enableRotate === false ) return;
+						handleTouchMoveDollyRotate( event );
+						scope.update();
+						break;
+
+					default:
+						state = STATE.NONE;
+
+				}
+
+			}
+
+			function onTouchEnd( event ) {
+
+				if ( scope.enabled === false ) return;
+				handleTouchEnd( event );
+				scope.dispatchEvent( _endEvent );
+				state = STATE.NONE;
+
+			}
+
+			function onContextMenu( event ) {
+
+				if ( scope.enabled === false ) return;
+				event.preventDefault();
+
+			} //
+
+
+			scope.domElement.addEventListener( 'contextmenu', onContextMenu );
+			scope.domElement.addEventListener( 'pointerdown', onPointerDown );
+			scope.domElement.addEventListener( 'wheel', onMouseWheel, {
+				passive: false
+			} );
+			scope.domElement.addEventListener( 'touchstart', onTouchStart, {
+				passive: false
+			} );
+			scope.domElement.addEventListener( 'touchend', onTouchEnd );
+			scope.domElement.addEventListener( 'touchmove', onTouchMove, {
+				passive: false
+			} ); // force an update at start
+
+			this.update();
+
+		}
+
+	} // This set of controls performs orbiting, dollying (zooming), and panning.
+	// Unlike TrackballControls, it maintains the "up" direction object.up (+Y by default).
+	// This is very similar to OrbitControls, another set of touch behavior
+	//
+	//    Orbit - right mouse, or left mouse + ctrl/meta/shiftKey / touch: two-finger rotate
+	//    Zoom - middle mouse, or mousewheel / touch: two-finger spread or squish
+	//    Pan - left mouse, or arrow keys / touch: one-finger move
+
+
+	class MapControls extends OrbitControls {
+
+		constructor( object, domElement ) {
+
+			super( object, domElement );
+			this.screenSpacePanning = false; // pan orthogonal to world-space direction camera.up
+
+			this.mouseButtons.LEFT = THREE.MOUSE.PAN;
+			this.mouseButtons.RIGHT = THREE.MOUSE.ROTATE;
+			this.touches.ONE = THREE.TOUCH.PAN;
+			this.touches.TWO = THREE.TOUCH.DOLLY_ROTATE;
+
+		}
+
+	}
+
+	THREE.MapControls = MapControls;
+	THREE.OrbitControls = OrbitControls;
+
+} )();

Різницю між файлами не показано, бо вона завелика
+ 5 - 0
html/vendor/three.min.js


BIN
html/微信图片_20260817170012_14_2.png


BIN
meta_graph.png


BIN
meta_graph_project_self_loops.png

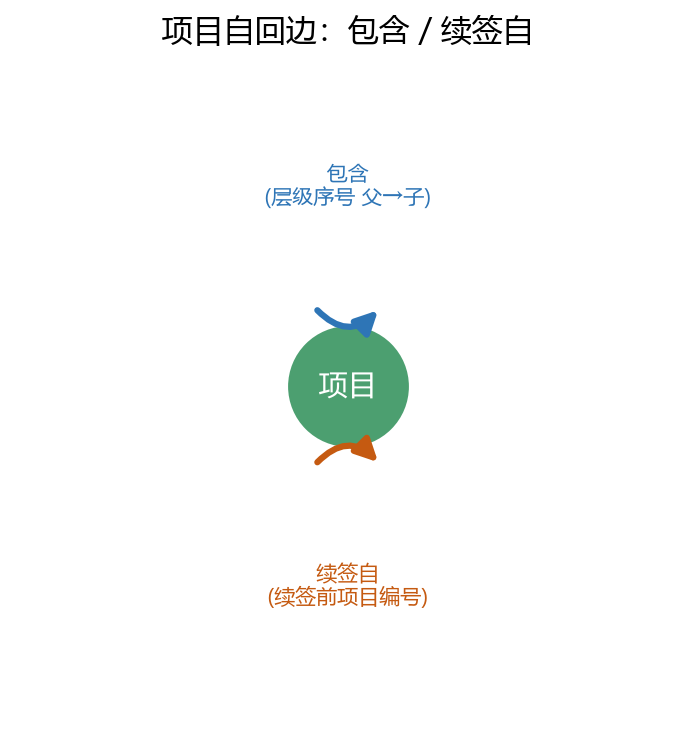
BIN
meta_graph_v2.png

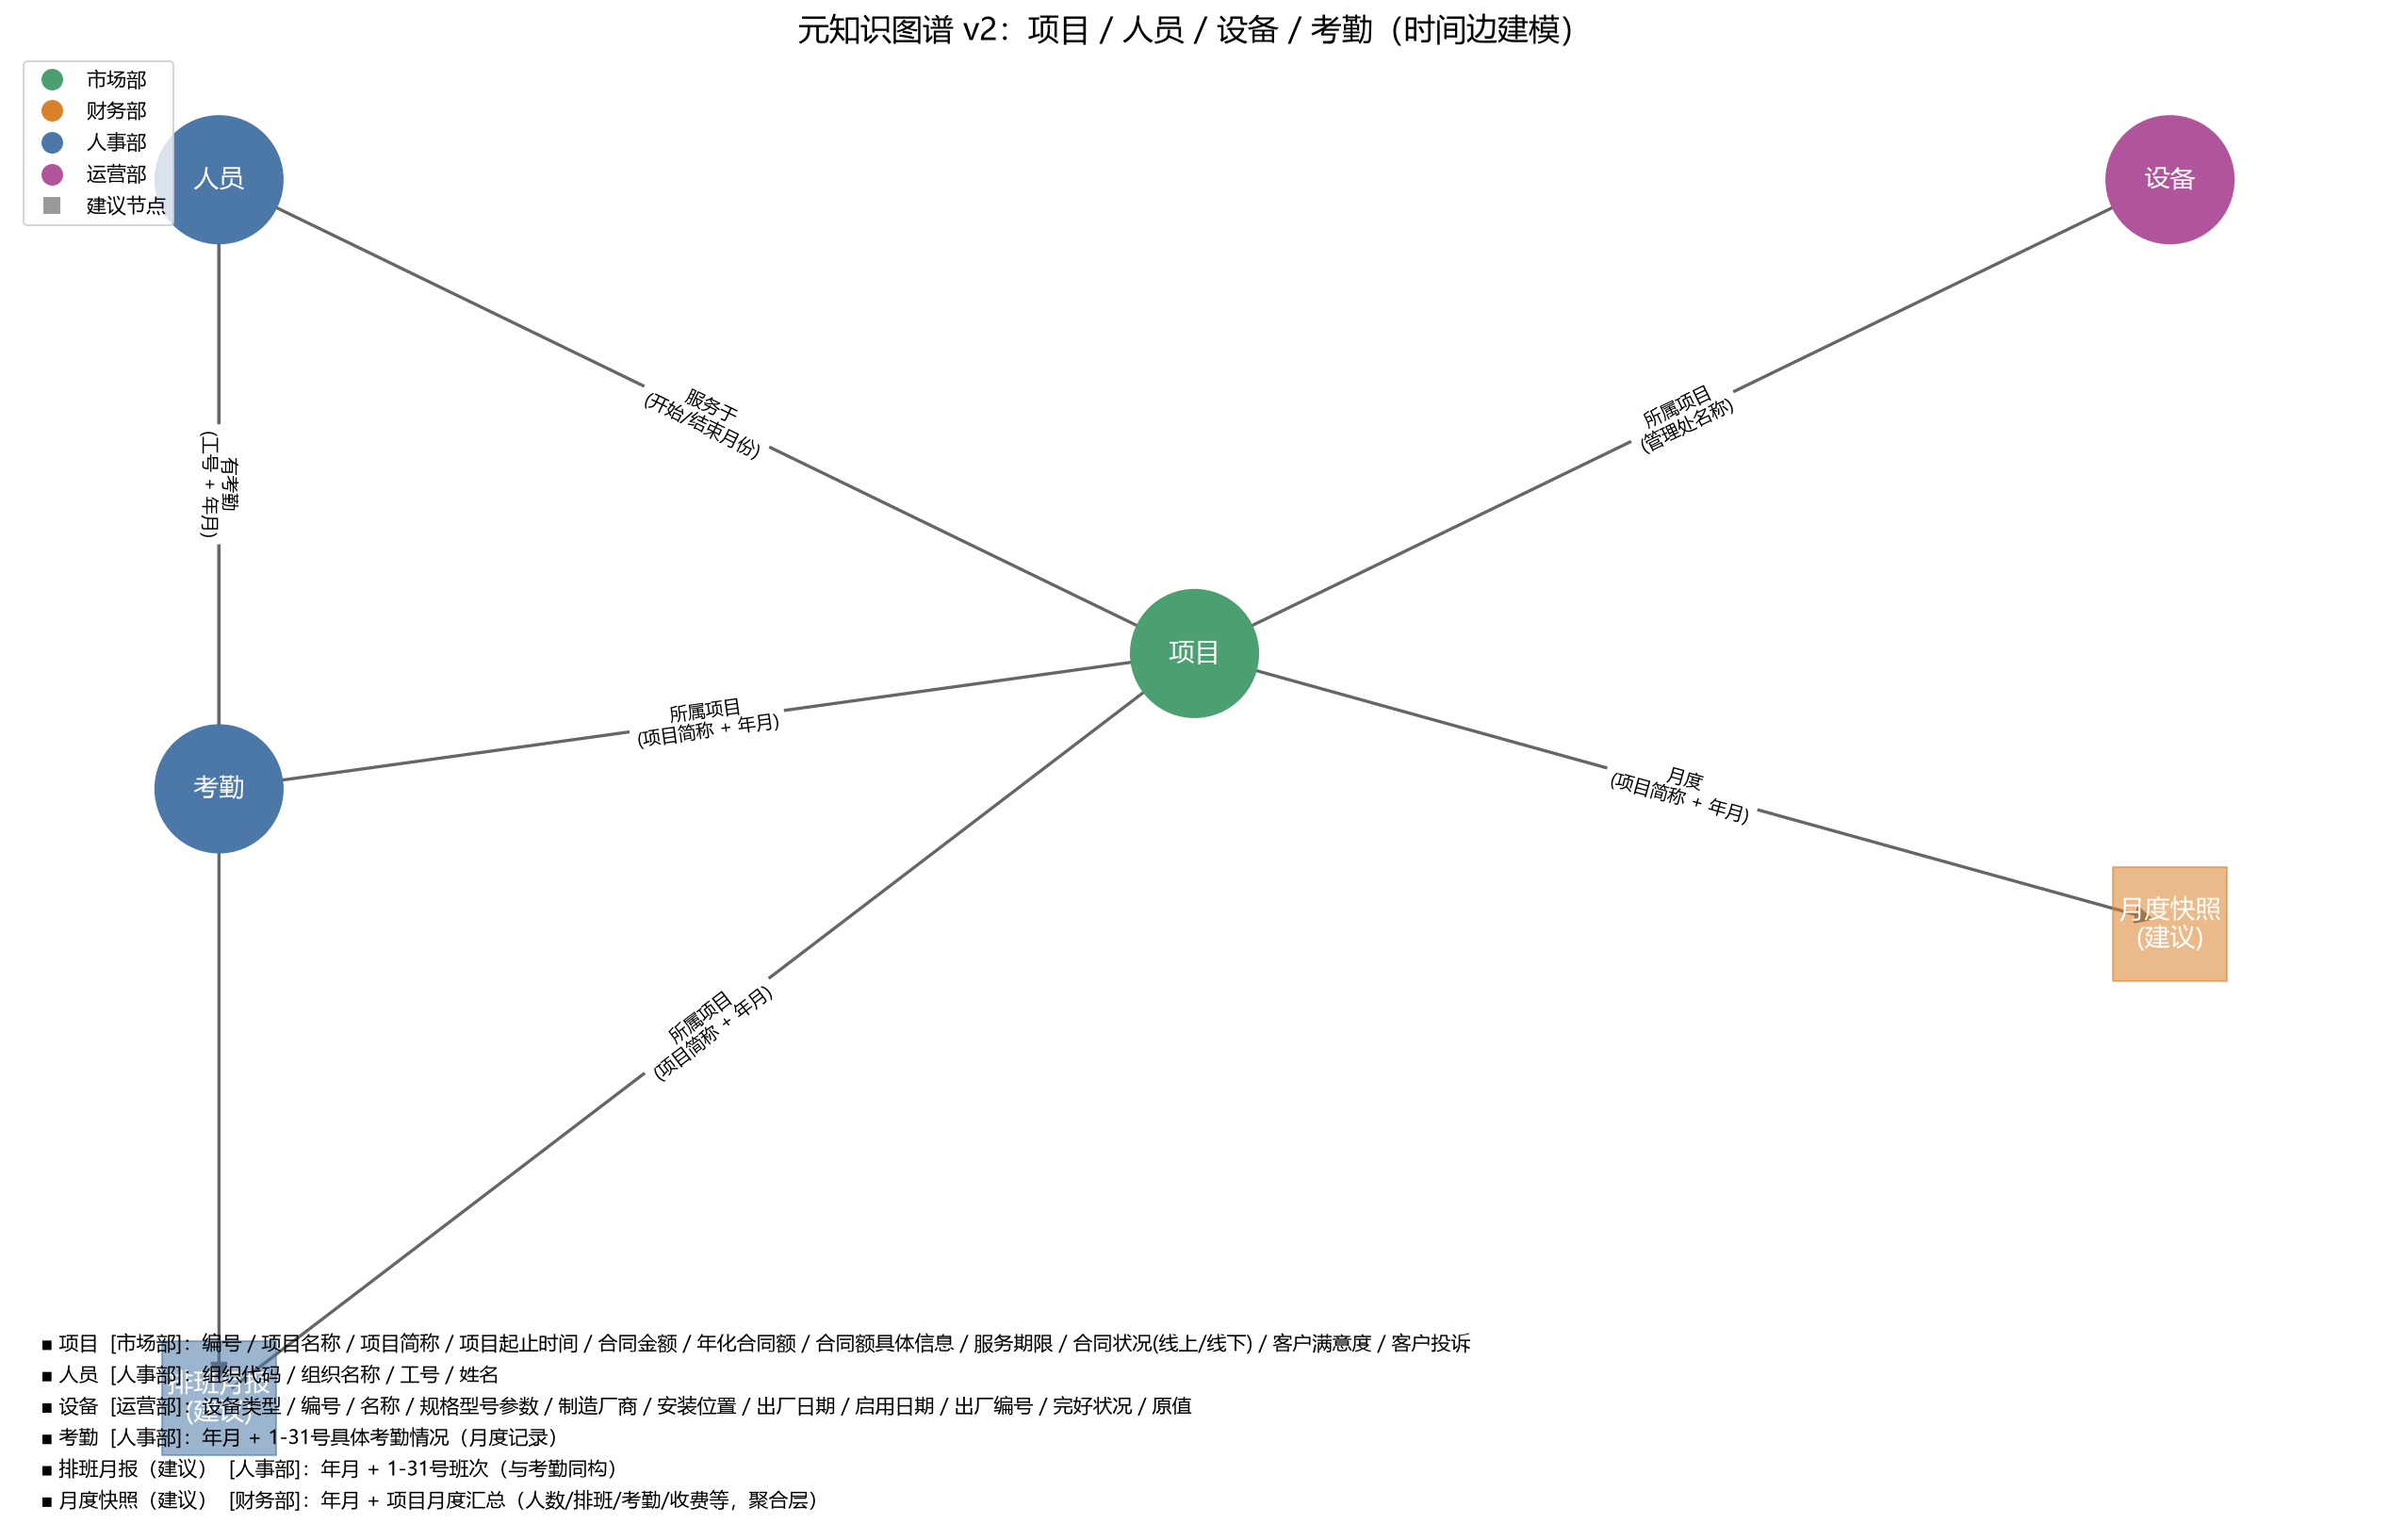
BIN
meta_graph_v3.png


BIN
meta_graph_v4.png

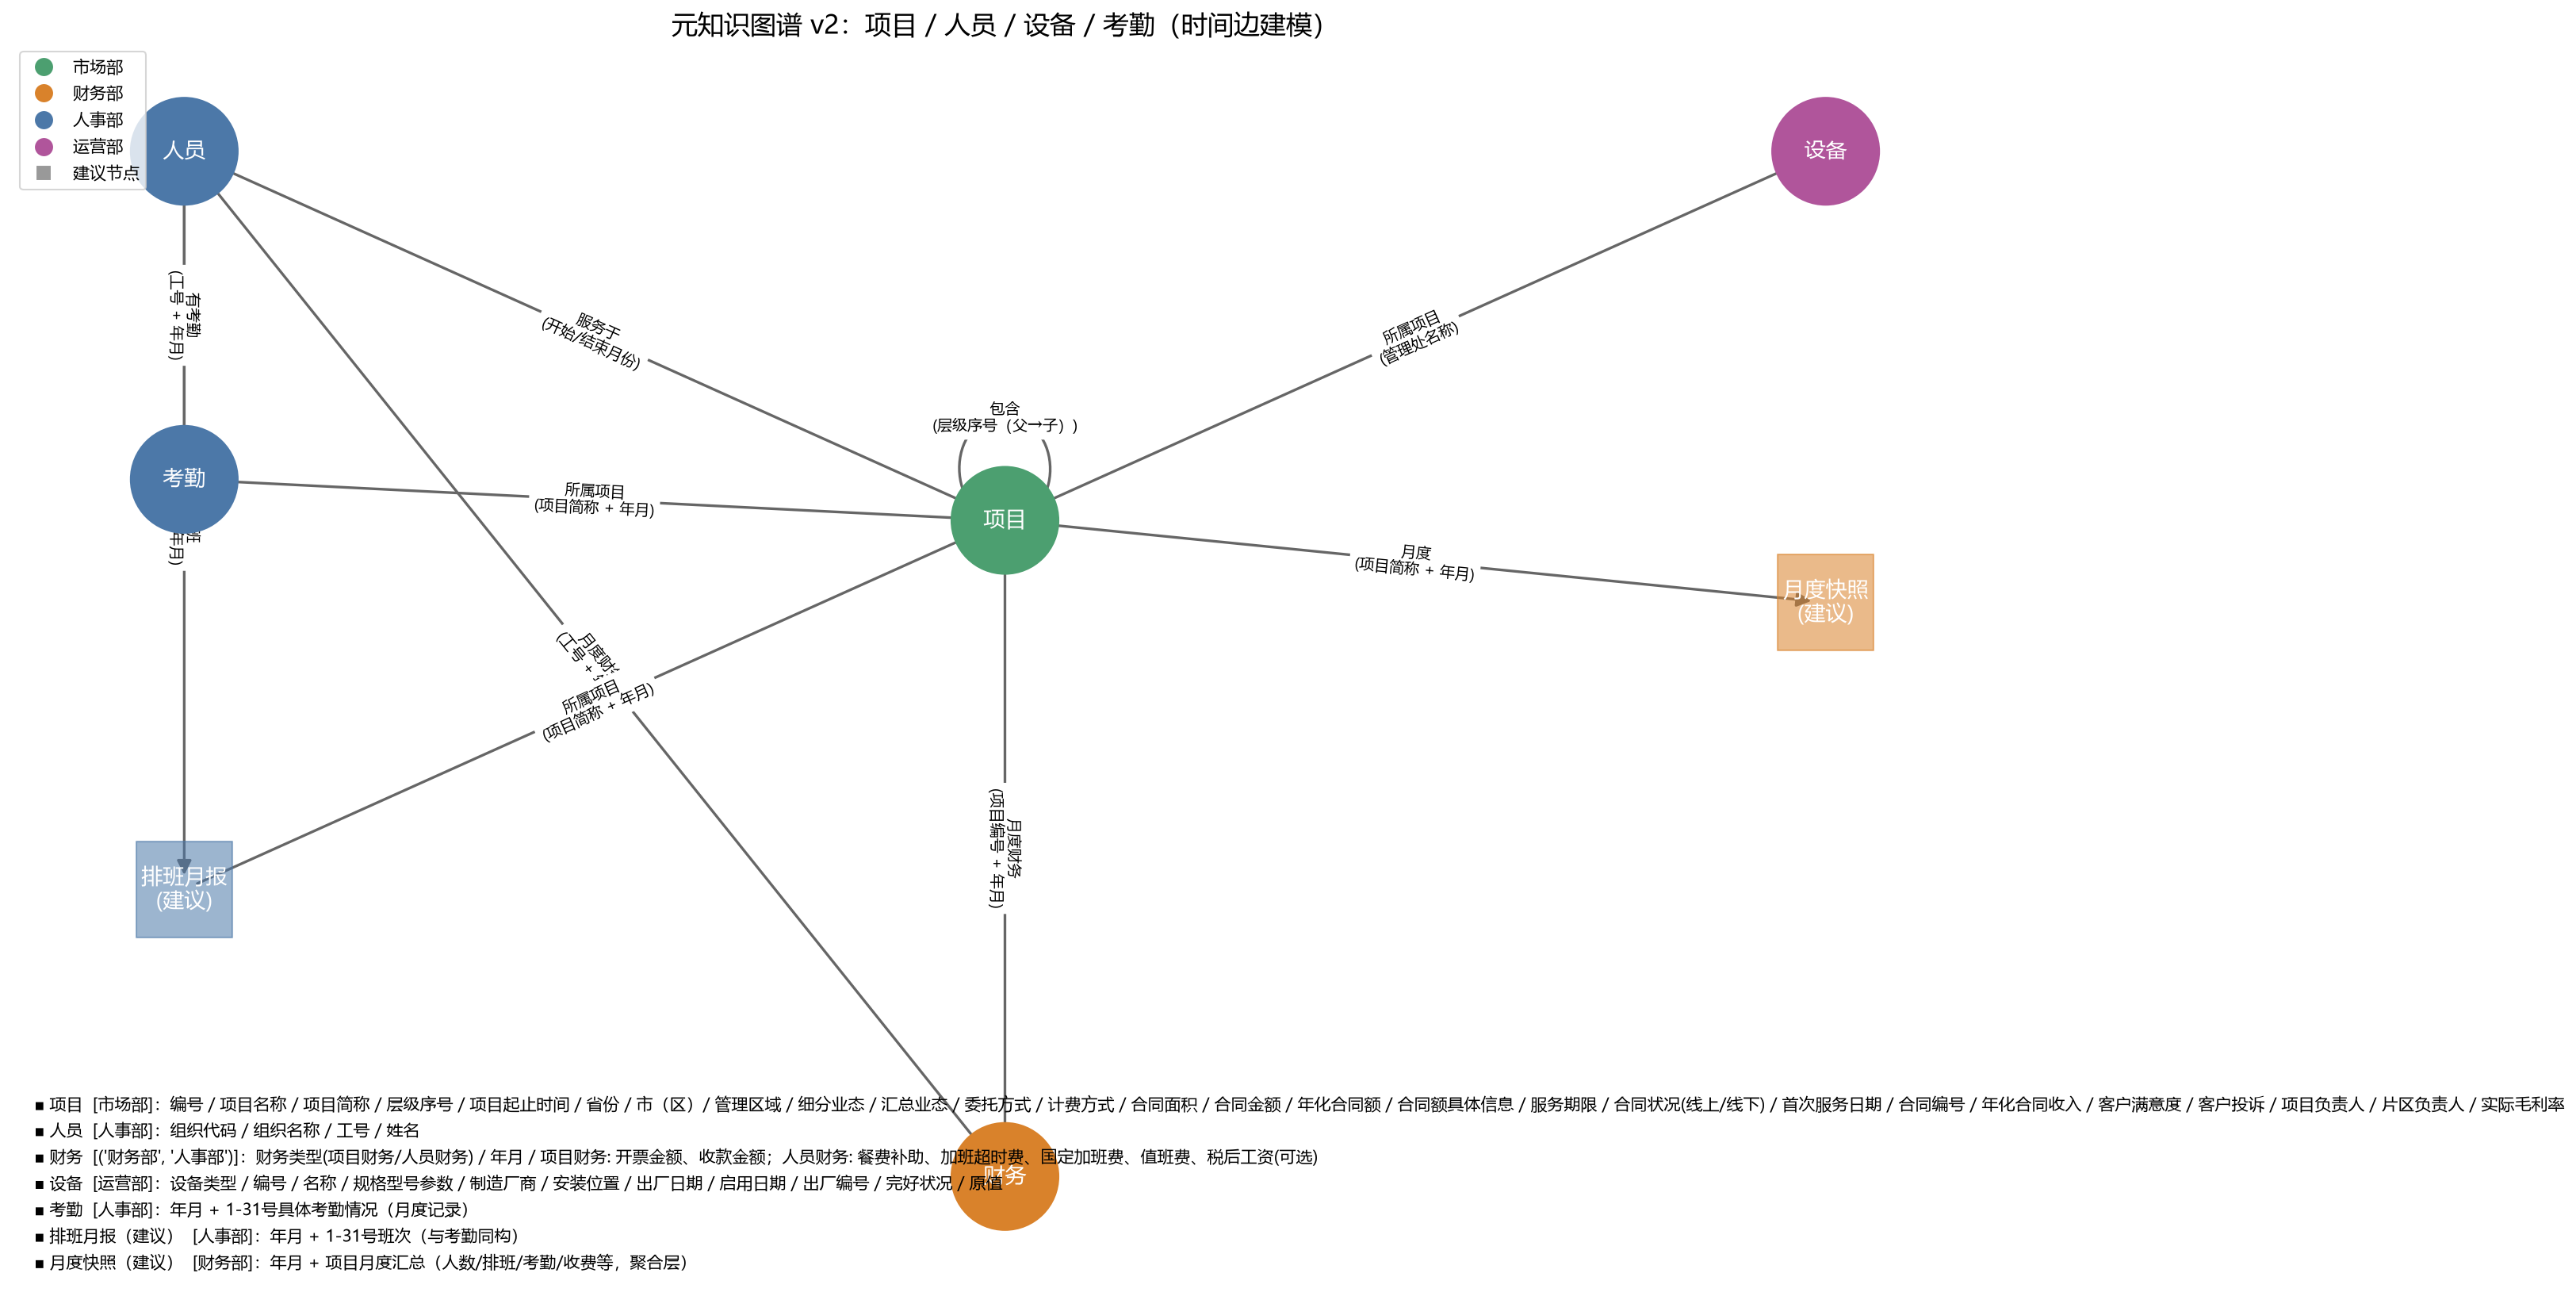
BIN
meta_graph_v5.png

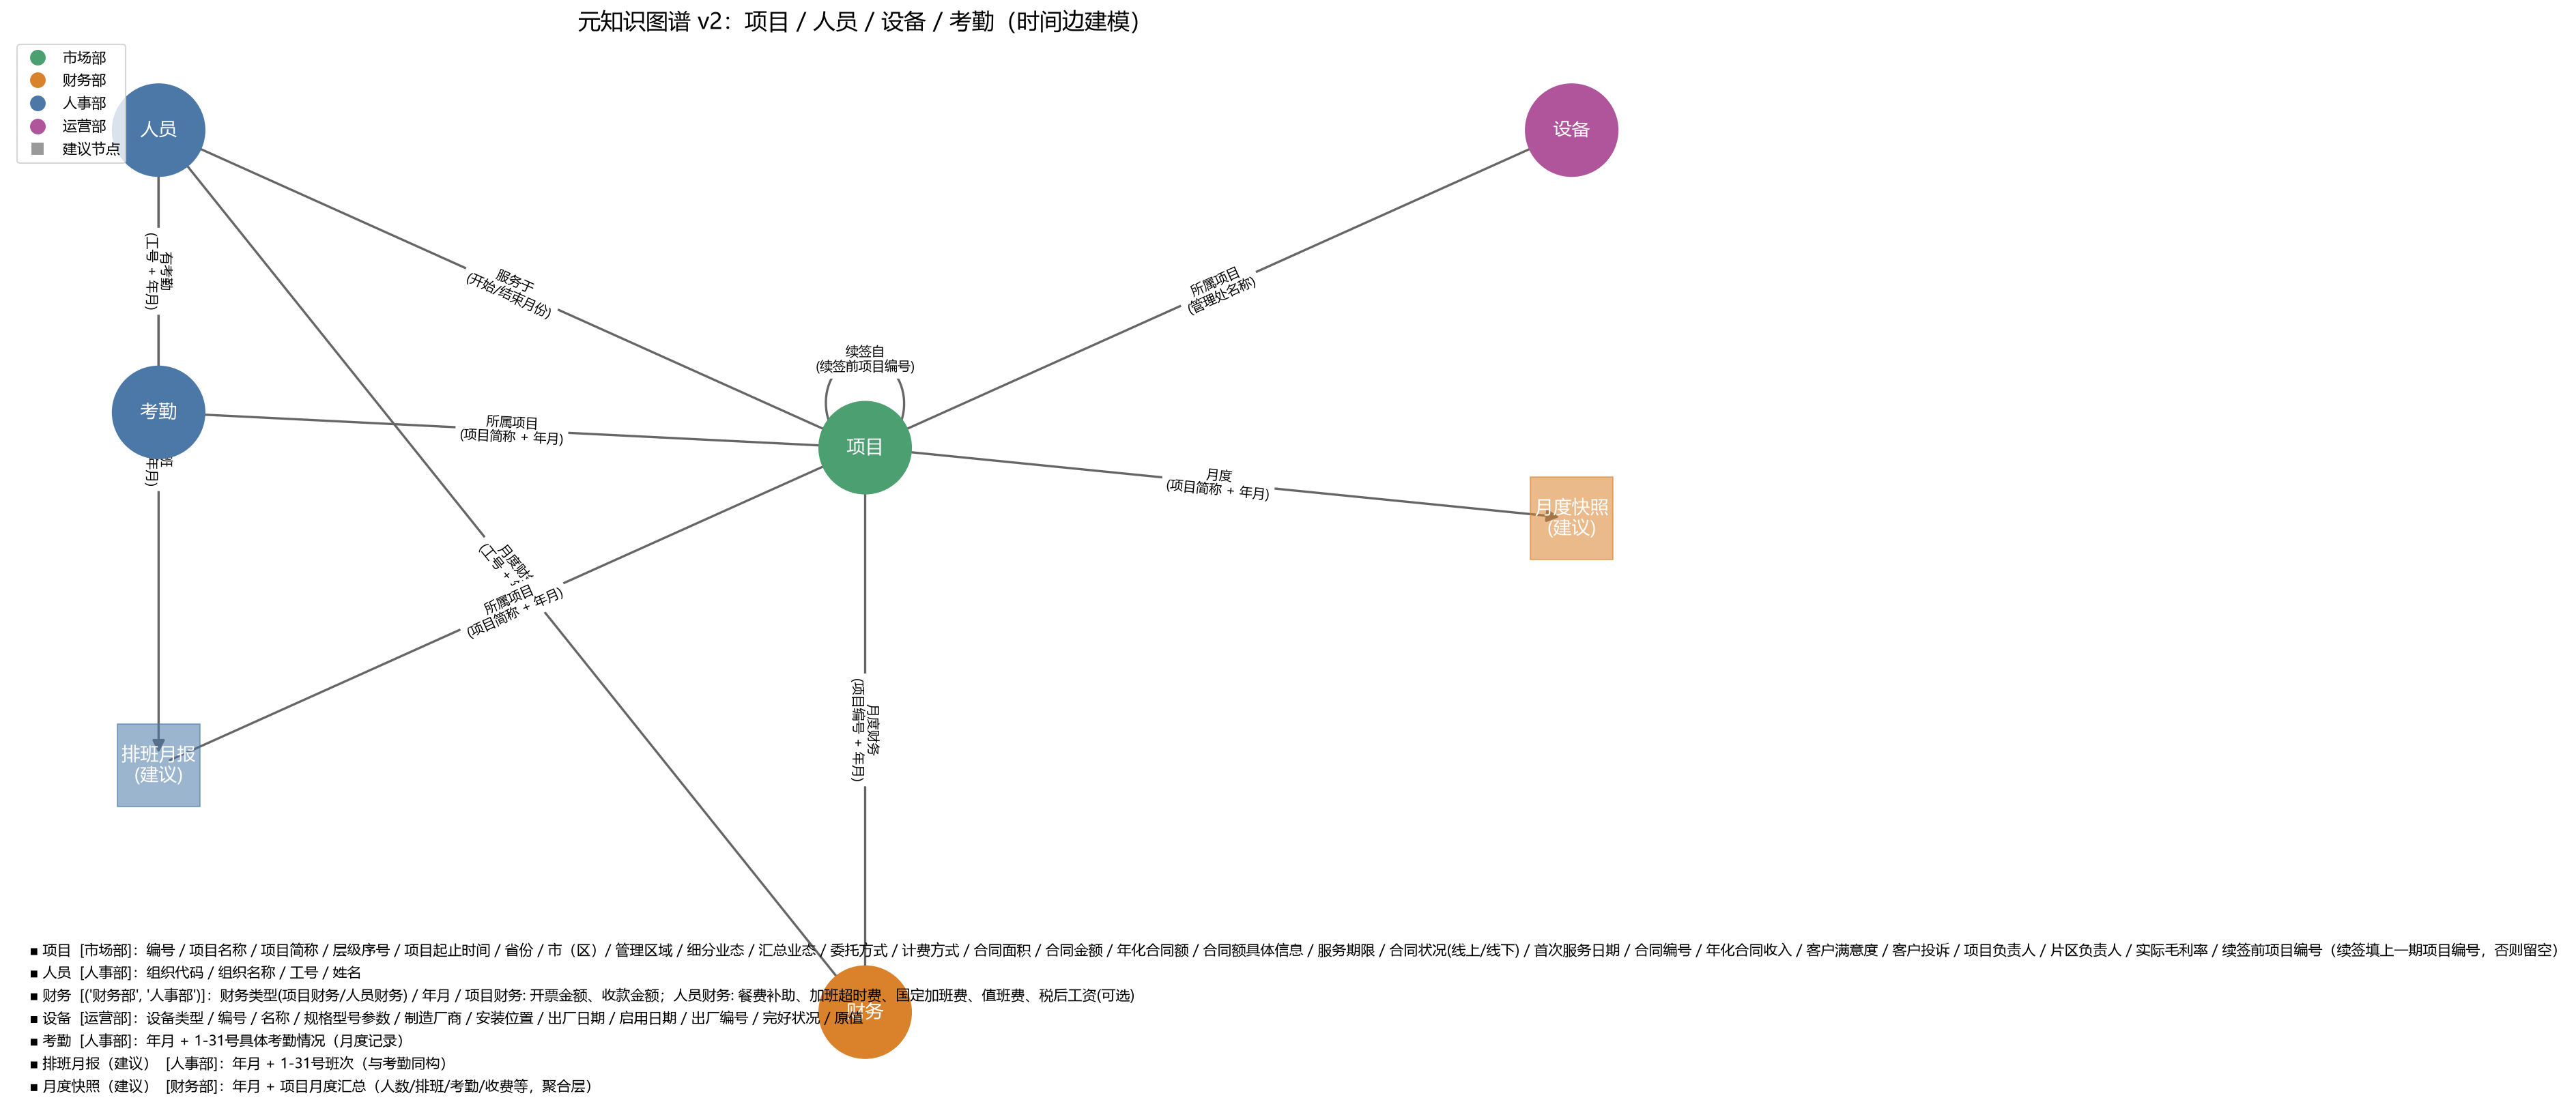
BIN
meta_graph_v6.png

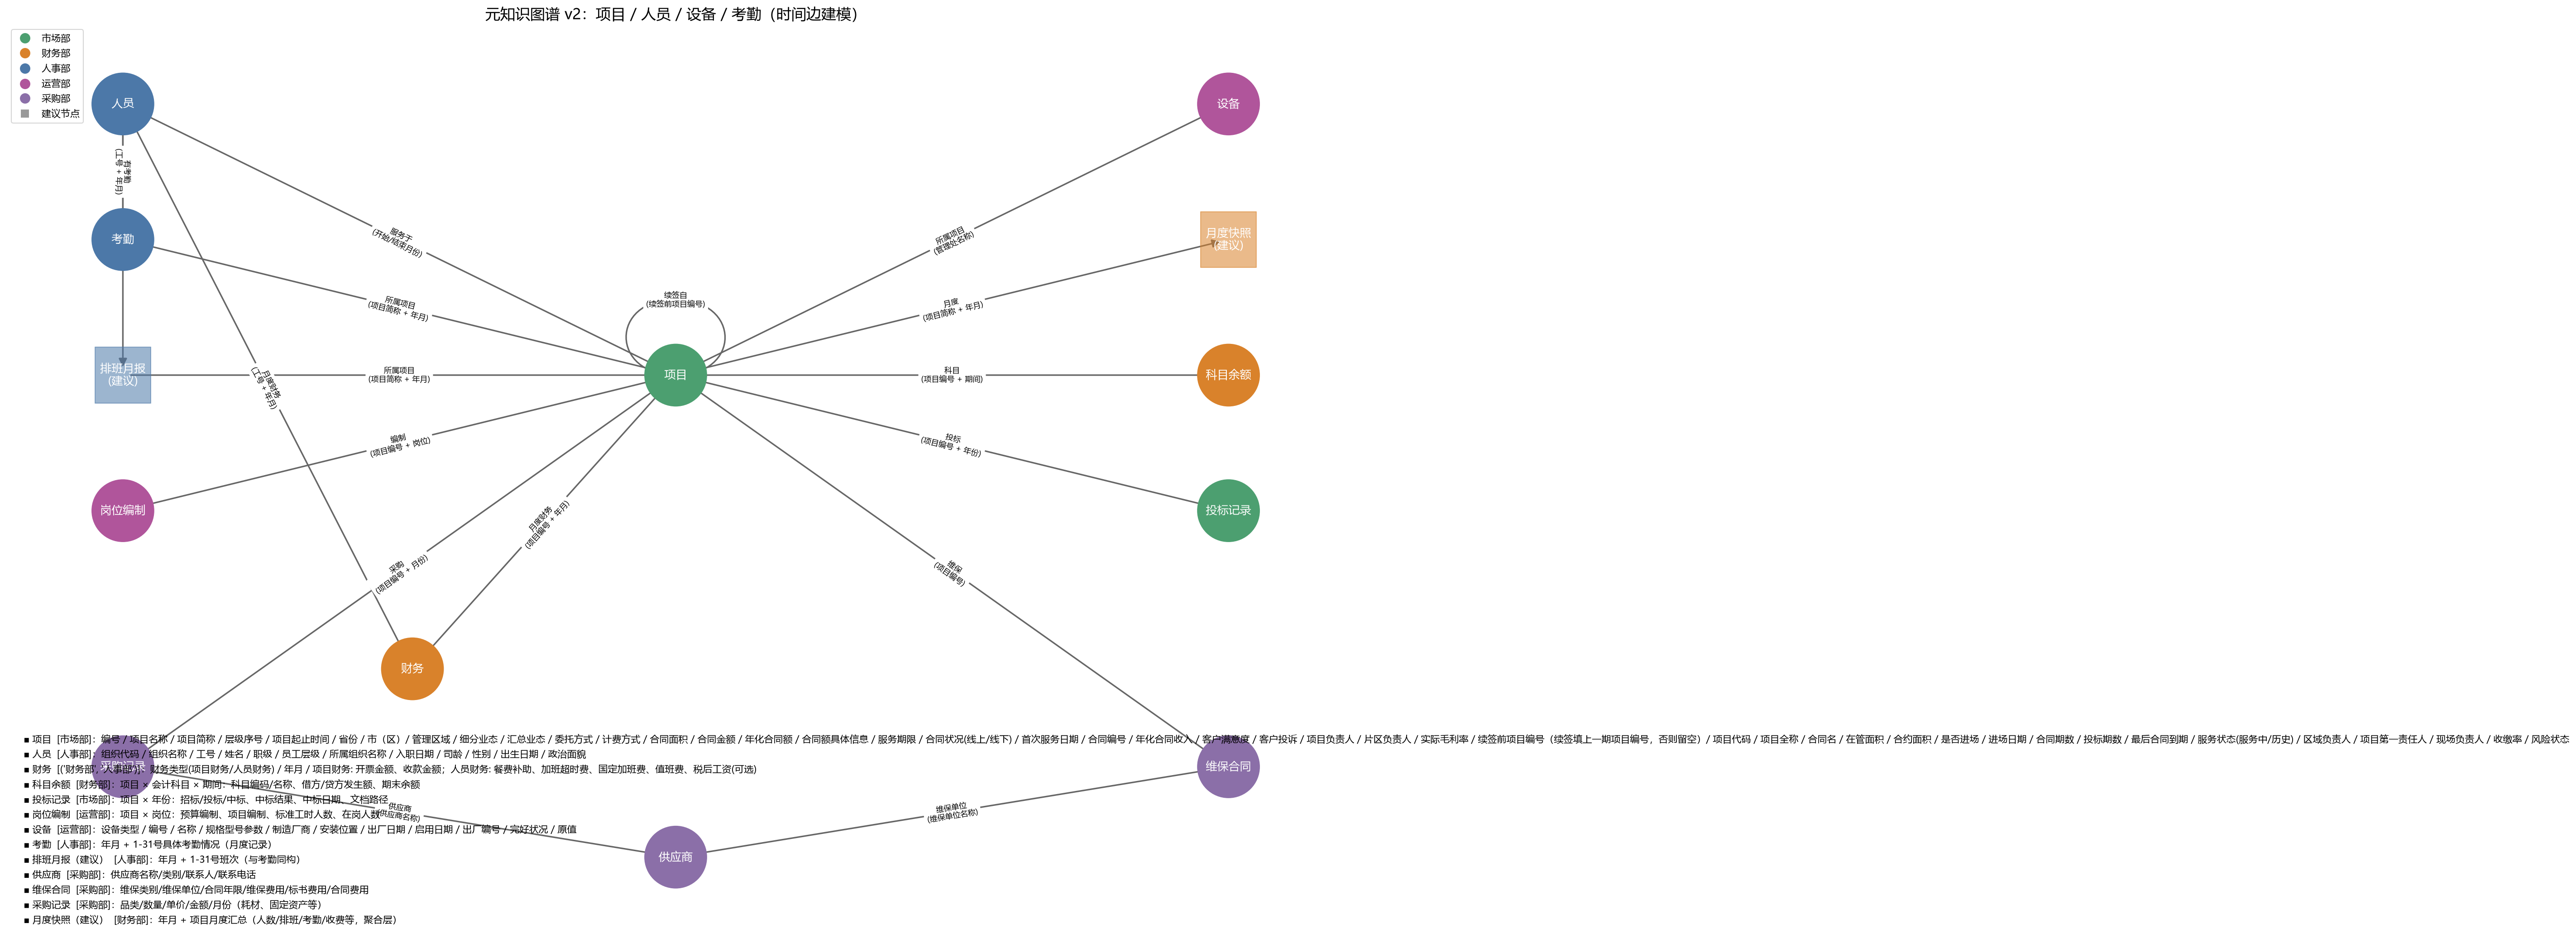
BIN
meta_graph_v7.png

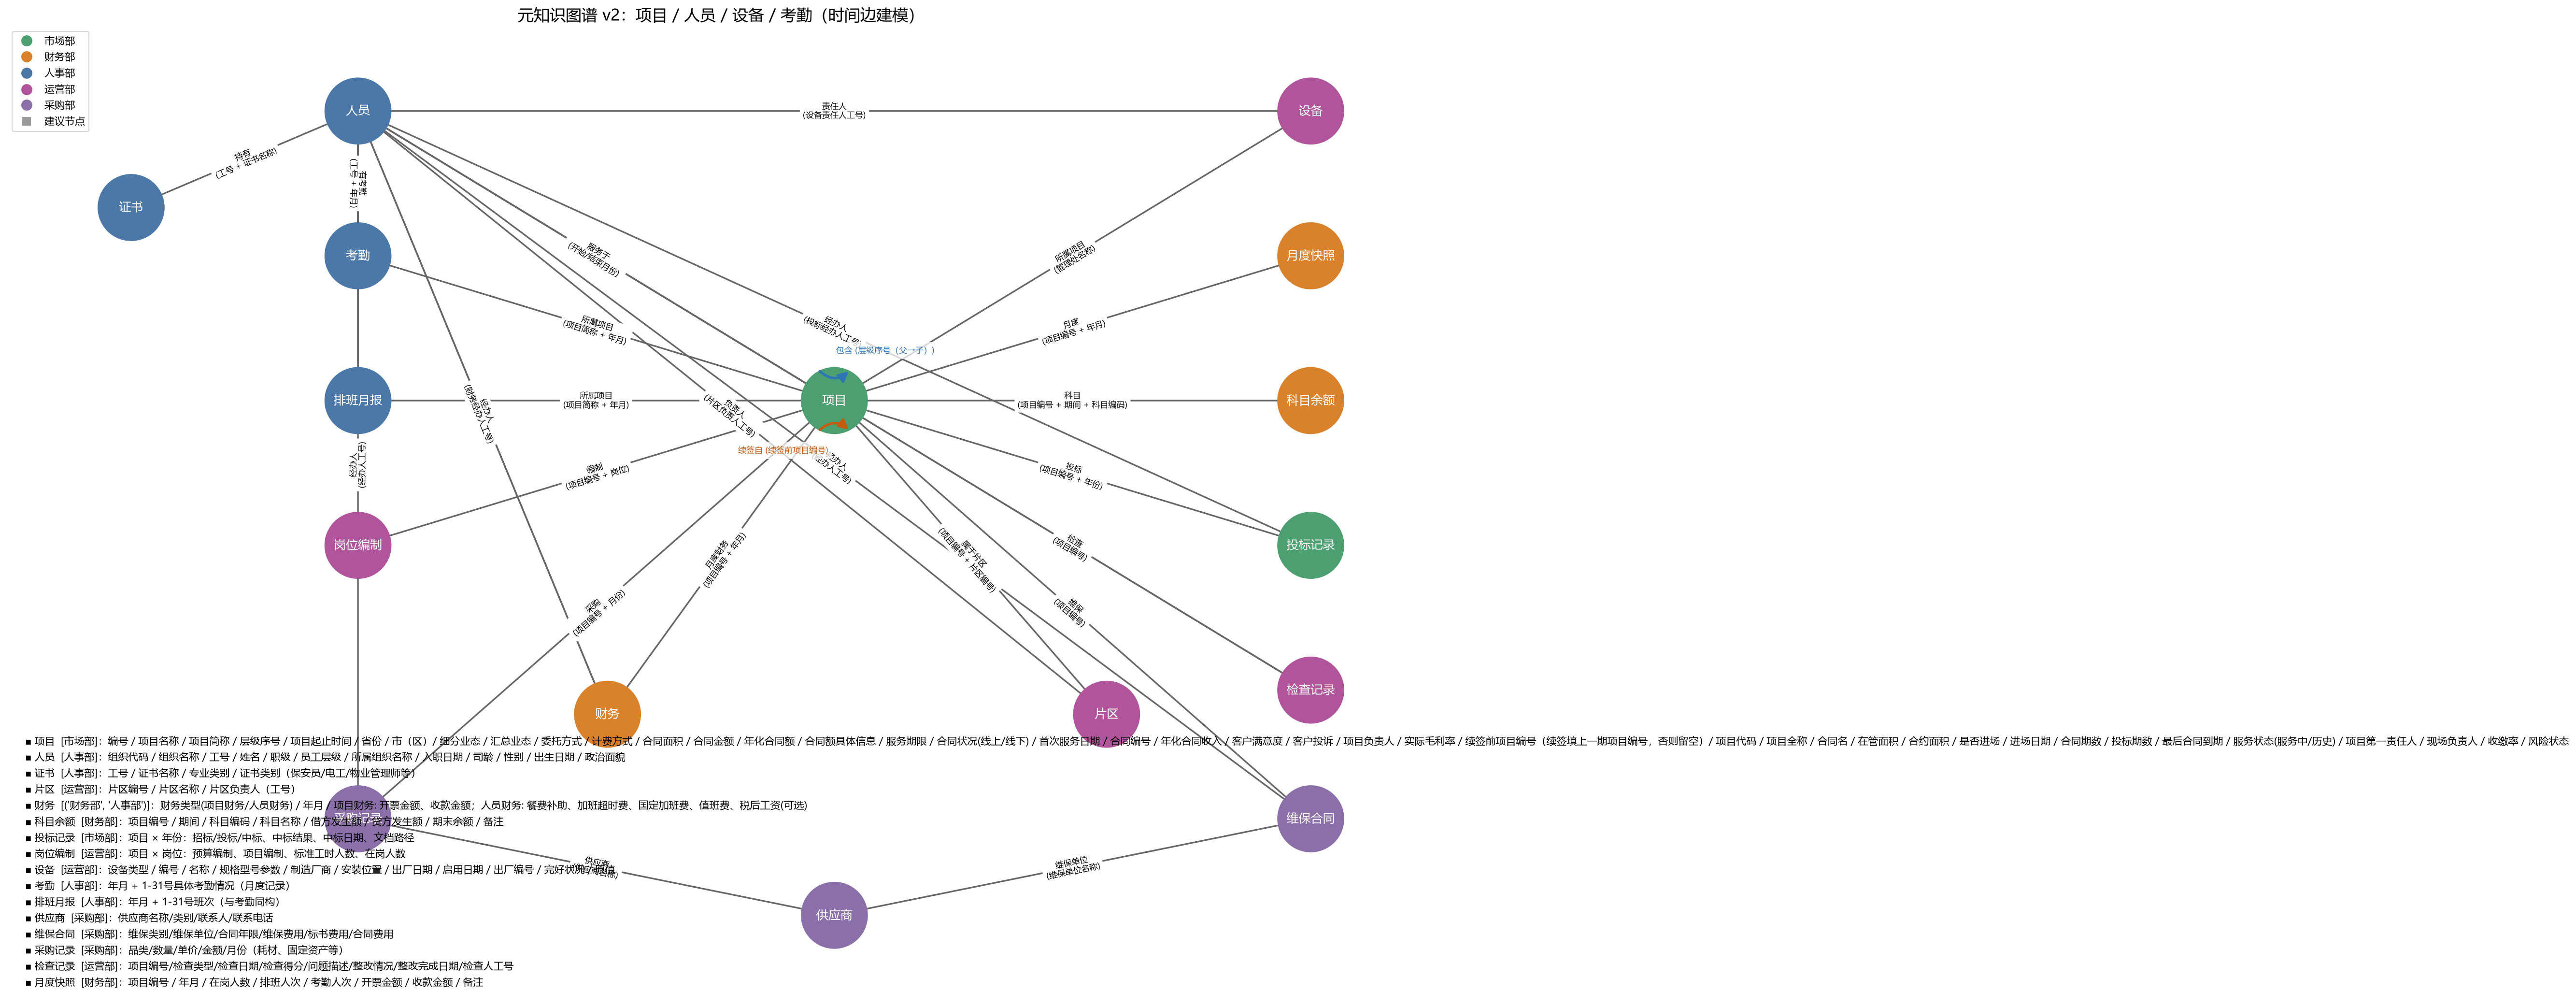
+ 0 - 92
scripts/analyze_temporal.py

@@ -1,92 +0,0 @@
-"""分析考勤数据中的人员-项目-时间分布,验证时间建模方案。"""
-
-from __future__ import annotations
-
-import re
-from pathlib import Path
-
-import pandas as pd
-
-
-HR_ROOT = Path(r"E:\CODE\knowledge_agent\data\20260529_申勤提供数据\人事部")
-MONTH_PAT = re.compile(r"(\d{1,2})\s*月")
-
-
-def _month_from_sheet(sh: str, default: int | None = None) -> int | None:
-    m = MONTH_PAT.search(sh)
-    return int(m.group(1)) if m else default
-
-
-def _header_info(df: pd.DataFrame) -> tuple[str, int]:
-    """从表头前几行中提取 项目名 与 年份。"""
-    project = ""
-    year = 2026
-    for r in range(min(3, len(df))):
-        for c in range(min(12, df.shape[1])):
-            v = df.iat[r, c]
-            if pd.isna(v):
-                continue
-            s = str(v)
-            m = re.search(r"项目[::]\s*(.+)", s)
-            if m and not project:
-                project = m.group(1).strip()
-            ym = re.search(r"20(\d{2})\s*年", s)
-            if ym:
-                year = 2000 + int(ym.group(1))
-    return project, year
-
-
-def main() -> None:
-    # employee -> {project: set(months)}
-    emp_proj: dict[str, dict[str, set[int]]] = {}
-    # project -> {month: employee count}
-    proj_month: dict[str, dict[int, set[str]]] = {}
-    total_rows = 0
-
-    for p in sorted(HR_ROOT.rglob("*.xls")):
-        try:
-            xls = pd.ExcelFile(p)
-        except Exception:  # noqa: BLE001
-            continue
-        for sh in xls.sheet_names:
-            try:
-                df = pd.read_excel(xls, sheet_name=sh, header=None, dtype=str)
-            except Exception:  # noqa: BLE001
-                continue
-            if df.shape[0] < 5 or df.shape[1] < 4:
-                continue
-            project, year = _header_info(df)
-            if not project:
-                project = p.name
-            month = _month_from_sheet(sh)
-            sub = df.iloc[4:].copy()
-            sub.columns = range(sub.shape[1])
-            sub = sub[sub[3].notna()]
-            for _, row in sub.iterrows():
-                emp_id = str(row[1]).strip() if pd.notna(row[1]) else ""
-                name = str(row[3]).strip()
-                key = emp_id or f"{project}-{name}"
-                total_rows += 1
-                emp_proj.setdefault(key, {}).setdefault(project, set()).add(month or -1)
-                proj_month.setdefault(project, {}).setdefault(month or -1, set()).add(key)
-
-    print(f"考勤记录总数: {total_rows}")
-    print(f"考勤文件涉及的唯一员工(按工号/姓名+项目): {len(emp_proj)}")
-
-    multi = {k: v for k, v in emp_proj.items() if len(v) > 1}
-    print(f"\n== 跨多个项目的人员数: {len(multi)} ==")
-    for k, v in sorted(multi.items())[:20]:
-        detail = ", ".join(f"{pj}({sorted(ms)})" for pj, ms in v.items())
-        print(f"  {k}: {detail}")
-
-    print(f"\n== 项目 × 月份 覆盖(人数) ==")
-    for pj, months in sorted(proj_month.items()):
-        cells = ", ".join(f"{m}月:{len(s)}人" for m, s in sorted(months.items()))
-        print(f"  {pj}: {cells}")
-
-    all_months = {m for pj in proj_month.values() for m in pj}
-    print(f"\n涉及月份: {sorted(all_months)}")
-
-
-if __name__ == "__main__":
-    main()

+ 0 - 67
scripts/audit_template_sources.py

@@ -1,67 +0,0 @@
-"""审计模板:每个表头字段是否都在「填写说明 → 字段依据」中有来源标注。"""
-
-from __future__ import annotations
-
-import re
-import sys
-from pathlib import Path
-
-import openpyxl
-
-
-sys.stdout.reconfigure(encoding="utf-8")
-TPL = Path(r"E:\CODE\knowledge_agent\data\templates")
-
-
-def norm(h: str) -> str:
-    s = h.replace("*", "")
-    for x in ("(选填)", "(必填)", "(工号)", "(非续签留空)"):
-        s = s.replace(x, "")
-    return re.sub(r"\s+", "", s)
-
-
-def main() -> None:
-    for f in sorted(TPL.glob("*.xlsx")):
-        if f.name.startswith("~$"):
-            continue  # Excel 临时锁文件
-        wb = openpyxl.load_workbook(f, read_only=True, data_only=True)
-        data = wb[wb.sheetnames[0]]
-        headers = [c.value for c in data[1] if c.value]
-        note = wb["填写说明"]
-        start = None
-        for r in range(1, 200):
-            if note.cell(row=r, column=1).value == "【字段依据】":
-                start = r
-                break
-        entries: list[str] = []
-        if start:
-            r = start + 2
-            while note.cell(row=r, column=1).value:
-                entries.append(str(note.cell(row=r, column=1).value))
-                r += 1
-
-        missing = []
-        for h in headers:
-            hn = norm(h)
-            if re.fullmatch(r"\d+日", hn):
-                continue  # 1日..31日 由「1-31日」条目覆盖
-            covered = False
-            for e in entries:
-                toks = [t for t in re.split(r"[/、,,]", norm(e)) if t]
-                for tk in toks:
-                    if hn == tk or (len(tk) >= 2 and (tk in hn or hn in tk)):
-                        covered = True
-                        break
-                if covered:
-                    break
-            if not covered:
-                missing.append(h)
-
-        print(f"=== {f.name}: {len(headers)} 列 / 依据 {len(entries)} 条 / 未覆盖 {len(missing)}")
-        for m in missing:
-            print(f"    ✗ {m}")
-        wb.close()
-
-
-if __name__ == "__main__":
-    main()

+ 206 - 0
scripts/build_field_association.py

@@ -0,0 +1,206 @@
+"""生成 模板-源数据-DMS 三方字段关联 CSV。
+
+输出:
+  output/模板_源数据_DMS字段关联.csv
+"""
+
+from __future__ import annotations
+
+import ast
+import csv
+import importlib.util
+import json
+import re
+import sys
+from pathlib import Path
+
+
+sys.stdout.reconfigure(encoding="utf-8")
+ROOT = Path(r"E:\CODE\knowledge_agent")
+OUT = ROOT / "output" / "模板_源数据_DMS字段关联.csv"
+DATA_FILES = [
+    p.name for p in (ROOT / "data").rglob("*")
+    if p.is_file() and p.suffix.lower() in {".xlsx", ".xls", ".csv", ".docx", ".doc", ".pdf"}
+]
+DMS_ALIASES: dict[str, str] = {}
+try:
+    raw_dms = json.loads((ROOT / "output" / "dms_scoped_models_fields.json").read_text(encoding="utf-8-sig"))
+    DMS_ALIASES = {
+        k: (v.get("modelAlias") or v.get("path") or k)
+        for k, v in raw_dms.items()
+        if isinstance(v, dict)
+    }
+except Exception:  # noqa: BLE001
+    pass
+
+
+def load_module(name: str, path: Path):
+    spec = importlib.util.spec_from_file_location(name, path)
+    mod = importlib.util.module_from_spec(spec)
+    assert spec and spec.loader
+    spec.loader.exec_module(mod)
+    return mod
+
+
+dms_mod = load_module("dms_supplement", ROOT / "scripts" / "generate_dms_supplement.py")
+tpl_mod = load_module("template_gen", ROOT / "scripts" / "generate_templates.py")
+
+
+def norm_header(h: str) -> str:
+    h = str(h or "").strip()
+    h = re.sub(r"\*$", "", h)
+    h = re.sub(r"([^)]*)$", "", h)
+    return re.sub(r"\s+", "", h)
+
+
+def parse_field_sources() -> dict[str, list[tuple[str, str]]]:
+    tree = ast.parse(Path(tpl_mod.__file__).read_text(encoding="utf-8"))
+    namespace = {k: v for k, v in tpl_mod.__dict__.items() if not k.startswith("__")}
+    result: dict[str, list[tuple[str, str]]] = {}
+    for node in ast.walk(tree):
+        if not isinstance(node, ast.Call):
+            continue
+        if not isinstance(node.func, ast.Name) or node.func.id != "_make_file":
+            continue
+        if len(node.args) < 3:
+            continue
+        filename_node = node.args[0]
+        headers_node = node.args[2]
+        try:
+            filename = ast.literal_eval(filename_node)
+            headers = ast.literal_eval(headers_node)
+        except Exception:  # noqa: BLE001
+            continue
+        if not isinstance(filename, str) or not isinstance(headers, list):
+            continue
+        field_sources = []
+        for kw in node.keywords:
+            if kw.arg != "field_sources":
+                continue
+            try:
+                value = eval(compile(ast.Expression(body=kw.value), "<tpl>", "eval"),
+                             namespace, namespace)
+            except Exception:  # noqa: BLE001
+                value = []
+            if isinstance(value, list):
+                field_sources = [
+                    (str(a), str(b))
+                    for a, b in value
+                    if isinstance(a, str) and isinstance(b, str)
+                ]
+        stem = Path(filename).stem
+        result[stem] = field_sources
+    return result
+
+
+def _split_source(desc: str) -> tuple[str, str]:
+    desc = desc.strip()
+    m = re.match(r"(.+?)\s*→\s*(.+)", desc, re.S)
+    if not m:
+        return desc, desc
+    return m.group(1).strip(), m.group(2).strip()
+
+
+def _file_names(src: str) -> list[str]:
+    names: list[str] = []
+    for part in re.split(r"[;;]", src):
+        part = part.strip()
+        if not part:
+            continue
+        if "新增(融合)" in part or "新增(分类)" in part:
+            continue
+        if "关联「" in part or part in {"—", "-"}:
+            continue
+        name = re.split(r"[\\/]", part)[-1].strip()
+        name = re.sub(r"[((][^))]*[))]$", "", name).strip()
+        if re.search(r"\.(xlsx|xls|csv|docx|doc|pdf)$", name, re.I):
+            names.append(name)
+            continue
+        # 字段来源里可能是“登记表名称”而非完整文件名,尝试在工作区数据文件中匹配
+        hit = next((f for f in DATA_FILES if name and name in f), None)
+        if hit:
+            names.append(hit)
+    return names
+
+
+def parse_source(desc: str) -> tuple[str, str]:
+    src, field = _split_source(desc)
+    names = _file_names(src)
+    src_out = ";".join(names)
+    if "新增(融合)" in desc or "新增(分类)" in desc:
+        return "", field
+    if not names:
+        return "", field
+    quoted = re.findall(r"「([^」]+)」", field)
+    if quoted:
+        field = " / ".join(quoted)
+    return src_out, field
+
+
+def split_fields(label: str) -> list[str]:
+    return [re.sub(r"\s+", "", x) for x in re.split(r"[/、]", label) if re.sub(r"\s+", "", x)]
+
+
+def main() -> None:
+    sources = parse_field_sources()
+    rows: list[dict] = []
+    last_file: dict[str, str] = {}
+    for tpl, fields in dms_mod.TEMPLATES.items():
+        tpl_sources = sources.get(tpl, [])
+        for field in fields:
+            dms_source = dms_mod.DMS_SOURCES.get((tpl, field), "")
+            dms_model = dms_field = ""
+            if dms_source:
+                m = re.match(r"^([^.]+)\.(.*)$", dms_source)
+                if m:
+                    dms_model, dms_field = m.group(1), m.group(2)
+            dms_model_display = dms_model
+            if dms_model and dms_model in DMS_ALIASES:
+                dms_model_display = f"{dms_model}({DMS_ALIASES[dms_model]})"
+            meta_file = meta_field = ""
+            matched_desc = ""
+            for label, desc in tpl_sources:
+                for lf in split_fields(label):
+                    if norm_header(field) == norm_header(lf) or (
+                        len(norm_header(lf)) >= 2 and norm_header(lf) in norm_header(field)
+                    ):
+                        matched_desc = desc
+                        break
+                if matched_desc:
+                    break
+            if matched_desc:
+                raw_src, _ = _split_source(matched_desc)
+                if raw_src.strip() in {"同一登记表", "同上", "同文件", "同一文件"}:
+                    meta_file = last_file.get(tpl, "")
+                    meta_field = parse_source(matched_desc)[1]
+                else:
+                    meta_file, meta_field = parse_source(matched_desc)
+                    if meta_file:
+                        last_file[tpl] = meta_file
+            if not meta_file:
+                meta_field = ""
+            rows.append({
+                "模板文件名称": f"{tpl}.csv",
+                "模板字段": field,
+                "元数据文件": meta_file,
+                "元数据字段名称": meta_field,
+                "dms模型": dms_model_display,
+                "dms字段名称": dms_field,
+                "是否需要人工增加": "否" if dms_source else "是",
+            })
+
+    OUT.parent.mkdir(parents=True, exist_ok=True)
+    with OUT.open("w", newline="", encoding="utf-8-sig") as f:
+        w = csv.writer(f)
+        w.writerow(["模板文件名称", "模板字段", "元数据文件", "元数据字段名称",
+                    "dms模型", "dms字段名称", "是否需要人工增加"])
+        for r in rows:
+            w.writerow([r["模板文件名称"], r["模板字段"], r["元数据文件"],
+                        r["元数据字段名称"], r["dms模型"], r["dms字段名称"],
+                        r["是否需要人工增加"]])
+    print("输出:", OUT)
+    print("字段行数:", len(rows))
+
+
+if __name__ == "__main__":
+    main()

+ 1 - 1
scripts/build_graph.py

@@ -1,4 +1,4 @@
-"""CLI:根据 JSON 配置(12 类文件数组)构建知识图谱。
+"""CLI:根据 JSON 配置(15 类文件数组)构建知识图谱。
 
 用法: uv run python scripts/build_graph.py [config.json] [--clear]
 """

+ 128 - 0
scripts/export_meta_schema.py

@@ -0,0 +1,128 @@
+"""导出元知识图谱 Schema 为前端展示用 JSON。
+
+输出:
+  output/meta_graph_schema.json             # 完整 schema(含规划中节点)
+  output/meta_graph_schema_display.json     # 仅已启用节点/关系,适合前端展示
+
+内容包括:
+  - nodes: 节点/实体类型,含属性列表、部门、是否中心节点、是否建议节点、是否已启用
+  - relations: 节点间连接关系,含源节点、目标节点、关系名、关联键、基数、说明、是否已启用
+"""
+
+from __future__ import annotations
+
+import json
+import re
+import sys
+from datetime import date
+from pathlib import Path
+
+from knowledge_agent.meta.schema import ENTITIES, RELATIONS
+
+
+sys.stdout.reconfigure(encoding="utf-8")
+ROOT = Path(r"E:\CODE\knowledge_agent")
+OUT = ROOT / "output" / "meta_graph_schema.json"
+OUT_DISPLAY = ROOT / "output" / "meta_graph_schema_display.json"
+
+
+def split_attributes(desc: str) -> list[str]:
+    """从 EntitySpec.desc 中提取属性名。
+
+    desc 基本是“属性1 / 属性2 / ...”格式;括号内的斜杠不拆分。
+    """
+    if not desc:
+        return []
+    # 先保护括号内的“/”,例如 合同状况(线上/线下)、服务状态(服务中/历史)
+    protected = re.sub(
+        r"([((][^))]*)/([^))]*[))])",
+        lambda m: m.group(0).replace("/", "__SLASH__"),
+        desc,
+    )
+    parts = re.split(r"\s*/\s*|;|;", protected)
+    result: list[str] = []
+    for p in parts:
+        p = p.strip().replace("__SLASH__", "/")
+        if not p:
+            continue
+        # 去掉解释性括号,但保留括号内容作为属性说明
+        result.append(re.sub(r"\s+", "", p))
+    return result
+
+
+def build_payload() -> dict:
+    active_names = {e.name for e in ENTITIES if e.active}
+
+    nodes = []
+    for e in ENTITIES:
+        dept = [e.department] if isinstance(e.department, str) else list(e.department)
+        nodes.append({
+            "id": e.name,
+            "name": e.name,
+            "department": dept,
+            "is_hub": e.is_hub,
+            "suggested": e.suggested,
+            "active": e.active,
+            "attributes": split_attributes(e.desc),
+            "description": e.desc,
+        })
+
+    relations = []
+    for r in RELATIONS:
+        relations.append({
+            "id": f"{r.source}__{r.rel_type}__{r.target}",
+            "source": r.source,
+            "target": r.target,
+            "type": r.rel_type,
+            "key": r.key,
+            "cardinality": r.cardinality,
+            "description": r.desc,
+            "active": r.source in active_names and r.target in active_names,
+        })
+
+    return {
+        "meta": {
+            "title": "申勤物业元知识图谱 Schema",
+            "source": "src/knowledge_agent/meta/schema.py",
+            "generated_at": date.today().isoformat(),
+            "entity_count": len(nodes),
+            "active_entity_count": sum(1 for n in nodes if n["active"]),
+            "relation_count": len(relations),
+            "active_relation_count": sum(1 for r in relations if r["active"]),
+        },
+        "nodes": nodes,
+        "relations": relations,
+    }
+
+
+def main() -> None:
+    payload = build_payload()
+    OUT.parent.mkdir(parents=True, exist_ok=True)
+    OUT.write_text(json.dumps(payload, ensure_ascii=False, indent=2), encoding="utf-8")
+
+    display_nodes = [n for n in payload["nodes"] if n["active"]]
+    display_relations = [r for r in payload["relations"] if r["active"]]
+    display = {
+        "meta": {
+            **payload["meta"],
+            "title": "申勤物业元知识图谱 Schema(仅已启用节点/关系)",
+            "entity_count": len(display_nodes),
+            "active_entity_count": len(display_nodes),
+            "relation_count": len(display_relations),
+            "active_relation_count": len(display_relations),
+        },
+        "nodes": display_nodes,
+        "relations": display_relations,
+    }
+    OUT_DISPLAY.write_text(json.dumps(display, ensure_ascii=False, indent=2), encoding="utf-8")
+
+    print("完整 schema:", OUT)
+    print(f"  节点: {payload['meta']['entity_count']}(启用 {payload['meta']['active_entity_count']})")
+    print(f"  关系: {payload['meta']['relation_count']}(启用 {payload['meta']['active_relation_count']})")
+    print("展示版 schema:", OUT_DISPLAY)
+    print(f"  节点: {len(display_nodes)}")
+    print(f"  关系: {len(display_relations)}")
+
+
+if __name__ == "__main__":
+    main()

+ 0 - 78
scripts/fetch_dms_fields.py

@@ -1,78 +0,0 @@
-"""读取 DMS 申勤相关模型的字段定义(只读),输出到 output/dms_models_fields.json。"""
-
-from __future__ import annotations
-
-import json
-import sys
-import urllib.request
-
-
-sys.stdout.reconfigure(encoding="utf-8")
-TOKEN = ("eyJ0eXAiOiJKV1QiLCJhbGciOiJIUzI1NiJ9."
-         "eyJyb2xlSWQiOiIwLDEsMiwxMiIsImV4cCI6MTc4NjU2NjU0NCwidXNlcklkIjoyNzQs"
-         "InVzZXJuYW1lIjoidXNlcl93YW5neGkifQ."
-         "FHjT1Bi_gYW3wAfdqTXpMFfmzW2L8V-gYJ0On1PnWq0")
-BASE = "http://121.43.55.7:10081/dms/model/getModelById"
-
-IDS = {
-    "sq_employee(申勤员工)": 1793,
-    "sq_project(申勤项目数据)": 1794,
-    "file1da77(申勤物业项目清单)": 1795,
-    "sq_xq(续签表)": 1950,
-    "xzbm(行政编码及片区)": 1902,
-    "sq_personnel_certificate(人员证书)": 1890,
-    "sq_position_salary(岗位区域薪资)": 1900,
-    "shenqin_zbb(招标表)": 1853,
-    "shenqin_txb(投续标表)": 1852,
-    "shenqin_project_annual_stat(年化数据统计)": 1836,
-    "sq_project_period(项目期次)": 1876,
-    "sq_shenqin_project(项目主数据)": 1896,
-    "sq_yt_column(申勤业态表)": 1909,
-    "sq_tender_intent(招标意向)": 1954,
-    "sq_tender_notice(招标公告)": 1955,
-    "sq_tender_result(结果公告)": 1956,
-}
-
-
-def fetch(mid: int) -> dict:
-    url = BASE + "?modelId=" + str(mid)
-    req = urllib.request.Request(
-        url, data=b"{}",
-        headers={"token": TOKEN, "Content-Type": "application/json"})
-    with urllib.request.urlopen(req, timeout=30) as r:
-        return json.loads(r.read().decode("utf-8", "replace"))
-
-
-def main() -> None:
-    out = {}
-    for name, mid in IDS.items():
-        try:
-            data = fetch(mid)
-            content = data.get("content") or {}
-            fields = content.get("fieldList") or "{}"
-            if isinstance(fields, str):
-                fields = json.loads(fields)
-            names = []
-            if isinstance(fields, dict):
-                for k, v in fields.items():
-                    alias = v.get("alias") if isinstance(v, dict) else (v if isinstance(v, str) else str(v))
-                    names.append((k, alias))
-            elif isinstance(fields, list):
-                for v in fields:
-                    if isinstance(v, dict):
-                        names.append((v.get("name"), v.get("alias")))
-                    else:
-                        names.append((str(v), str(v)))
-            out[name] = {"modelId": mid, "modelName": content.get("modelName"),
-                         "fields": names}
-            print(f"== {name} [{content.get('modelName')}] 字段数={len(names)}")
-            for n, a in names:
-                print(f"    {n} | {a}")
-        except Exception as e:  # noqa: BLE001
-            print(f"== {name} ERR {e}")
-    with open(r"E:\CODE\knowledge_agent\output\dms_models_fields.json", "w", encoding="utf-8") as f:
-        json.dump(out, f, ensure_ascii=False, indent=1)
-
-
-if __name__ == "__main__":
-    main()

+ 0 - 306
scripts/generate_dms_mapping.py

@@ -1,306 +0,0 @@
-"""生成 13 类模板字段 ↔ DMS 模型字段 映射文档。
-
-来源分三类:
-1. DMS来源                 —— DMS 模型中有对应字段(模型.字段)
-2. 源Excel来源(DMS未建模型) —— 源 Excel 中确实存在,但 DMS 没有建模型,
-                               需人工从源 Excel 填入模板(标注具体文件+列)
-3. 新增融合(图谱关联字段)    —— DMS 与源 Excel 均无,为图谱建模/关联额外添加
-"""
-
-from __future__ import annotations
-
-import json
-import re
-import sys
-from pathlib import Path
-
-
-sys.stdout.reconfigure(encoding="utf-8")
-OUT = Path(r"E:\CODE\knowledge_agent\output\dms_models_fields.json")
-DOC = Path(r"E:\CODE\knowledge_agent\docs\DMS字段映射.md")
-
-
-def norm(s: str) -> str:
-    return re.sub(r"[\s()()/*、,,::元万㎡条%]", "", s or "")
-
-
-TEMPLATES: dict[str, list[str]] = {
-    "项目信息": ["项目编号", "项目名称", "项目简称", "上级项目编号", "续签前项目编号", "项目起止时间",
-               "省份", "市(区)", "细分业态", "汇总业态", "委托方式", "计费方式", "合同面积",
-               "合同金额", "年化合同额", "合同额具体信息", "服务期限", "合同状况", "首次服务日期",
-               "年化合同收入", "客户满意度", "客户投诉", "甲方名称", "项目地址", "项目负责人",
-               "项目负责人工号", "实际毛利率", "服务状态", "备注"],
-    "项目月度财务": ["项目编号", "项目名称", "年月", "开票金额", "收款金额", "口径说明",
-                  "财务经办人工号", "财务经办人", "备注"],
-    "投标记录": ["项目编号", "项目名称", "年份", "投标类型", "中标结果", "中标日期", "投标金额",
-               "文档路径", "投标经办人工号", "投标经办人", "备注"],
-    "人员信息": ["姓名", "工号", "组织名称", "岗位名称", "当前服务项目编号", "服务起始年月",
-               "服务结束年月", "职级", "员工层级", "所属组织名称", "入职日期", "离职日期", "司龄",
-               "性别", "出生日期", "政治面貌", "联系电话", "备注"],
-    "考勤与人员财务": ["姓名", "工号", "项目编号", "项目名称", "年月", "1-31日", "上班天数",
-                     "平时加班小时", "国定加班小时", "餐费补助金额", "加班超时费金额",
-                     "国定加班费金额", "值班费金额", "税后工资", "备注"],
-    "排班明细": ["姓名", "工号", "项目编号", "项目名称", "年月", "1-31日班次", "备注"],
-    "岗位编制": ["项目编号", "项目名称", "岗位", "预算编制", "项目编制", "标准工时人数", "在岗人数", "备注"],
-    "设备信息": ["项目编号", "项目名称", "设备编号", "设备类型", "名称", "规格型号参数", "制造厂商",
-               "安装位置", "出厂日期", "启用日期", "入项目日期", "退项目日期", "出厂编号", "完好状况",
-               "原值", "设备责任人工号", "设备责任人", "备注"],
-    "采购与维保": ["记录类型", "项目编号", "项目名称", "供应商名称", "供应商编号", "类别",
-                 "名称/合同名称", "数量", "单位", "单价", "金额", "合同年限", "月份/日期",
-                 "当前状态", "经办人工号", "经办人", "备注"],
-    "检查记录": ["项目编号", "项目名称", "检查类型", "检查日期", "检查得分", "问题描述",
-               "整改情况", "整改完成日期", "检查人工号", "检查人", "备注"],
-    "片区信息": ["片区编号", "片区名称", "片区负责人工号", "片区负责人", "备注"],
-    "项目片区关系": ["项目编号", "项目名称", "片区编号", "片区名称", "备注"],
-    "人员证书": ["工号", "姓名", "专业类别", "证书类别", "证书名称", "备注"],
-}
-
-NOTES: dict[str, str] = {
-    "项目信息": "专用模型:sq_project(申勤项目数据) + shenqin_project_annual_stat(年化统计) + sq_project_period(项目期次) + sq_xq(续签表)",
-    "人员信息": "专用模型:sq_employee(申勤员工)",
-    "投标记录": "专用模型:shenqin_txb(投续标表) + shenqin_zbb(招标表) + sq_tender_intent/notice/result(招标意向/公告/结果)",
-    "片区信息": "专用模型:xzbm(行政编码及片区)",
-    "项目片区关系": "无专用关联表:可基于 sq_project.管理区域 / xzbm 行政编码 推导",
-    "人员证书": "专用模型:sq_personnel_certificate(AMS枢元/人员证书)",
-    "考勤与人员财务": "DMS 中未发现考勤专用模型(姓名/工号等为跨模型公共字段)",
-    "排班明细": "DMS 中未发现排班专用模型",
-    "项目月度财务": "DMS 无月度开票/收款明细(仅年化/合同金额)",
-    "岗位编制": "DMS 无编制/在岗模型(sq_project 仅有定岗人数,为预算口径)",
-    "设备信息": "DMS 中未发现设备台账模型",
-    "检查记录": "DMS 中未发现品质/安全检查模型",
-    "采购与维保": "DMS 中未发现采购/维保模型",
-}
-
-# 有专用 DMS 模型的模板(其余模板按"源Excel来源"处理)
-MODELED = {"项目信息", "人员信息", "投标记录", "片区信息", "人员证书"}
-
-# 字段的源 Excel 说明(DMS 未建模型时)
-DEFAULT_SOURCES: dict[str, str] = {
-    "项目信息": "市场部项目管理表 + 业务大表(表1)",
-    "项目月度财务": "财务部收费进程表(1-12月物业费/期内开票收款)",
-    "投标记录": "业务大表表2 中标情况 + 档案目录(中标通知书等)",
-    "人员信息": "人事部员工信息.xlsx(花名册)",
-    "考勤与人员财务": "人事部考勤表(如 青浦-赵巷公园-员工岗位考勤表.xls)",
-    "排班明细": "人事部排班文件(每日班次代码)",
-    "岗位编制": "运营部 9-项目岗位编制汇总.xlsx",
-    "设备信息": "运营部设备台账(青浦工业园区/徐汇环境监测中心)",
-    "采购与维保": "采购部 耗材汇总/维保合同台账/固定资产台账",
-    "检查记录": "运营部品质巡检及整改记录台账",
-    "片区信息": "业务大表「管理区域」/ 8-项目信息汇总表",
-    "项目片区关系": "业务大表「管理区域」推导(M:N)",
-    "人员证书": "合景悠活职称及资格证书管理登记表",
-}
-
-# 源 Excel 字段级说明(DMS 未建模型时,标注到具体文件+列)
-SOURCE_EXCEL_NOTES: dict[tuple[str, str], str] = {
-    ("考勤与人员财务", "工号"): "人事部考勤表「员工编码」列(13 份考勤 xls/xlsx)",
-    ("考勤与人员财务", "年月"): "考勤表工作表名/表头(如 青浦-赵巷公园-员工岗位考勤表2026年1月-4月员工岗位考勤表.xls →「2026年×月」)",
-    ("考勤与人员财务", "1-31日"): "考勤表 1~31 日列,班次标记(常/日/夜/日1 等)",
-    ("考勤与人员财务", "上班天数"): "考勤表「上班天数」列",
-    ("考勤与人员财务", "平时加班小时"): "考勤表「平时加班小时」列",
-    ("考勤与人员财务", "国定加班小时"): "考勤表「国定加班小时」列",
-    ("考勤与人员财务", "餐费补助金额"): "考勤表「餐费补助金额」列",
-    ("考勤与人员财务", "加班超时费金额"): "考勤表「加班超时费金额」列",
-    ("考勤与人员财务", "国定加班费金额"): "考勤表「国定加班费金额」列",
-    ("考勤与人员财务", "值班费金额"): "考勤表「值班费金额」列",
-    ("考勤与人员财务", "税后工资"): "考勤表末尾金额列(表头为「员工签字」,实际填月度税后工资,如 4896.25)",
-    ("考勤与人员财务", "备注"): "考勤表「备注」列",
-    ("排班明细", "工号"): "人事部排班 xlsx「工号(Employee ID)」列",
-    ("排班明细", "年月"): "排班 xlsx 日期列(2026-01-01 … 2026-01-31),如 排班:青浦-赵巷公园、赵巷文体中心、赵巷镇政府、赵巷品牌公司系统排班(2026年1-4月).xlsx",
-    ("排班明细", "1-31日班次"): "排班 xlsx 1~31 日「班次代码(Shift Code)」列(OFF/A003/SQ-104/M11-033 等)",
-    ("岗位编制", "岗位"): "运营部 9-项目岗位编制汇总.xlsx",
-    ("设备信息", "设备编号"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "设备类型"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "规格型号参数"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "制造厂商"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "安装位置"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "出厂日期"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "启用日期"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "出厂编号"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "完好状况"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("设备信息", "原值"): "运营部设备台账(如 青浦工业园区/徐汇环境监测中心)",
-    ("检查记录", "检查类型"): "运营部品质巡检及整改记录台账",
-    ("检查记录", "检查日期"): "运营部品质巡检及整改记录台账",
-    ("检查记录", "检查得分"): "运营部品质巡检及整改记录台账",
-    ("检查记录", "问题描述"): "运营部品质巡检及整改记录台账",
-    ("检查记录", "整改情况"): "运营部品质巡检及整改记录台账",
-    ("检查记录", "整改完成日期"): "运营部品质巡检及整改记录台账",
-    ("项目月度财务", "年月"): "财务部收费进程表(1-12月物业费/期内开票收款)",
-    ("项目月度财务", "开票金额"): "财务部收费进程表(1-12月物业费/期内开票收款)",
-    ("项目月度财务", "收款金额"): "财务部收费进程表(1-12月物业费/期内开票收款)",
-    ("项目信息", "客户满意度"): "运营部\\03 客户满意度及投诉记录\\客户满意度\\申勤物业服务满意度评价问卷报告(2025年度).docx → 满意度得分(聚合为项目属性)",
-    ("项目信息", "客户投诉"): "运营部\\03 客户满意度及投诉记录\\客户投诉\\SHSQ-JGJL-02-0301客户投诉受理单.doc 等 → 投诉条数",
-}
-
-# 真正新增融合的字段(DMS 与源 Excel 均无,为图谱建模/关联添加)
-FUSION_FIELDS: dict[str, set[str]] = {
-    "项目信息": {"项目负责人工号", "服务状态", "续签前项目编号"},
-    "项目月度财务": {"项目名称", "口径说明", "财务经办人工号", "财务经办人"},
-    "投标记录": {"项目名称", "投标类型", "投标经办人工号", "投标经办人", "中标日期", "文档路径"},
-    "人员信息": {"当前服务项目编号", "服务起始年月", "服务结束年月", "离职日期"},
-    "考勤与人员财务": {"项目名称"},
-    "排班明细": {"项目名称", "备注"},
-    "岗位编制": {"项目名称"},
-    "设备信息": {"项目名称", "入项目日期", "退项目日期", "设备责任人工号", "设备责任人"},
-    "采购与维保": {"记录类型", "项目名称", "供应商编号", "经办人工号", "经办人"},
-    "检查记录": {"项目名称", "检查人工号", "检查人"},
-    "片区信息": {"片区编号", "片区负责人工号", "片区负责人"},
-    "项目片区关系": {"项目名称", "片区名称"},
-    "人员证书": {"姓名", "备注"},
-}
-
-# 不参与 DMS 别名匹配的字段(避免被误匹配到跨模型公共字段,如 sq_employee.c_bz)
-EXCLUDE_DMS: set[tuple[str, str]] = {
-    ("考勤与人员财务", "备注"),
-    ("排班明细", "备注"),
-}
-
-# 语义映射覆盖:模板字段 -> (模型, DMS字段)
-OVERRIDES: dict[tuple[str, str], tuple[str, str]] = {
-    ("人员信息", "工号"): ("sq_employee", "c_ygbm 员工编码"),
-    ("人员信息", "姓名"): ("sq_employee", "c_xm 姓名"),
-    ("人员信息", "岗位名称"): ("sq_employee", "c_gwmc 岗位名称"),
-    ("人员信息", "员工层级"): ("sq_employee", "c_ygcj 员工层级"),
-    ("人员信息", "职级"): ("sq_employee", "c_zj 职级"),
-    ("人员信息", "所属组织名称"): ("sq_employee", "c_sszzmc 所属组织名称"),
-    ("人员信息", "入职日期"): ("sq_employee", "c_rzrq 入职日期"),
-    ("人员信息", "司龄"): ("sq_employee", "c_sl 司龄"),
-    ("人员信息", "性别"): ("sq_employee", "c_xb 性别"),
-    ("人员信息", "出生日期"): ("sq_employee", "c_csrq 出生日期"),
-    ("人员信息", "政治面貌"): ("sq_employee", "c_zzmm 政治面貌"),
-    ("人员信息", "联系电话"): ("sq_employee", "c_sjhm 手机号码"),
-    ("人员信息", "当前服务项目编号"): ("sq_employee", "c_xmmc 项目名称(五级公司)"),
-    ("项目信息", "项目编号"): ("sq_project", "c_jdbm 金蝶编码"),
-    ("项目信息", "项目名称"): ("sq_project", "c_xmmc 项目名称"),
-    ("项目信息", "上级项目编号"): ("sq_project", "c_father_code 父项目编码"),
-    ("项目信息", "省份"): ("sq_project", "c_sfzxs 省份(直辖市)"),
-    ("项目信息", "市(区)"): ("sq_project", "c_sq 市(区)"),
-    ("项目信息", "管理区域"): ("sq_project", "c_glqynbkj 管理区域(内部口径)"),
-    ("项目信息", "细分业态"): ("sq_project", "c_xfyt 细分业态"),
-    ("项目信息", "汇总业态"): ("sq_project", "c_hzyt 汇总业态"),
-    ("项目信息", "委托方式"): ("sq_project", "c_wtfs 委托方式"),
-    ("项目信息", "计费方式"): ("sq_project", "c_jffs 计费方式"),
-    ("项目信息", "合同面积"): ("sq_project", "c_htmj 合同面积(平方米)"),
-    ("项目信息", "合同金额"): ("shenqin_project_annual_stat", "c_contract_amount 合同金额"),
-    ("项目信息", "年化合同额"): ("shenqin_project_annual_stat", "c_annualized_amount 年化合同额"),
-    ("项目信息", "合同额具体信息"): ("shenqin_project_annual_stat", "c_current_period_amount/预估/存量/新增"),
-    ("项目信息", "服务期限"): ("shenqin_project_annual_stat", "c_service_period 服务期限"),
-    ("项目信息", "合同状况"): ("shenqin_project_annual_stat", "c_contract_status_online/offline"),
-    ("项目信息", "首次服务日期"): ("sq_project", "c_scfwrq 首次服务日期"),
-    ("项目信息", "年化合同收入"): ("sq_project", "c_nhhtsr 年化合同收入"),
-    ("项目信息", "甲方名称"): ("shenqin_project_annual_stat", "c_client_name 甲方名称"),
-    ("项目信息", "项目地址"): ("shenqin_project_annual_stat", "c_project_address 项目地址"),
-    ("项目信息", "项目负责人"): ("sq_project", "c_xmdzfzr 项目点状负责人"),
-    ("项目信息", "实际毛利率"): ("sq_project", "c_xmdnsjmll 项目当年实际毛利率"),
-    ("项目信息", "项目起止时间"): ("sq_project_period", "c_c_date_range_text 日期区间"),
-    ("项目信息", "项目简称"): ("shenqin_project_annual_stat", "c_project_short_name 项目简称"),
-    ("投标记录", "项目编号"): ("shenqin_txb", "c_jdbm 金蝶编码"),
-    ("投标记录", "投标金额"): ("shenqin_txb", "tbbj 投标报价"),
-    ("投标记录", "中标结果"): ("sq_tender_result", "c_winning_suppliers 中标供应商名称"),
-    ("投标记录", "年份"): ("sq_tender_notice", "c_publish_time 发布时间"),
-    ("片区信息", "片区编号"): ("xzbm", "c_part_code 片区编码"),
-    ("片区信息", "片区名称"): ("xzbm", "c_part_name 片区名称"),
-    ("人员证书", "工号"): ("sq_personnel_certificate", "c_c_person_id 人员ID"),
-    ("人员证书", "证书类别"): ("sq_personnel_certificate", "c_c_cert_type 证书类型"),
-}
-
-
-def load_dms() -> dict[str, dict[str, str]]:
-    data = json.loads(OUT.read_text(encoding="utf-8"))
-    aliases: dict[str, str] = {}
-    for model, info in data.items():
-        for fname, alias in info.get("fields", []):
-            key = norm(alias)
-            if key:
-                aliases.setdefault(key, f"{model}.{fname}({alias})")
-    return aliases
-
-
-def main() -> None:
-    aliases = load_dms()
-    lines = ["# DMS 数据库字段映射(13 类模板)", "",
-             "> 依据 DMS 模型元数据生成(模型:申勤物业数字化 / AMS枢元 相关)。"
-             "来源分三类:① DMS来源 = 模型.字段(别名);② 源Excel来源(DMS未建模型)"
-             "= 源 Excel 中确有、但 DMS 无对应模型,需人工从源 Excel 填入;"
-             "③ 新增融合 = DMS 与源 Excel 均无,为图谱建模/关联额外添加。", ""]
-    summary = []
-    for tpl, fields in TEMPLATES.items():
-        lines.append(f"## {tpl}")
-        lines.append(f"**说明**:{NOTES.get(tpl, '')}")
-        lines.append("| 模板字段 | 来源(DMS 模型.字段 / 源Excel文件+列) | 类型 |")
-        lines.append("|---|---|---|")
-        found = 0
-        for f in fields:
-            ov = OVERRIDES.get((tpl, f))
-            src = ""
-            note = ""
-            if ov:
-                src = f"{ov[0]}.{ov[1]}"
-                found += 1
-            else:
-                if (tpl, f) not in EXCLUDE_DMS:
-                    for alias, desc in aliases.items():
-                        if norm(f) == alias or (len(norm(f)) >= 2 and norm(f) in alias):
-                            src = desc
-                            found += 1
-                            break
-            if src:
-                kind = "DMS来源"
-            elif f in FUSION_FIELDS.get(tpl, set()):
-                kind = "新增融合(图谱关联字段)"
-                note = "DMS 与源 Excel 均无,图谱建模/关联用"
-            else:
-                kind = "源Excel来源(DMS未建模型)"
-                note = SOURCE_EXCEL_NOTES.get((tpl, f)) or DEFAULT_SOURCES.get(tpl, "")
-            if src:
-                display = src
-            elif kind.startswith("源Excel"):
-                display = f"源Excel:{note}" if note else "—"
-            else:
-                display = note or "—"
-            lines.append(f"| {f} | {display} | {kind} |")
-        summary.append((tpl, len(fields), found))
-        lines.append("")
-    lines.insert(3, "## 覆盖概览")
-    lines.insert(4, "| 模板 | 字段数 | 有DMS来源 |")
-    lines.insert(5, "|---|---|---|")
-    for t, n, f in summary:
-        lines.insert(6, f"| {t} | {n} | {f} |")
-    DOC.write_text("\n".join(lines), encoding="utf-8")
-
-    import csv
-    csv_path = Path(r"E:\CODE\knowledge_agent\output\dms_template_mapping.csv")
-    with csv_path.open("w", newline="", encoding="utf-8-sig") as f:
-        w = csv.writer(f)
-        w.writerow(["模板", "模板字段", "DMS来源(模型.字段)", "类型", "说明"])
-        for tpl, fields in TEMPLATES.items():
-            for fld in fields:
-                ov = OVERRIDES.get((tpl, fld))
-                src = ""
-                if ov:
-                    src = f"{ov[0]}.{ov[1]}"
-                else:
-                    if (tpl, fld) not in EXCLUDE_DMS:
-                        for alias, desc in aliases.items():
-                            if norm(fld) == alias or (len(norm(fld)) >= 2 and norm(fld) in alias):
-                                src = desc
-                                break
-                if src:
-                    kind = "DMS来源"
-                    note = NOTES.get(tpl, "")
-                elif fld in FUSION_FIELDS.get(tpl, set()):
-                    kind = "新增融合"
-                    note = "图谱建模/关联字段"
-                else:
-                    kind = "源Excel来源(DMS未建模型)"
-                    note = SOURCE_EXCEL_NOTES.get((tpl, fld)) or DEFAULT_SOURCES.get(tpl, "")
-                w.writerow([tpl, fld, src, kind, note])
-    print("覆盖概览:")
-    for t, n, f in summary:
-        print(f"  {t}: {f}/{n}")
-    print("文档输出:", DOC)
-    print("CSV 输出:", csv_path)
-
-
-if __name__ == "__main__":
-    main()

+ 607 - 0
scripts/generate_dms_supplement.py

@@ -0,0 +1,607 @@
+"""按最新 DMS 范围重新比对 15 类模板字段,生成补充数据清单。
+
+最新 DMS 范围:
+  1. 申勤物业数字化/申勤物业项目清单、申勤员工
+  2. AMS枢元/申勤数字化改造(全部模型)
+
+输出:
+  - data/manual_fill/DMS补数字段清单.csv
+  - output/dms_scoped_template_mapping.csv
+  - docs/DMS字段映射_最新范围.md
+"""
+
+from __future__ import annotations
+
+import csv
+import json
+import re
+import sys
+from pathlib import Path
+
+from openpyxl import Workbook, load_workbook
+from openpyxl.styles import Alignment, Border, Font, PatternFill, Side
+from openpyxl.utils import get_column_letter
+
+
+sys.stdout.reconfigure(encoding="utf-8")
+
+ROOT = Path(r"E:\CODE\knowledge_agent")
+DMS_JSON = ROOT / "output" / "dms_scoped_models_fields.json"
+OUT_XLSX = ROOT / "data" / "manual_fill" / "DMS补数字段清单.csv"
+OUT_CSV = ROOT / "output" / "dms_scoped_template_mapping.csv"
+OUT_DOC = ROOT / "docs" / "DMS字段映射_最新范围.md"
+
+
+TEMPLATES: dict[str, list[str]] = {
+    "项目信息": ["项目编号", "项目名称", "项目简称", "上级项目编号", "续签前项目编号", "项目起止时间",
+               "省份", "市(区)", "细分业态", "汇总业态", "委托方式", "计费方式", "合同面积",
+               "合同金额", "年化合同额", "合同额具体信息", "服务期限", "合同状况", "首次服务日期",
+               "年化合同收入", "客户满意度", "客户投诉", "甲方名称", "项目地址", "项目负责人",
+               "项目负责人工号", "实际毛利率", "服务状态", "备注"],
+    "项目月度财务": ["项目编号", "项目名称", "年月", "开票金额", "收款金额", "口径说明",
+                  "财务经办人工号", "财务经办人", "备注"],
+    "月度快照": ["项目编号", "项目名称", "年月", "在岗人数", "排班人次", "考勤人次",
+               "开票金额", "收款金额", "备注"],
+    "科目余额": ["项目编号", "项目名称", "期间", "科目编码", "科目名称",
+               "借方发生额", "贷方发生额", "期末余额", "备注"],
+    "投标记录": ["项目编号", "项目名称", "年份", "投标类型", "中标结果", "中标日期", "投标金额",
+               "文档路径", "投标经办人工号", "投标经办人", "备注"],
+    "人员信息": ["姓名", "工号", "组织名称", "岗位名称", "当前服务项目编号", "服务起始年月",
+               "服务结束年月", "职级", "员工层级", "所属组织名称", "入职日期", "离职日期", "司龄",
+               "性别", "出生日期", "政治面貌", "联系电话", "备注"],
+    "考勤与人员财务": ["姓名", "工号", "项目编号", "项目名称", "年月", "1-31日", "上班天数",
+                     "平时加班小时", "国定加班小时", "餐费补助金额", "加班超时费金额",
+                     "国定加班费金额", "值班费金额", "税后工资", "备注"],
+    "排班月报": ["姓名", "工号", "项目编号", "项目名称", "年月", "1-31日班次", "备注"],
+    "岗位编制": ["项目编号", "项目名称", "岗位", "预算编制", "项目编制", "标准工时人数", "在岗人数", "备注"],
+    "设备信息": ["项目编号", "项目名称", "设备编号", "设备类型", "名称", "规格型号参数", "制造厂商",
+               "安装位置", "出厂日期", "启用日期", "入项目日期", "退项目日期", "出厂编号", "完好状况",
+               "原值", "设备责任人工号", "设备责任人", "备注"],
+    "采购与维保": ["记录类型", "项目编号", "项目名称", "供应商名称", "供应商编号", "类别",
+                 "名称/合同名称", "数量", "单位", "单价", "金额", "合同年限", "月份/日期",
+                 "当前状态", "经办人工号", "经办人", "备注"],
+    "检查记录": ["项目编号", "项目名称", "检查类型", "检查日期", "检查得分", "问题描述",
+               "整改情况", "整改完成日期", "检查人工号", "检查人", "备注"],
+    "片区信息": ["片区编号", "片区名称", "片区负责人工号", "片区负责人", "备注"],
+    "项目片区关系": ["项目编号", "项目名称", "片区编号", "片区名称", "备注"],
+    "人员证书": ["工号", "姓名", "专业类别", "证书类别", "证书名称", "备注"],
+}
+
+
+# 仅使用最新范围内的 DMS 模型。key = (模板, 模板字段)
+DMS_SOURCES: dict[tuple[str, str], str] = {
+    ("项目信息", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("项目信息", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+    ("项目信息", "项目简称"): "shenqin_project_annual_stat.c_project_short_name(项目简称)",
+    ("项目信息", "项目起止时间"): "shenqin_project_annual_stat.c_contract_period(合同起止日期) / sq_project_period.c_c_date_range_text(日期区间)",
+    ("项目信息", "省份"): "ams_sq_project.c_sfzxs(省份/直辖市)",
+    ("项目信息", "市(区)"): "ams_sq_project.c_sq(市/区)",
+    ("项目信息", "细分业态"): "ams_sq_project.c_xfyt(细分业态)",
+    ("项目信息", "汇总业态"): "ams_sq_project.c_hzyt(汇总业态)",
+    ("项目信息", "委托方式"): "ams_sq_project.c_wtfs(委托方式)",
+    ("项目信息", "计费方式"): "ams_sq_project.c_jffs(计费方式)",
+    ("项目信息", "合同面积"): "shenqin_project_annual_stat.c_building_area_sqm(建筑面积) / ams_sq_project.c_htmj(合同面积)",
+    ("项目信息", "合同金额"): "shenqin_project_annual_stat.c_contract_amount(合同金额)",
+    ("项目信息", "年化合同额"): "shenqin_project_annual_stat.c_annualized_amount(年化合同额)",
+    ("项目信息", "合同额具体信息"): "shenqin_project_annual_stat.c_current_period_amount / c_stock_amount / c_new_amount / c_estimated_amount",
+    ("项目信息", "服务期限"): "shenqin_project_annual_stat.c_service_period(服务期限)",
+    ("项目信息", "合同状况"): "shenqin_project_annual_stat.c_contract_status_online / c_contract_status_offline",
+    ("项目信息", "首次服务日期"): "ams_sq_project.c_scfwrq(首次服务日期)",
+    ("项目信息", "年化合同收入"): "ams_sq_project.c_nhhtsr(年化合同收入)",
+    ("项目信息", "甲方名称"): "shenqin_project_annual_stat.c_client_name(甲方名称)",
+    ("项目信息", "项目地址"): "shenqin_project_annual_stat.c_project_address(项目地址) / ams_sq_project.c_xmdz(项目地址)",
+    ("项目信息", "项目负责人"): "ams_sq_project.c_xmdzfzr(项目点状负责人)",
+    ("项目信息", "实际毛利率"): "ams_sq_project.c_xmdnsjmll(项目当年实际毛利率)",
+
+    ("项目月度财务", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("项目月度财务", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+
+    ("月度快照", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("月度快照", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+
+    ("科目余额", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("科目余额", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+
+    ("投标记录", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("投标记录", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+    ("投标记录", "中标结果"): "ams_sq_project.c_zbjgrzbdrhxsj(中标结果)",
+    ("投标记录", "中标日期"): "ams_sq_project.c_xmzbrq(项目中标日期)",
+    ("投标记录", "文档路径"): "sq_project_file.c_c_abs_path(绝对路径) / sq_bid_archive_scan.c_c_abs_path(标书扫描绝对路径)",
+
+    ("人员信息", "姓名"): "sq_employee.c_xm(姓名)",
+    ("人员信息", "工号"): "sq_employee.c_ygbm(员工编码)",
+    ("人员信息", "组织名称"): "sq_employee.c_sszzmc(所属组织名称)",
+    ("人员信息", "岗位名称"): "sq_employee.c_gwmc(岗位名称)",
+    ("人员信息", "服务起始年月"): "sq_employee.c_htksrq(合同开始日期,口径需确认)",
+    ("人员信息", "服务结束年月"): "sq_employee.c_htjsrq(合同结束日期,口径需确认)",
+    ("人员信息", "职级"): "sq_employee.c_zj(职级)",
+    ("人员信息", "员工层级"): "sq_employee.c_ygcj(员工层级)",
+    ("人员信息", "所属组织名称"): "sq_employee.c_sszzmc(所属组织名称)",
+    ("人员信息", "入职日期"): "sq_employee.c_rzrq(入职日期)",
+    ("人员信息", "司龄"): "sq_employee.c_sl(司龄)",
+    ("人员信息", "性别"): "sq_employee.c_xb(性别)",
+    ("人员信息", "出生日期"): "sq_employee.c_csrq(出生日期)",
+    ("人员信息", "政治面貌"): "sq_employee.c_zzmm(政治面貌)",
+    ("人员信息", "联系电话"): "sq_employee.c_sjhm(手机号码)",
+    ("人员信息", "备注"): "sq_employee.c_bz(备注)",
+
+    ("考勤与人员财务", "姓名"): "sq_employee.c_xm(姓名)",
+    ("考勤与人员财务", "工号"): "sq_employee.c_ygbm(员工编码)",
+    ("考勤与人员财务", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("考勤与人员财务", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / sq_employee.c_xmmc(项目名称)",
+
+    ("排班月报", "姓名"): "sq_employee.c_xm(姓名)",
+    ("排班月报", "工号"): "sq_employee.c_ygbm(员工编码)",
+    ("排班月报", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("排班月报", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / sq_employee.c_xmmc(项目名称)",
+
+    ("岗位编制", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("岗位编制", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+    ("岗位编制", "岗位"): "sq_position_salary.c_c_position_name(岗位名称) / sq_employee.c_gwmc(岗位名称)",
+    ("岗位编制", "在岗人数"): "ams_sq_project.c_xmygrs(项目员工人数,需按岗位拆分)",
+
+    ("设备信息", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("设备信息", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+
+    ("采购与维保", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("采购与维保", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+
+    ("检查记录", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("检查记录", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+
+    ("片区信息", "片区名称"): "ams_sq_project.c_glqynbkj(管理区域内部口径) / sq_shenqin_project.c_c_region(区域)",
+    ("片区信息", "片区负责人"): "ams_sq_project.c_pjfzr(片区负责人)",
+
+    ("项目片区关系", "项目编号"): "shenqin_project_annual_stat.c_kingdee_code(金蝶编码) / sq_shenqin_project.c_c_project_code(项目编号)",
+    ("项目片区关系", "项目名称"): "shenqin_project_annual_stat.c_project_name(项目名称) / ams_sq_project.c_xmmc(项目名称)",
+    ("项目片区关系", "片区名称"): "ams_sq_project.c_glqynbkj(管理区域内部口径) / sq_shenqin_project.c_c_region(区域)",
+
+    ("人员证书", "工号"): "sq_personnel_certificate.c_c_person_id(人员ID,需与 sq_employee.c_ygbm 核对映射)",
+    ("人员证书", "姓名"): "sq_personnel_material.c_c_name(姓名) / sq_employee.c_xm(姓名)",
+    ("人员证书", "证书类别"): "sq_personnel_certificate.c_c_cert_type(证书类型)",
+}
+
+
+# 与 DMS/其他补充表对齐的主连接键。即使 DMS 已有,也必须在补充 Excel 中保留。
+JOIN_KEYS: dict[str, set[str]] = {
+    "项目信息": {"项目编号"},
+    "项目月度财务": {"项目编号", "年月"},
+    "月度快照": {"项目编号", "年月"},
+    "科目余额": {"项目编号", "期间", "科目编码"},
+    "投标记录": {"项目编号", "年份"},
+    "人员信息": {"工号"},
+    "考勤与人员财务": {"工号", "项目编号", "年月"},
+    "排班月报": {"工号", "项目编号", "年月"},
+    "岗位编制": {"项目编号", "岗位"},
+    "设备信息": {"项目编号", "设备编号"},
+    "采购与维保": {"项目编号", "名称/合同名称", "月份/日期"},
+    "检查记录": {"项目编号", "检查日期"},
+    "片区信息": {"片区编号"},
+    "项目片区关系": {"项目编号", "片区编号"},
+    "人员证书": {"工号", "证书名称"},
+}
+
+
+# 非 DMS 字段中,可从已有源 Excel 搬运的字段
+SOURCE_EXCEL_FIELDS: set[tuple[str, str]] = {
+    ("项目信息", "上级项目编号"),
+    ("项目信息", "续签前项目编号"),
+    ("项目信息", "客户满意度"),
+    ("项目信息", "客户投诉"),
+    ("项目月度财务", "年月"),
+    ("项目月度财务", "开票金额"),
+    ("项目月度财务", "收款金额"),
+    ("月度快照", "年月"),
+    ("月度快照", "在岗人数"),
+    ("月度快照", "排班人次"),
+    ("月度快照", "考勤人次"),
+    ("月度快照", "开票金额"),
+    ("月度快照", "收款金额"),
+    ("科目余额", "期间"),
+    ("科目余额", "科目编码"),
+    ("科目余额", "科目名称"),
+    ("科目余额", "借方发生额"),
+    ("科目余额", "贷方发生额"),
+    ("科目余额", "期末余额"),
+    ("投标记录", "年份"),
+    ("投标记录", "投标金额"),
+    ("人员信息", "离职日期"),
+    ("考勤与人员财务", "年月"),
+    ("考勤与人员财务", "1-31日"),
+    ("考勤与人员财务", "上班天数"),
+    ("考勤与人员财务", "平时加班小时"),
+    ("考勤与人员财务", "国定加班小时"),
+    ("考勤与人员财务", "餐费补助金额"),
+    ("考勤与人员财务", "加班超时费金额"),
+    ("考勤与人员财务", "国定加班费金额"),
+    ("考勤与人员财务", "值班费金额"),
+    ("考勤与人员财务", "税后工资"),
+    ("考勤与人员财务", "备注"),
+    ("排班月报", "年月"),
+    ("排班月报", "1-31日班次"),
+    ("岗位编制", "预算编制"),
+    ("岗位编制", "项目编制"),
+    ("岗位编制", "标准工时人数"),
+    ("设备信息", "设备编号"),
+    ("设备信息", "设备类型"),
+    ("设备信息", "名称"),
+    ("设备信息", "规格型号参数"),
+    ("设备信息", "制造厂商"),
+    ("设备信息", "安装位置"),
+    ("设备信息", "出厂日期"),
+    ("设备信息", "启用日期"),
+    ("设备信息", "出厂编号"),
+    ("设备信息", "完好状况"),
+    ("设备信息", "原值"),
+    ("采购与维保", "供应商名称"),
+    ("采购与维保", "类别"),
+    ("采购与维保", "名称/合同名称"),
+    ("采购与维保", "数量"),
+    ("采购与维保", "单位"),
+    ("采购与维保", "单价"),
+    ("采购与维保", "金额"),
+    ("采购与维保", "合同年限"),
+    ("采购与维保", "月份/日期"),
+    ("采购与维保", "当前状态"),
+    ("检查记录", "检查类型"),
+    ("检查记录", "检查日期"),
+    ("检查记录", "检查得分"),
+    ("检查记录", "问题描述"),
+    ("检查记录", "整改情况"),
+    ("检查记录", "整改完成日期"),
+    ("人员证书", "专业类别"),
+    ("人员证书", "证书名称"),
+}
+
+
+DEFAULT_SOURCES: dict[str, str] = {
+    "项目信息": "市场部项目管理表 / 业务大表",
+    "项目月度财务": "财务部收费进程表(1-12月物业费/期内开票收款)",
+    "月度快照": "由考勤/排班/项目月度财务汇总生成(可参考 scripts/sample_snapshot.py)",
+    "科目余额": "财务部科目余额表(科目编码/名称/借贷发生额/期末余额)",
+    "投标记录": "业务大表中标情况 / 档案目录",
+    "人员信息": "人事部员工花名册",
+    "考勤与人员财务": "人事部考勤表(13份考勤 xls/xlsx)",
+    "排班月报": "人事部排班文件(每日班次代码)",
+    "岗位编制": "运营部 9-项目岗位编制汇总.xlsx",
+    "设备信息": "运营部设备台账(青浦工业园区/徐汇环境监测中心)",
+    "采购与维保": "采购部耗材汇总/维保合同台账/固定资产台账",
+    "检查记录": "运营部品质巡检及整改记录台账",
+    "片区信息": "业务大表「管理区域」/ 8-项目信息汇总表",
+    "项目片区关系": "业务大表「管理区域」推导",
+    "人员证书": "合景悠活职称及资格证书管理登记表",
+}
+
+
+SPECIAL_NOTES: dict[tuple[str, str], str] = {
+    ("项目信息", "项目负责人工号"): "DMS 有项目负责人姓名;工号需按姓名在员工花名册中匹配",
+    ("项目信息", "上级项目编号"): "可由业务大表层级/委托方式推导后回填",
+    ("项目信息", "续签前项目编号"): "可由续签链/档案目录推导后回填",
+    ("人员信息", "当前服务项目编号"): "DMS sq_employee 只有项目名称/GUID,编号需按项目名称映射",
+    ("人员信息", "离职日期"): "DMS 只有合同结束日期,不是离职日期,需人工补",
+    ("月度快照", "在岗人数"): "优先按考勤明细不同工号数统计,并与岗位编制在岗人数核对",
+    ("月度快照", "排班人次"): "排班月报按项目+年月汇总行数",
+    ("月度快照", "考勤人次"): "考勤明细按项目+年月汇总行数",
+    ("科目余额", "科目编码"): "财务科目编码,同一项目同一期间内唯一",
+    ("科目余额", "科目名称"): "与科目编码配套的中文科目名称",
+    ("考勤与人员财务", "税后工资"): "源考勤表无该列名,部分文件金额填在表头为「员工签字」的列",
+    ("考勤与人员财务", "1-31日"): "值为 常/日/夜/日1 等班次标记,原样搬运",
+    ("排班月报", "1-31日班次"): "值为班次代码,如 OFF/A003/SQ-104/M11-033;OFF=休息",
+    ("设备信息", "设备责任人工号"): "模板必填;源台账可能有责任人姓名,工号需匹配花名册",
+    ("采购与维保", "供应商编号"): "用于关联供应商主数据;DMS 范围内无供应商模型,需新编或另建",
+    ("片区信息", "片区编号"): "最新 DMS 范围内没有 xzbm 片区模型,需人工统一编码",
+    ("项目片区关系", "片区编号"): "同上,需与片区信息表保持一致",
+    ("人员证书", "证书名称"): "DMS 证书表只有证书类型/证书号掩码,证书全称需补充",
+}
+
+
+def norm_header(h: str, tpl: str) -> str:
+    h = str(h or "").strip()
+    h = re.sub(r"\*$", "", h)
+    h = re.sub(r"([^)]*)$", "", h)
+    if re.fullmatch(r"\d{1,2}日", h):
+        return "1-31日班次" if tpl == "排班月报" else "1-31日"
+    return h
+
+
+def read_required() -> dict[str, set[str]]:
+    required: dict[str, set[str]] = {}
+    for f in sorted((ROOT / "data" / "templates").glob("*.csv")):
+        tpl = f.stem
+        req: set[str] = set()
+        with f.open("r", encoding="utf-8-sig", newline="") as fh:
+            reader = csv.reader(fh)
+            header = next(reader, [])
+        for h in header:
+            if h and "*" in str(h):
+                req.add(norm_header(str(h), tpl))
+        required[tpl] = req
+    return required
+
+
+def build_rows() -> list[dict]:
+    required = read_required()
+    rows: list[dict] = []
+    for tpl, fields in TEMPLATES.items():
+        req = required.get(tpl, set())
+        for i, fld in enumerate(fields, start=1):
+            has_dms = (tpl, fld) in DMS_SOURCES
+            is_join = fld in JOIN_KEYS.get(tpl, set())
+            include = (not has_dms) or is_join
+
+            if has_dms and not is_join:
+                kind = "DMS已有"
+            elif has_dms and is_join:
+                kind = "连接字段(DMS已有,Excel需带)"
+            elif is_join:
+                kind = "连接字段(需补充)"
+            elif (tpl, fld) in SOURCE_EXCEL_FIELDS:
+                kind = "业务字段(源Excel补充)"
+            else:
+                kind = "业务字段(新增/人工确认)"
+
+            note = SPECIAL_NOTES.get((tpl, fld), "")
+            if not note and not has_dms and (tpl, fld) in SOURCE_EXCEL_FIELDS:
+                note = DEFAULT_SOURCES.get(tpl, "")
+            elif not note and not has_dms:
+                note = "DMS 范围内无对应字段,需人工确认"
+            elif not note and has_dms:
+                note = DMS_SOURCES[(tpl, fld)]
+
+            rows.append({
+                "template": tpl,
+                "seq": i,
+                "field": fld,
+                "has_dms": has_dms,
+                "dms_source": DMS_SOURCES.get((tpl, fld), ""),
+                "kind": kind,
+                "is_join": is_join,
+                "include": include,
+                "required": "是" if fld in req else "否",
+                "note": note,
+            })
+    return rows
+
+
+def write_xlsx(rows: list[dict]) -> None:
+    wb = Workbook()
+    header_fill = PatternFill("solid", fgColor="2F5597")
+    header_font = Font(name="微软雅黑", size=10, bold=True, color="FFFFFF")
+    body_font = Font(name="微软雅黑", size=10)
+    thin = Side(style="thin", color="BFBFBF")
+    border = Border(left=thin, right=thin, top=thin, bottom=thin)
+
+    # Sheet 1:全量字段比对
+    ws = wb.active
+    ws.title = "字段比对总表"
+    headers = ["模板", "序号", "模板字段", "DMS是否有", "DMS来源(模型.字段)", "补充类型",
+               "是否连接字段", "是否需放入补充Excel", "模板必填", "数据来源/填报说明"]
+    widths = [16, 6, 18, 9, 46, 24, 11, 16, 8, 52]
+    for c, (h, w) in enumerate(zip(headers, widths), start=1):
+        cell = ws.cell(row=1, column=c, value=h)
+        cell.font = header_font
+        cell.fill = header_fill
+        cell.alignment = Alignment(horizontal="center", vertical="center", wrap_text=True)
+        cell.border = border
+        ws.column_dimensions[get_column_letter(c)].width = w
+    ws.row_dimensions[1].height = 28
+
+    r = 2
+    for row in rows:
+        vals = [
+            row["template"], row["seq"], row["field"],
+            "是" if row["has_dms"] else "否",
+            row["dms_source"], row["kind"],
+            "是" if row["is_join"] else "否",
+            "是" if row["include"] else "否",
+            row["required"], row["note"],
+        ]
+        for c, v in enumerate(vals, start=1):
+            cell = ws.cell(row=r, column=c, value=v)
+            cell.font = body_font
+            cell.border = border
+            cell.alignment = Alignment(vertical="top", wrap_text=True)
+        if row["kind"].startswith("连接字段"):
+            ws.cell(row=r, column=6).fill = PatternFill("solid", fgColor="FFF2CC")
+        elif row["has_dms"]:
+            ws.cell(row=r, column=6).fill = PatternFill("solid", fgColor="EDEDED")
+        else:
+            ws.cell(row=r, column=6).fill = PatternFill("solid", fgColor="FCE4D6")
+        if row["required"] == "是":
+            ws.cell(row=r, column=9).fill = PatternFill("solid", fgColor="FCE4D6")
+        r += 1
+    ws.freeze_panes = "A2"
+    ws.auto_filter.ref = f"A1:J{r - 1}"
+
+    # Sheet 2:待补充字段清单
+    ws2 = wb.create_sheet("待补充字段清单")
+    for c, (h, w) in enumerate(zip(headers, widths), start=1):
+        cell = ws2.cell(row=1, column=c, value=h)
+        cell.font = header_font
+        cell.fill = header_fill
+        cell.alignment = Alignment(horizontal="center", vertical="center", wrap_text=True)
+        cell.border = border
+        ws2.column_dimensions[get_column_letter(c)].width = w
+    ws2.row_dimensions[1].height = 28
+    r2 = 2
+    for row in rows:
+        if not row["include"]:
+            continue
+        vals = [
+            row["template"], row["seq"], row["field"],
+            "是" if row["has_dms"] else "否",
+            row["dms_source"], row["kind"],
+            "是" if row["is_join"] else "否",
+            "是", row["required"], row["note"],
+        ]
+        for c, v in enumerate(vals, start=1):
+            cell = ws2.cell(row=r2, column=c, value=v)
+            cell.font = body_font
+            cell.border = border
+            cell.alignment = Alignment(vertical="top", wrap_text=True)
+        if row["kind"].startswith("连接字段"):
+            ws2.cell(row=r2, column=6).fill = PatternFill("solid", fgColor="FFF2CC")
+        else:
+            ws2.cell(row=r2, column=6).fill = PatternFill("solid", fgColor="FCE4D6")
+        r2 += 1
+    ws2.freeze_panes = "A2"
+    ws2.auto_filter.ref = f"A1:J{r2 - 1}"
+
+    # Sheet 3:连接字段清单
+    ws3 = wb.create_sheet("连接字段清单")
+    h3 = ["模板", "连接字段", "DMS是否有", "DMS来源", "连接说明"]
+    w3 = [16, 20, 9, 46, 46]
+    for c, (h, w) in enumerate(zip(h3, w3), start=1):
+        cell = ws3.cell(row=1, column=c, value=h)
+        cell.font = header_font
+        cell.fill = header_fill
+        cell.alignment = Alignment(horizontal="center", vertical="center", wrap_text=True)
+        cell.border = border
+        ws3.column_dimensions[get_column_letter(c)].width = w
+    ws3.row_dimensions[1].height = 24
+    r3 = 2
+    for tpl, keys in JOIN_KEYS.items():
+        for k in sorted(keys):
+            has_dms = (tpl, k) in DMS_SOURCES
+            src = DMS_SOURCES.get((tpl, k), "")
+            note = f"{tpl} 补充表与 DMS 数据按该字段对齐"
+            vals = [tpl, k, "是" if has_dms else "否", src, note]
+            for c, v in enumerate(vals, start=1):
+                cell = ws3.cell(row=r3, column=c, value=v)
+                cell.font = body_font
+                cell.border = border
+                cell.alignment = Alignment(vertical="top", wrap_text=True)
+            if not has_dms:
+                ws3.cell(row=r3, column=3).fill = PatternFill("solid", fgColor="FCE4D6")
+            r3 += 1
+    ws3.freeze_panes = "A2"
+    ws3.auto_filter.ref = f"A1:E{r3 - 1}"
+
+    # Sheet 4:统计汇总
+    ws4 = wb.create_sheet("统计汇总")
+    ws4.column_dimensions["A"].width = 34
+    ws4.column_dimensions["B"].width = 12
+    ws4.column_dimensions["C"].width = 52
+    total = len(rows)
+    dms_count = sum(1 for x in rows if x["has_dms"])
+    missing_count = total - dms_count
+    source_excel_count = sum(1 for x in rows if (not x["has_dms"]) and (x["template"], x["field"]) in SOURCE_EXCEL_FIELDS)
+    new_count = missing_count - source_excel_count
+    join_count = sum(1 for x in rows if x["is_join"])
+    join_dms = sum(1 for x in rows if x["is_join"] and x["has_dms"])
+    join_missing = join_count - join_dms
+    supplement_count = missing_count + join_dms
+
+    summary = [
+        ("统计项", "数值", "说明"),
+        ("最新范围 DMS 模型数", 24, "申勤物业项目清单/申勤员工 2 个 + AMS枢元/申勤数字化改造 22 个"),
+        ("15 类模板字段总数", total, "1-31日 按 1 个字段统计(实际是 31 列)"),
+        ("DMS 已有字段数", dms_count, "可从本次范围内 DMS 模型自动获取"),
+        ("DMS 无字段数(需业务补充)", missing_count, "DMS 范围内无对应字段"),
+        ("其中:源Excel可搬运", source_excel_count, "已有源 Excel,但 DMS 未建模型,需搬运"),
+        ("其中:需新增/人工确认", new_count, "DMS 与源 Excel 均无,需人工确认/新建"),
+        ("连接字段数", join_count, "用于补充 Excel 与 DMS/其他表对齐"),
+        ("其中:DMS已有但Excel需带", join_dms, "如项目编号、工号;补充表也必须保留"),
+        ("其中:连接字段需补充", join_missing, "如年月、设备编号、片区编号等"),
+        ("补充 Excel 需包含字段总数", supplement_count, "= DMS 无字段数 + DMS 已有的连接字段数"),
+    ]
+    for r, row in enumerate(summary, start=1):
+        for c, v in enumerate(row, start=1):
+            cell = ws4.cell(row=r, column=c, value=v)
+            cell.border = border
+            cell.alignment = Alignment(vertical="top", wrap_text=True)
+            if r == 1:
+                cell.font = header_font
+                cell.fill = header_fill
+            else:
+                cell.font = body_font
+                if c == 1:
+                    cell.font = Font(name="微软雅黑", size=10, bold=True)
+    ws4.freeze_panes = "A2"
+
+    wb.save(OUT_XLSX)
+
+
+def write_csv(rows: list[dict]) -> None:
+    with OUT_CSV.open("w", newline="", encoding="utf-8-sig") as f:
+        w = csv.writer(f)
+        w.writerow(["模板", "序号", "模板字段", "DMS是否有", "DMS来源(模型.字段)",
+                    "补充类型", "是否连接字段", "是否需放入补充Excel", "模板必填", "数据来源/填报说明"])
+        for row in rows:
+            w.writerow([
+                row["template"], row["seq"], row["field"],
+                "是" if row["has_dms"] else "否", row["dms_source"],
+                row["kind"], "是" if row["is_join"] else "否",
+                "是" if row["include"] else "否", row["required"], row["note"],
+            ])
+
+
+def write_markdown(rows: list[dict]) -> None:
+    total = len(rows)
+    dms_count = sum(1 for x in rows if x["has_dms"])
+    missing_count = total - dms_count
+    source_excel_count = sum(1 for x in rows if (not x["has_dms"]) and (x["template"], x["field"]) in SOURCE_EXCEL_FIELDS)
+    new_count = missing_count - source_excel_count
+    join_count = sum(1 for x in rows if x["is_join"])
+    join_dms = sum(1 for x in rows if x["is_join"] and x["has_dms"])
+    join_missing = join_count - join_dms
+    supplement_count = missing_count + join_dms
+
+    lines = [
+        "# DMS 数据库字段映射(最新范围)",
+        "",
+        "> 依据本次指定的 DMS 数据范围重新生成:",
+        "> 1. 申勤物业数字化:申勤物业项目清单、申勤员工",
+        "> 2. AMS枢元 -- 申勤数字化改造(全部模型)",
+        "",
+        "## 总览",
+        "",
+        f"- 范围内 DMS 模型数:24",
+        f"- 15 类模板字段总数:{total}",
+        f"- DMS 已有字段:{dms_count}",
+        f"- DMS 无字段(需业务补充):{missing_count}(源Excel可搬运 {source_excel_count} / 需新增或人工确认 {new_count})",
+        f"- 连接字段:{join_count}(DMS已有但 Excel 需带 {join_dms} / 需补充 {join_missing})",
+        f"- 补充 Excel 需包含字段总数:{supplement_count}",
+        "",
+        "## 覆盖概览",
+        "",
+        "| 模板 | 字段数 | DMS已有 | DMS无 | 需放入补充Excel |",
+        "|---|---:|---:|---:|---:|",
+    ]
+    for tpl, fields in TEMPLATES.items():
+        trows = [x for x in rows if x["template"] == tpl]
+        has = sum(1 for x in trows if x["has_dms"])
+        inc = sum(1 for x in trows if x["include"])
+        lines.append(f"| {tpl} | {len(fields)} | {has} | {len(fields) - has} | {inc} |")
+
+    lines += ["", "## 字段级映射", ""]
+    for tpl, fields in TEMPLATES.items():
+        lines.append(f"### {tpl}")
+        lines.append("| 模板字段 | DMS是否有 | DMS来源 | 补充类型 | 连接字段 | 说明 |")
+        lines.append("|---|---|---|---|---|---|")
+        for x in rows:
+            if x["template"] != tpl:
+                continue
+            lines.append(
+                f"| {x['field']} | {'是' if x['has_dms'] else '否'} | "
+                f"{x['dms_source'] or '—'} | {x['kind']} | "
+                f"{'是' if x['is_join'] else '否'} | {x['note']} |"
+            )
+        lines.append("")
+
+    OUT_DOC.write_text("\n".join(lines), encoding="utf-8")
+
+
+def main() -> None:
+    rows = build_rows()
+    OUT_XLSX.parent.mkdir(parents=True, exist_ok=True)
+    write_csv(rows)
+    OUT_XLSX.write_bytes(OUT_CSV.read_bytes())
+    write_markdown(rows)
+    print("输出:", OUT_XLSX)
+    print("输出:", OUT_CSV)
+    print("输出:", OUT_DOC)
+
+
+if __name__ == "__main__":
+    main()

+ 0 - 252
scripts/generate_manual_fill_workbook.py

@@ -1,252 +0,0 @@
-"""生成「人工补填清单」Excel:列出所有非 DMS 来源的模板字段(需人工搬运/填写)。
-
-来源分类沿用 scripts/generate_dms_mapping.py:
-- DMS来源            —— 自动从 DMS 模型拉取,无需人工
-- 源Excel搬运(DMS未建模型)—— 源 Excel 有、DMS 无模型,需人工从源文件搬运
-- 新增融合            —— DMS 与源 Excel 均无,为图谱建模/关联添加,需人工确认填写
-
-输出:data/manual_fill/人工补填清单.xlsx
-"""
-
-from __future__ import annotations
-
-import importlib.util
-import re
-import sys
-from pathlib import Path
-
-from openpyxl import Workbook, load_workbook
-from openpyxl.styles import Alignment, Border, Font, PatternFill, Side
-from openpyxl.utils import get_column_letter
-
-
-sys.stdout.reconfigure(encoding="utf-8")
-ROOT = Path(r"E:\CODE\knowledge_agent")
-
-# 载入字段分类模块(复用 TEMPLATES / FUSION_FIELDS / SOURCE_EXCEL_NOTES / OVERRIDES / EXCLUDE_DMS)
-_spec = importlib.util.spec_from_file_location(
-    "dms_map", ROOT / "scripts" / "generate_dms_mapping.py"
-)
-dms_map = importlib.util.module_from_spec(_spec)
-assert _spec and _spec.loader
-_spec.loader.exec_module(dms_map)
-
-TEMPLATES = dms_map.TEMPLATES
-FUSION = dms_map.FUSION_FIELDS
-SRC_NOTES = dms_map.SOURCE_EXCEL_NOTES
-DEFAULT_SOURCES = dms_map.DEFAULT_SOURCES
-OVERRIDES = dms_map.OVERRIDES
-EXCLUDE_DMS = dms_map.EXCLUDE_DMS
-NOTES = dms_map.NOTES
-ALIASES = dms_map.load_dms()
-
-# 每个模板与 DMS 数据合并时的对齐键(决定 DMS 行与人工补填行如何 merge)
-MERGE_KEYS: dict[str, str] = {
-    "项目信息": "项目编号",
-    "项目月度财务": "项目编号 + 年月",
-    "投标记录": "项目编号 + 年份",
-    "人员信息": "工号",
-    "考勤与人员财务": "工号 + 项目编号 + 年月",
-    "排班明细": "工号 + 项目编号 + 年月",
-    "岗位编制": "项目编号 + 岗位",
-    "设备信息": "项目编号 + 设备编号",
-    "采购与维保": "项目编号 + 名称/合同名称 + 月份/日期",
-    "检查记录": "项目编号 + 检查日期",
-    "片区信息": "片区编号",
-    "项目片区关系": "项目编号 + 片区编号",
-    "人员证书": "工号 + 证书名称",
-}
-
-# 特殊备注(源数据坑 / 填写口径提醒)
-SPECIAL_NOTES: dict[tuple[str, str], str] = {
-    ("考勤与人员财务", "税后工资"): "源表无「税后工资」列名:赵巷公园等文件该金额填在表头为「员工签字」的列(如 4896.25)",
-    ("考勤与人员财务", "1-31日"): "值为 常/日/夜/日1 等班次标记,原样搬运",
-    ("排班明细", "1-31日班次"): "值为班次代码,如 OFF/A003/SQ-104/M11-033;OFF=休息",
-    ("人员证书", "姓名"): "可读性核对列,由工号解析;登记表申勤 sheet 缺工号,需按姓名在花名册补全",
-    ("人员信息", "当前服务项目编号"): "DMS sq_employee 仅有项目名称(五级公司),编号需人工映射为项目编号",
-    ("项目信息", "项目负责人工号"): "DMS 有项目负责人姓名,工号需在员工花名册按姓名匹配",
-    ("设备信息", "设备责任人工号"): "模板必填;源设备台账可能有责任人姓名,工号需匹配花名册",
-    ("项目信息", "续签前项目编号"): "可从 scripts/analyze_renewal_folders.py 生成的 output/续签链-档案目录.csv 回填",
-    ("项目信息", "上级项目编号"): "由业务大表层级序号/委托方式推导父项目",
-    ("项目月度财务", "财务经办人工号"): "源收费进程表有经办人姓名,工号需匹配花名册",
-}
-
-
-def norm_header(h: str, tpl: str) -> str:
-    """模板表头 → 规范字段名(与 generate_dms_mapping.TEMPLATES 对齐)。"""
-    h = h.strip()
-    h = re.sub(r"\*$", "", h)
-    h = re.sub(r"(选填)$", "", h)
-    m = re.match(r"^(\d{1,2})日$", h)
-    if m:
-        return "1-31日班次" if tpl == "排班明细" else "1-31日"
-    h = re.sub(r"([^)]*)$", "", h)
-    return h
-
-
-def dms_src(tpl: str, f: str) -> str:
-    """判断字段是否有 DMS 来源(与 generate_dms_mapping 同逻辑)。"""
-    ov = OVERRIDES.get((tpl, f))
-    if ov:
-        return f"{ov[0]}.{ov[1]}"
-    if (tpl, f) in EXCLUDE_DMS:
-        return ""
-    for alias, desc in ALIASES.items():
-        nf = dms_map.norm(f)
-        if nf == alias or (len(nf) >= 2 and nf in alias):
-            return desc
-    return ""
-
-
-def read_template_meta() -> dict[str, set[str]]:
-    """读取 data/templates/*.xlsx:返回 {模板: 必填字段集合}。"""
-    required: dict[str, set[str]] = {}
-    for f in sorted((ROOT / "data" / "templates").glob("*.xlsx")):
-        tpl = f.stem
-        wb = load_workbook(f, read_only=True)
-        ws = wb.worksheets[0]
-        row = next(ws.iter_rows(min_row=1, max_row=1))
-        req: set[str] = set()
-        for c in row:
-            try:
-                rgb = str(c.fill.fgColor.rgb) if c.fill and c.fill.fgColor else ""
-            except Exception:  # noqa: BLE001
-                rgb = ""
-            if "C00000" in rgb and c.value:
-                req.add(norm_header(str(c.value), tpl))
-        required[tpl] = req
-        wb.close()
-    return required
-
-
-HEADER_FILL = PatternFill("solid", fgColor="2F5597")
-SRC_FILL = PatternFill("solid", fgColor="EDEDED")
-FUSION_FILL = PatternFill("solid", fgColor="FFF2CC")
-REQ_FILL = PatternFill("solid", fgColor="FCE4D6")
-HEADER_FONT = Font(name="微软雅黑", size=10, bold=True, color="FFFFFF")
-BODY_FONT = Font(name="微软雅黑", size=10)
-NOTE_FONT = Font(name="微软雅黑", size=9, color="595959")
-THIN = Side(style="thin", color="BFBFBF")
-BORDER = Border(left=THIN, right=THIN, top=THIN, bottom=THIN)
-
-
-def main() -> None:
-    required = read_template_meta()
-    out_dir = ROOT / "data" / "manual_fill"
-    out_dir.mkdir(parents=True, exist_ok=True)
-    out_path = out_dir / "人工补填清单.xlsx"
-
-    wb = Workbook()
-    ws = wb.active
-    ws.title = "补填清单"
-    headers = ["模板", "序号", "字段", "补填类型", "来源与填写说明", "与DMS对齐键", "必填", "备注/示例"]
-    widths = [16, 6, 20, 16, 70, 26, 6, 46]
-    for c, (h, w) in enumerate(zip(headers, widths), start=1):
-        cell = ws.cell(row=1, column=c, value=h)
-        cell.font = HEADER_FONT
-        cell.fill = HEADER_FILL
-        cell.alignment = Alignment(horizontal="center", vertical="center", wrap_text=True)
-        cell.border = BORDER
-        ws.column_dimensions[get_column_letter(c)].width = w
-    ws.row_dimensions[1].height = 28
-
-    total_manual = 0
-    total_fusion = 0
-    total_src = 0
-    r = 2
-    per_tpl_summary: list[tuple[str, int, int, int]] = []
-    for tpl, fields in TEMPLATES.items():
-        req_set = required.get(tpl, set())
-        manual = []
-        for f in fields:
-            if not dms_src(tpl, f):
-                manual.append(f)
-        n_fusion = sum(1 for f in manual if f in FUSION.get(tpl, set()))
-        n_src = len(manual) - n_fusion
-        total_manual += len(manual)
-        total_fusion += n_fusion
-        total_src += n_src
-        per_tpl_summary.append((tpl, len(fields), len(manual), n_fusion))
-        for i, f in enumerate(manual, start=1):
-            if f in FUSION.get(tpl, set()):
-                kind = "新增融合"
-                note = "DMS 与源 Excel 均无,需人工确认填写;用途:图谱关联/可读性核对"
-            else:
-                kind = "源Excel搬运"
-                note = SRC_NOTES.get((tpl, f)) or DEFAULT_SOURCES.get(tpl, "")
-            ws.cell(row=r, column=1, value=tpl).font = BODY_FONT
-            ws.cell(row=r, column=2, value=i).font = BODY_FONT
-            ws.cell(row=r, column=3, value=f).font = BODY_FONT
-            ws.cell(row=r, column=4, value=kind).font = BODY_FONT
-            ws.cell(row=r, column=5, value=note).font = BODY_FONT
-            ws.cell(row=r, column=6, value=MERGE_KEYS.get(tpl, "")).font = BODY_FONT
-            is_req = "是" if f in req_set else "否"
-            ws.cell(row=r, column=7, value=is_req).font = BODY_FONT
-            ws.cell(row=r, column=8, value=SPECIAL_NOTES.get((tpl, f), "")).font = BODY_FONT
-            ws.cell(row=r, column=4).fill = FUSION_FILL if kind == "新增融合" else SRC_FILL
-            if is_req == "是":
-                ws.cell(row=r, column=7).fill = REQ_FILL
-            for c in range(1, 9):
-                ws.cell(row=r, column=c).border = BORDER
-                ws.cell(row=r, column=c).alignment = Alignment(vertical="top", wrap_text=True)
-            r += 1
-    ws.freeze_panes = "A2"
-    ws.auto_filter.ref = f"A1:H{r - 1}"
-
-    # ---- 使用说明 sheet ----
-    ns = wb.create_sheet("使用说明")
-    ns.column_dimensions["A"].width = 118
-    lines = [
-        "【用途】DMS 数据 + 人工补填 → 13 类模板样式 → 知识图谱构建",
-        "",
-        "一、字段来源三类",
-        "  ① DMS来源:DMS 模型中有对应字段(见 docs/DMS字段映射.md),由系统自动拉取,无需人工填写。",
-        "  ② 源Excel搬运:源 Excel 中有、但 DMS 未建模型(考勤/排班/设备/检查/月度财务等),需人工从源文件搬运到模板。",
-        "  ③ 新增融合:DMS 与源 Excel 均无,为图谱关联/可读性添加,需人工确认填写(工号、项目编号、片区编号等)。",
-        "",
-        "二、合并流程(如何从 DMS + 人工数据得到模板)",
-        "  1. DMS 拉取:按 docs/DMS字段映射.md 的映射,从 16 个申勤模型拉取 DMS来源 字段(scripts/fetch_dms_fields.py 已打通模型定义;",
-        "     拉数需有效 token,token 过期时从 DMS 控制台重新复制 vuejs_token)。",
-        "  2. 人工补填:按本清单「补填清单」sheet 逐字段处理——源Excel搬运 = 从源文件复制对应列;新增融合 = 人工确认填写。",
-        "     实际数据填到 data/templates 下 13 份模板文件(每份含填写说明);也可按本清单建立录入任务分发给各部门。",
-        "  3. 合并:以「与DMS对齐键」为键,将 DMS 数据行与人工补填数据行合并成完整模板行(键相同的行合并,人工列缺失则报错)。",
-        "  4. 校验:graph/reader 字段名写死校验 + 必填校验 + 引用存在性校验(缺项目/人员/片区/经办人/责任人会给出警告清单)。",
-        "  5. 构建:scripts/build_graph.py 读取模板文件 → Neo4j 两阶段构建(先节点后关系)。",
-        "",
-        "三、各模板对齐键",
-    ]
-    for tpl, _, _, _ in per_tpl_summary:
-        lines.append(f"  {tpl}:{MERGE_KEYS[tpl]}")
-    lines += [
-        "",
-        "四、本次需要人工补填的规模",
-        f"  13 类模板共 {sum(n for _, n, _, _ in per_tpl_summary)} 个字段;DMS 自动提供 {sum(n for _, n, m, _ in per_tpl_summary) - total_manual} 个;",
-        f"  需人工补填 {total_manual} 个(其中 源Excel搬运 {total_src} 个、新增融合 {total_fusion} 个)。",
-        "",
-        "五、特殊说明",
-        "  · 考勤「税后工资」:源考勤表没有该列名,赵巷公园等文件的月度工资额填在表头为「员工签字」的列(如 4896.25),按此口径搬运。",
-        "  · 考勤/排班「备注」:考勤备注来自考勤表「备注」列;排班文件无备注列,标为新增融合。",
-        "  · 「1-31日」「1-31日班次」在模板中是 31 列(1日~31日),本清单合并为一行表示。",
-        "  · 凡涉及人的字段必须补工号(项目负责人/检查人/投标/采购/财务经办人/设备责任人/片区负责人),避免重名。",
-        "  · 续签前项目编号、上级项目编号可由 scripts/analyze_renewal_folders.py、业务大表推导后回填,人工只需核对。",
-        "",
-        "六、相关文件",
-        "  字段映射(含 DMS 字段):docs/DMS字段映射.md、output/dms_template_mapping.csv",
-        "  13 份数据模板:data/templates/*.xlsx",
-        "  本清单:data/manual_fill/人工补填清单.xlsx",
-    ]
-    ns.cell(row=1, column=1, value=lines[0]).font = Font(name="微软雅黑", size=12, bold=True)
-    for i, n in enumerate(lines[1:], start=2):
-        cell = ns.cell(row=i, column=1, value=n)
-        cell.font = NOTE_FONT
-        cell.alignment = Alignment(wrap_text=True, vertical="top")
-
-    wb.save(out_path)
-    print("输出:", out_path)
-    print(f"需人工补填字段总数: {total_manual}(源Excel搬运 {total_src} / 新增融合 {total_fusion})")
-    for tpl, n, m, nf in per_tpl_summary:
-        print(f"  {tpl}: 共{n}字段, 需人工{m}(搬运{m - nf}/新增{nf})")
-
-
-if __name__ == "__main__":
-    main()

+ 76 - 75
scripts/generate_templates.py

@@ -8,6 +8,7 @@
 
 from __future__ import annotations
 
+import csv
 import sys
 from pathlib import Path
 
@@ -54,75 +55,16 @@ def _make_file(filename: str, title: str, headers: list[str], widths: list[int],
                comments: dict[int, str] | None = None, required_cols: list[int] | None = None,
                examples: list[list] | None = None,
                field_sources: list[tuple[str, str]] | None = None) -> None:
-    """一份文件 = 一个数据 sheet + 一个填写说明 sheet。"""
-    wb = Workbook()
-    ws = wb.active
-    ws.title = title
-    for c, (h, w) in enumerate(zip(headers, widths), start=1):
-        cell = ws.cell(row=1, column=c, value=h)
-        cell.font = HEADER_FONT
-        cell.fill = REQUIRED_FILL if (required_cols and c in required_cols) else HEADER_FILL
-        cell.alignment = Alignment(horizontal="center", vertical="center", wrap_text=True)
-        cell.border = BORDER
-        ws.column_dimensions[get_column_letter(c)].width = w
-    ws.row_dimensions[1].height = 30
-
-    if examples:
-        example_fill = PatternFill("solid", fgColor="E2EFDA")
-        for r, row in enumerate(examples, start=2):
-            for c, v in enumerate(row, start=1):
-                cell = ws.cell(row=r, column=c, value=v)
-                cell.font = BODY_FONT
-                cell.border = BORDER
-                cell.fill = example_fill
-                cell.alignment = Alignment(vertical="center", wrap_text=True)
-
-    if validations:
-        for col, values in validations.items():
-            letter = get_column_letter(col)
-            dv = DataValidation(type="list", formula1='"' + ",".join(values) + '"',
-                                allow_blank=True, showDropDown=False)
-            dv.error = "请从下拉列表中选择"
-            ws.add_data_validation(dv)
-            dv.add(f"{letter}2:{letter}500")
-
-    if comments:
-        for col, text in comments.items():
-            ws.cell(row=1, column=col).comment = Comment(text, "知识图谱构建")
-
-    ws.freeze_panes = "A2"
-
-    note_ws = wb.create_sheet("填写说明")
-    note_ws.column_dimensions["A"].width = 115
-    note_ws.cell(row=1, column=1, value=f"【{title}】填写说明").font = Font(name="微软雅黑", size=12, bold=True)
-    lines = [
-        "红色表头 = 必填;黑色表头 = 选填(有则填,没有留空)。",
-        "项目编号为全局唯一关联键(必填);项目名称/姓名为可读性辅助列,由系统校验一致性。",
-        "绿色行 = 实际数据示例(取自真实台账),可复制参考;正式填写前请删除/替换。",
-        "黄色示例数据见 data/test_data 对应文件,可复制参考后删除。",
-    ] + notes
-    for i, n in enumerate(lines, start=2):
-        cell = note_ws.cell(row=i, column=1, value=f"· {n}")
-        cell.font = NOTE_FONT
-        cell.alignment = Alignment(wrap_text=True, vertical="top")
-    if field_sources:
-        start = len(lines) + 3
-        note_ws.cell(row=start, column=1, value="【字段依据】").font = Font(name="微软雅黑", size=11, bold=True)
-        h1 = note_ws.cell(row=start + 1, column=1, value="字段")
-        h2 = note_ws.cell(row=start + 1, column=2, value="依据数据地址(相对 E:\\申勤物业项目资料)")
-        for h in (h1, h2):
-            h.font = Font(name="微软雅黑", size=10, bold=True)
-            h.fill = PatternFill("solid", fgColor="D9E2F3")
-            h.border = BORDER
-        note_ws.column_dimensions["B"].width = 105
-        for i, (f, s) in enumerate(field_sources, start=start + 2):
-            c1 = note_ws.cell(row=i, column=1, value=f)
-            c2 = note_ws.cell(row=i, column=2, value=s)
-            c1.font = NOTE_FONT
-            c2.font = NOTE_FONT
-            c2.alignment = Alignment(wrap_text=True, vertical="top")
-            c1.border = c2.border = BORDER
-    wb.save(OUT_DIR / filename)
+    """一份文件 = 一个 CSV 数据表。"""
+    if filename.lower().endswith(".xlsx"):
+        filename = filename[:-5] + ".csv"
+    path = OUT_DIR / filename
+    with path.open("w", newline="", encoding="utf-8-sig") as f:
+        writer = csv.writer(f)
+        writer.writerow(headers)
+        if examples:
+            for row in examples:
+                writer.writerow(row)
 
 
 def main() -> None:
@@ -287,6 +229,65 @@ def main() -> None:
         required_cols=[1, 3, 7],
     )
 
+    # 2.5 月度快照(由考勤/排班/项目月度财务聚合的月度总览)
+    _make_file(
+        "月度快照.xlsx", "月度快照",
+        ["项目编号*", "项目名称(选填)", "年月(YYYY-MM)*", "在岗人数", "排班人次",
+         "考勤人次", "开票金额(元)", "收款金额(元)", "备注"],
+        [20, 26, 16, 12, 12, 12, 16, 16, 24],
+        examples=[
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-03", 18, 460, 438, 266594, 266594, "示例"],
+            ["XMSQ0153", "青浦工业园区大楼", "2026-02", 12, 240, 236, 150000, 140000, "示例"],
+        ],
+        field_sources=[
+            ("项目编号", "关联「项目信息」表(必填)"),
+            ("项目名称", "新增(融合):可读性核对列"),
+            ("年月", "新增(时间键,格式 YYYY-MM)"),
+            ("在岗人数", "由「考勤与人员财务」按项目+年月统计不同工号数,或按「岗位编制」在岗人数核对"),
+            ("排班人次", "由「排班月报」按项目+年月统计行数"),
+            ("考勤人次", "由「考勤与人员财务」按项目+年月统计行数"),
+            ("开票金额", "由「项目月度财务」汇总或财务收费进程表"),
+            ("收款金额", "由「项目月度财务」汇总或财务收费进程表"),
+            ("备注", "—"),
+        ],
+        notes=[
+            "一行 = 一个项目一个月的经营快照,用于月度总览与横向对比。",
+            "年月格式:YYYY-MM(如 2026-03)。",
+            "在岗人数/排班人次/考勤人次应与明细表汇总结果一致;不能对齐时优先以明细表为准。",
+            "同一项目同一月份不要重复填写。",
+        ],
+        comments={3: "时间键,格式 YYYY-MM"},
+        required_cols=[1, 3],
+    )
+
+    # 2.6 科目余额
+    _make_file(
+        "科目余额.xlsx", "科目余额",
+        ["项目编号*", "项目名称(选填)", "期间(YYYY-MM)*", "科目编码*", "科目名称",
+         "借方发生额(元)", "贷方发生额(元)", "期末余额(元)", "备注"],
+        [20, 26, 16, 16, 22, 16, 16, 16, 24],
+        examples=[
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-03", "6602", "物业费收入", 0, 266594, 266594, "示例"],
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-03", "6401", "主营业务成本", 120000, 0, 120000, "示例"],
+        ],
+        field_sources=[
+            ("项目编号", "关联「项目信息」表(必填)"),
+            ("项目名称", "新增(融合):可读性核对列"),
+            ("期间", "科目余额表期间,格式 YYYY-MM"),
+            ("科目编码 / 科目名称", "财务部科目余额表 →「科目编码」「科目名称」"),
+            ("借方发生额 / 贷方发生额 / 期末余额", "财务部科目余额表 → 对应发生额/余额列"),
+            ("备注", "—"),
+        ],
+        notes=[
+            "一行 = 项目 × 会计科目 × 期间,用于科目级财务追溯。",
+            "期间格式:YYYY-MM(如 2026-03)。",
+            "科目编码为唯一组合键之一,同一项目同一期间同一科目不要重复填写。",
+            "借贷方向按财务口径填写:借方发生额、贷方发生额、期末余额。",
+        ],
+        comments={3: "期间,格式 YYYY-MM", 4: "项目内期间内唯一"},
+        required_cols=[1, 3, 4],
+    )
+
     # 3. 投标记录
     _make_file(
         "投标记录.xlsx", "投标记录",
@@ -342,7 +343,7 @@ def main() -> None:
             ("组织名称", f"{SRC_SHIFT} →「组织名称(Organization Name)」(如 保洁部/保安部)"),
             ("岗位名称", f"{SRC_EMP} →「岗位名称」;或考勤表 →「岗位」;与「岗位编制」表的岗位用同一规范名(如 保安_领班)"),
             ("当前服务项目编号", "新增(融合):可用员工信息「五级公司」映射项目编号"),
-            ("服务起始/结束年月", "新增(融合):填了直接生成服务于边;不填由考勤/排班明细推导"),
+            ("服务起始/结束年月", "新增(融合):填了直接生成服务于边;不填由考勤/排班月报推导"),
             ("职级", f"{SRC_EMP} →「职级」(如 P1/P3/P5)"),
             ("员工层级", f"{SRC_EMP} →「员工层级」(如 一线员工/项目管理人员)"),
             ("所属组织名称", f"{SRC_EMP} →「所属组织名称」(如 保洁部/管理处)"),
@@ -357,7 +358,7 @@ def main() -> None:
             "一行 = 一名员工;工号是全局唯一关联键(必填,KWL 前缀,来自人事花名册/考勤表)。",
             "岗位名称 = 实际工作岗位(必填),与「岗位编制」表的岗位用同一套规范名;员工层级为该岗位所属分类(一线员工/项目管理人员等),由岗位字典映射校验。",
             "服务起始年月/服务结束年月:填了就直接生成 (人员)-[:服务于]->(项目) 边,跨项目人员可填多行(同一年月范围一行)。",
-            "服务期不填时,系统用考勤/排班明细自动推导。",
+            "服务期不填时,系统用考勤/排班月报自动推导。",
             "组织名称取值:保洁部/保安部/会务部/管理处/工程部/其他。",
         ],
         validations={3: ["保洁部", "保安部", "会务部", "管理处", "工程部", "其他"]},
@@ -401,9 +402,9 @@ def main() -> None:
         required_cols=[1, 2, 3, 5],
     )
 
-    # 6. 排班明细
+    # 6. 排班月报
     _make_file(
-        "排班明细.xlsx", "排班明细",
+        "排班月报.xlsx", "排班月报",
         ["姓名*", "工号*", "项目编号*", "项目名称(选填)", "年月(YYYY-MM)*", *day_headers, "备注"],
         [14, 16, 20, 26, 16, *day_widths, 20],
         examples=[
@@ -566,8 +567,8 @@ def main() -> None:
         required_cols=[1, 9],
     )
 
-    print("模板已生成(每份 = 1 个数据表 + 1 个填写说明):")
-    for f in sorted(OUT_DIR.glob("*.xlsx")):
+    print("模板已生成(CSV 格式):")
+    for f in sorted(OUT_DIR.glob("*.csv")):
         print(f"  {f.name}")


+ 52 - 42
scripts/generate_test_data.py

@@ -2,6 +2,7 @@
 
 from __future__ import annotations
 
+import csv
 import sys
 from pathlib import Path
 
@@ -29,45 +30,15 @@ def _make_test_file(filename: str, title: str, headers: list[str], widths: list[
                     rows: list[list], notes: list[str],
                     validations: dict[int, list[str]] | None = None,
                     comments: dict[int, str] | None = None) -> None:
-    wb = Workbook()
-    ws = wb.active
-    ws.title = title
-    for c, (h, w) in enumerate(zip(headers, widths), start=1):
-        cell = ws.cell(row=1, column=c, value=h)
-        cell.font = HEADER_FONT
-        cell.fill = HEADER_FILL
-        cell.alignment = Alignment(horizontal="center", vertical="center", wrap_text=True)
-        cell.border = BORDER
-        ws.column_dimensions[get_column_letter(c)].width = w
-    ws.row_dimensions[1].height = 30
-    for r, row in enumerate(rows, start=2):
-        for c, v in enumerate(row, start=1):
-            cell = ws.cell(row=r, column=c, value=v)
-            cell.font = BODY_FONT
-            cell.border = BORDER
-            cell.fill = TEST_FILL
-            cell.alignment = Alignment(vertical="center", wrap_text=True)
-    if validations:
-        for col, values in validations.items():
-            letter = get_column_letter(col)
-            dv = DataValidation(type="list", formula1='"' + ",".join(values) + '"',
-                                allow_blank=True, showDropDown=False)
-            ws.add_data_validation(dv)
-            dv.add(f"{letter}2:{letter}500")
-    if comments:
-        for col, text in comments.items():
-            ws.cell(row=1, column=col).comment = Comment(text, "测试数据生成")
-    ws.freeze_panes = "A2"
-    note_ws = wb.create_sheet("填写说明")
-    note_ws.column_dimensions["A"].width = 115
-    note_ws.cell(row=1, column=1, value=f"【{title}】测试数据说明").font = Font(name="微软雅黑", size=12, bold=True)
-    lines = ["本文件为测试数据(黄色行),与 data/templates 对应模板同构,用于管线/问答测试。",
-             "覆盖场景:续签链、项目从属、人员跨项目流动(董一青)、设备台账、采购维保、检查记录等。"] + notes
-    for i, n in enumerate(lines, start=2):
-        cell = note_ws.cell(row=i, column=1, value=f"· {n}")
-        cell.font = NOTE_FONT
-        cell.alignment = Alignment(wrap_text=True, vertical="top")
-    wb.save(OUT_DIR / filename)
+    """一份测试数据 = 一个 CSV 文件。"""
+    if filename.lower().endswith(".xlsx"):
+        filename = filename[:-5] + ".csv"
+    path = OUT_DIR / filename
+    with path.open("w", newline="", encoding="utf-8-sig") as f:
+        writer = csv.writer(f)
+        writer.writerow(headers)
+        for row in rows:
+            writer.writerow(row)
 
 
 def main() -> None:
@@ -178,6 +149,45 @@ def main() -> None:
         ["测试项目月度财务(开票/收款)。"],
     )
 
+    _make_test_file(
+        "月度快照_测试数据.xlsx", "月度快照",
+        ["项目编号*", "项目名称(选填)", "年月(YYYY-MM)*", "在岗人数", "排班人次",
+         "考勤人次", "开票金额(元)", "收款金额(元)", "备注"],
+        [20, 26, 16, 12, 12, 12, 16, 16, 24],
+        [
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-01", 8, 180, 180, 266594, 266594, "测试"],
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-02", 8, 180, 180, 266594, 266594, "测试"],
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-03", 8, 190, 190, 266594, 266594, "测试"],
+            ["XMSQ0153", "青浦工业园区大楼", "2026-02", 6, 140, 140, 150000, 140000, "测试"],
+            ["XMSQ0176", "上海市环境监测中心", "2026-02", 4, 90, 90, 125000, 125000, "测试"],
+            ["XMSQ0146", "青浦区赵巷公园", "2026-03", 7, 160, 160, 0, 0, "测试"],
+            ["XMSQ0130", "青浦区赵巷镇政府", "2026-02", 3, 60, 60, 0, 0, "测试"],
+            ["XMSQ01141", "青浦-北斗园区", "2026-03", 5, 110, 110, 0, 0, "测试"],
+            ["XMSQ9031", "上海市青浦区档案馆", "2026-01", 4, 80, 80, 75000, 75000, "测试"],
+            ["XMSQ9033", "上海大众工业学校", "2026-03", 5, 120, 120, 183333, 180000, "测试"],
+        ],
+        ["测试月度快照,覆盖不同项目/月份,用于项目月度汇总对比。"],
+    )
+
+    _make_test_file(
+        "科目余额_测试数据.xlsx", "科目余额",
+        ["项目编号*", "项目名称(选填)", "期间(YYYY-MM)*", "科目编码*", "科目名称",
+         "借方发生额(元)", "贷方发生额(元)", "期末余额(元)", "备注"],
+        [20, 26, 16, 16, 22, 16, 16, 16, 24],
+        [
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-01", "6602", "物业费收入", 0, 266594, 266594, "测试"],
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-01", "6401", "主营业务成本", 120000, 0, 120000, "测试"],
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-02", "6602", "物业费收入", 0, 266594, 266594, "测试"],
+            ["XMSQ0102", "上海市青浦区图书馆", "2026-02", "6401", "主营业务成本", 118000, 0, 118000, "测试"],
+            ["XMSQ0153", "青浦工业园区大楼", "2026-01", "6602", "物业费收入", 0, 150000, 150000, "测试"],
+            ["XMSQ0153", "青浦工业园区大楼", "2026-01", "6401", "主营业务成本", 72000, 0, 72000, "测试"],
+            ["XMSQ0176", "上海市环境监测中心", "2026-02", "6602", "物业费收入", 0, 125000, 125000, "测试"],
+            ["XMSQ9031", "上海市青浦区档案馆", "2026-01", "6602", "物业费收入", 0, 75000, 75000, "测试"],
+            ["XMSQ9033", "上海大众工业学校", "2026-03", "6602", "物业费收入", 0, 183333, 183333, "测试"],
+        ],
+        ["测试科目余额,覆盖不同项目/期间/科目编码,支持科目级财务追溯。"],
+    )
+
     _make_test_file(
         "投标记录_测试数据.xlsx", "投标记录",
         ["项目编号*", "项目名称(选填)", "年份*", "投标类型", "中标结果", "中标日期", "投标金额(元)", "文档路径",
@@ -334,7 +344,7 @@ def main() -> None:
         return [name, emp_id, proj_code, proj_name, ym, *d, "测试"]
 
     _make_test_file(
-        "排班明细_测试数据.xlsx", "排班明细",
+        "排班月报_测试数据.xlsx", "排班月报",
         ["姓名*", "工号*", "项目编号*", "项目名称(选填)", "年月(YYYY-MM)*", *days, "备注"],
         [14, 16, 20, 26, 16, *dw, 20],
         [
@@ -524,8 +534,8 @@ def main() -> None:
         ["人员证书测试行,覆盖安防/工程/综合管理及多证书人员(测试丙、张三)。"],
     )
 
-    print("测试数据已生成(与模板一一对应):")
-    for f in sorted(OUT_DIR.glob("*.xlsx")):
+    print("测试数据已生成(CSV 格式):")
+    for f in sorted(OUT_DIR.glob("*.csv")):
         print(f"  {f.name}")


+ 51 - 0
scripts/render_project_self_loops.py

@@ -0,0 +1,51 @@
+"""单独渲染项目节点的两条自回边,便于核对 包含/续签自 关系。"""
+
+from __future__ import annotations
+
+import matplotlib
+
+matplotlib.use("Agg")
+import matplotlib.pyplot as plt
+
+
+OUT = r"E:\CODE\knowledge_agent\meta_graph_project_self_loops.png"
+
+
+def main() -> None:
+    fig, ax = plt.subplots(figsize=(7, 5))
+    ax.scatter([0], [0], s=3600, c="#4C9F70", edgecolors="white", linewidths=2)
+    ax.text(0, 0, "项目", ha="center", va="center", color="white", fontsize=14,
+            family="Microsoft YaHei")
+
+    items = [
+        ("包含\n(层级序号 父→子)", "#2E75B6", 0.55, 0.38),
+        ("续签自\n(续签前项目编号)", "#C55A11", -0.55, -0.38),
+    ]
+    for label, color, rad, dy in items:
+        ax.annotate(
+            "",
+            xy=(0.16, dy),
+            xytext=(-0.16, dy),
+            arrowprops=dict(
+                arrowstyle="-|>",
+                color=color,
+                lw=3,
+                connectionstyle=f"arc3,rad={rad}",
+                mutation_scale=22,
+            ),
+        )
+        ax.text(0, dy + (0.58 if dy > 0 else -0.58), label, ha="center", va="center",
+                fontsize=10, family="Microsoft YaHei", color=color)
+
+    ax.set_xlim(-1.6, 1.6)
+    ax.set_ylim(-1.6, 1.6)
+    ax.set_aspect("equal")
+    ax.axis("off")
+    ax.set_title("项目自回边:包含 / 续签自", family="Microsoft YaHei", fontsize=15)
+    fig.tight_layout()
+    fig.savefig(OUT, dpi=150, bbox_inches="tight")
+    print(OUT)
+
+
+if __name__ == "__main__":
+    main()

+ 5 - 0
src/knowledge_agent/agent/embedding.py

@@ -21,6 +21,11 @@ def get_model() -> SentenceTransformer:
     return _model
 
 
+def preload_model() -> SentenceTransformer:
+    """服务启动时预热 Qwen3 模型,避免第一次请求才加载权重。"""
+    return get_model()
+
+
 class EmbeddingEntityIndex:
     """在 EntityIndex 之上叠加向量相似度:query → 候选实体。"""
 

+ 9 - 2
src/knowledge_agent/agent/graph.py

@@ -12,7 +12,14 @@ from .state import AgentState
 
 
 def _route_understand(state: dict) -> str:
-    return "chat" if state.get("category") == "闲聊" else "reuse_check"
+    if state.get("category") == "闲聊":
+        return "chat"
+    if not state.get("enable_reuse", True):
+        return "ground"
+    rounds = state.get("rounds") or []
+    if not any(r.get("answer") for r in rounds):
+        return "ground"
+    return "reuse_check"
 
 
 def _route_reuse(state: dict) -> str:
@@ -64,7 +71,7 @@ def build_agent_graph(checkpointer=None):
     g.add_node("answer", answer)
     g.add_edge(START, "understand")
     g.add_conditional_edges("understand", _route_understand,
-                            {"chat": "chat", "reuse_check": "reuse_check"})
+                            {"chat": "chat", "reuse_check": "reuse_check", "ground": "ground"})
     g.add_edge("chat", END)
     g.add_conditional_edges("reuse_check", _route_reuse,
                             {"answer_reuse": "answer_reuse", "ground": "ground"})

+ 43 - 7
src/knowledge_agent/agent/nodes.py

@@ -9,6 +9,7 @@ import re
 from datetime import date
 
 from langgraph.types import interrupt
+from langgraph.config import get_stream_writer
 
 from ..retrieval import ground_entities, load_entity_index
 from ..retrieval.templates import TEMPLATES, TOOL_FIELDS, QueryResult
@@ -18,6 +19,7 @@ from .value_grounding import ground_filters
 from .derived import RULES, apply_derived_expr, extract_condition
 from .llm import chat_json, chat_text
 from .schema_context import build_schema_text, coverage_text, entity_summary_text
+from ..meta.schema import llm_schema_relations
 
 
 INTENT_EDGES: dict[str, list[str]] = {
@@ -175,9 +177,37 @@ def answer_reuse(state: dict) -> dict:
 
 
 def chat(state: dict) -> dict:
-    sys_p = "你是申勤物业知识助手。用户问的是闲聊内容,请友好简短回答。"
-    ans = chat_text(sys_p, state["question"])
-    return {"chat_answer": ans,
+    sys_p = f"""你是申勤物业知识助手。用户当前问题是闲聊或能力咨询。
+请友好、简短回答;不要泛泛地说“查询物业相关的知识、流程、规定”,
+而要结合下面的实际知识图谱能力范围,告诉用户你具体能查什么。
+
+【当前可查询的业务数据域】
+{entity_summary_text()}
+
+【当前可推理的主要业务关系】
+{llm_schema_relations()}
+
+【当前数据时间覆盖】
+{coverage_text()}
+
+回答要求:
+1. 如果用户问“你能干嘛/你能做什么/有什么功能”,请按 项目、人员、考勤排班、财务、
+   设备、证书、采购维保、检查、片区等方向概括能力,并给出 1-2 个具体可问的例子。
+2. 不要声称能查询上述范围之外的制度、流程或外部知识。
+3. 其他闲聊内容保持自然友好,不要强行罗列功能。
+"""
+    try:
+        writer = get_stream_writer()
+    except Exception:  # noqa: BLE001  非流式上下文
+        writer = None
+
+    def on_chunk(piece: str) -> None:
+        if writer is not None:
+            writer({"type": "answer_chunk", "text": piece})
+
+    ans = chat_text(sys_p, state["question"], on_chunk=on_chunk)
+    return {"answer": ans,
+            "chat_answer": ans,
             "messages": state.get("messages", []) + [{"role": "assistant", "content": ans}]}
 
 
@@ -432,7 +462,6 @@ def plan(state: dict) -> dict:
                 or state.get("run_feedback")
                 or state.get("feedback")
                 or "(首次规划)")
-    tool_fields_text = "\n".join(f"- {tool}: {'、'.join(fm)}" for tool, fm in TOOL_FIELDS.items())
     sys_p = f"""
 你是知识图谱查询规划器。根据 用户问题 + 接地槽位 + 图谱结构 + 可用工具,生成查询流程图。
 输出 JSON:{{"steps": [{{"step_id":"s1","tool":"工具名","params":{{...}},"fields":["返回字段..."],"depends":[]}}]}}
@@ -446,8 +475,6 @@ def plan(state: dict) -> dict:
   * 字段名来自「工具支持字段」清单,不要发明;
   * 必须包含 回答问题所需字段、后续步骤引用字段、能力拓展派生来源字段(source_fields,如 年龄需要 出生日期);
   * 聚合统计/缺勤分析/项目缺口分析/交集分析 等非图谱步骤 fields 写 []。
-工具支持字段:
-{tool_fields_text}
 上一轮审查反馈:{feedback}
 {build_schema_text()}"""
     payload = {
@@ -997,6 +1024,15 @@ def reflect(state: dict) -> dict:
 
 def answer(state: dict) -> dict:
     sub = json.dumps(state["subgraph"], ensure_ascii=False, default=str)
+    try:
+        writer = get_stream_writer()
+    except Exception:  # noqa: BLE001  非流式上下文(如单元测试)
+        writer = None
+
+    def on_chunk(piece: str) -> None:
+        if writer is not None:
+            writer({"type": "answer_chunk", "text": piece})
+
     sys_p = f"""你是申勤物业知识问答助手。根据 图谱结构、检索子图、用户问题 给出准确、简洁、带溯源的回答。
 规则:只依据子图中出现的事实;子图没有的信息不要编造,明确说"数据中未找到";金额带单位元,人名用标准名称。
 项目一律带唯一标识,格式“项目简称(项目编号)”,如“青浦-区图书馆(XMSQ0102)”;多个项目逐行列出。
@@ -1007,7 +1043,7 @@ def answer(state: dict) -> dict:
 派生属性(年龄/剩余服务期)回答时说明换算口径:年龄由 出生日期 与当前日期换算,剩余服务期由 项目起止时间 与当前日期换算。
 {build_schema_text(include_tools=False)}"""
     user = f"用户问题:{state['question']}\n\n检索子图:\n{sub}"
-    ans = chat_text(sys_p, user)
+    ans = chat_text(sys_p, user, on_chunk=on_chunk)
     # 把回答写回本轮结构化记录
     rounds = list(state.get("rounds", []))
     if rounds:

+ 86 - 7
src/knowledge_agent/agent/schema_context.py

@@ -6,10 +6,13 @@ Neo4j 不可用时回退静态默认值。
 
 from __future__ import annotations
 
+import inspect
 import time
 
 from ..config import get_settings
 from ..meta.schema import llm_schema_entities, llm_schema_relations
+from ..retrieval.templates import TEMPLATES as RETRIEVAL_TEMPLATES
+from ..retrieval.templates import TOOL_FIELDS as RETRIEVAL_TOOL_FIELDS
 from .derived import derived_schema_text
 
 
@@ -20,7 +23,7 @@ _TOOLS_TEXT = """
 - 收费(项目编号, 年月, 财务类型) -> 项目/人员财务
 - 设备(项目编号, 设备编号?, 设备类型?) -> 设备台账(设备锚点会给出 project_code/eq_code 拆分)
 - 服务期(工号?, 项目编号?) -> 服务期边
-- 项目列表(服务状态?, 区域?) -> 项目主数据(编号/名称/简称/服务状态/起止时间),按服务状态筛选项目用本工具
+- 项目列表(项目编号?, 服务状态?, 区域?) -> 项目主数据(编号/名称/简称/服务状态/起止时间/合同金额等),按项目编号或服务状态筛选项目用本工具
 - 人员(工号?, 姓名?, 组织?, 岗位?, 员工层级?, 司龄上限?, 司龄下限?) -> 人员属性(工号/姓名/岗位/司龄/入职日期/职级/层级/性别/电话)
 - 项目从属(项目编号) -> 子项目
 - 项目续签(项目编号) -> 上一期
@@ -40,6 +43,8 @@ _TOOLS_TEXT = """
   再用 项目缺口分析 对比——回答要说明“服务中但暂无人员服务记录”的项目(数据缺失/未录入)。
 - 统计人数(按司龄/性别/员工层级/岗位/组织)必须用 人员 工具 + 聚合统计 count(工号),不要用 服务期。
   示例:“司龄5年以下” → 人员(司龄上限=5)(表示 司龄<5),再聚合 count(工号)。
+- 统计“持证人数”时,证书表一人可能持多张证书,必须用 证书 工具 + 聚合统计 count(distinct 工号);
+  统计“证书总条数”才用 count(证书名称) 或 count(),两者不要混用。
 - 用户筛选词可能与图谱枚举值不一致(如 用户说“管理岗”,图谱岗位名称是“项目经理”)。
   “筛选值接地”(filters_grounded)已把用户词映射到规范枚举值列表(values),
   调用工具时用 values 里的规范值(如 人员(岗位=["项目经理"])),不要用用户原词。
@@ -53,6 +58,72 @@ _TOOLS_TEXT = """
 涉及"参与人数/在册 vs 实际出勤/缺勤/旷工"的问题,应同时查询 服务期 与 考勤 两个步骤,再用 缺勤分析 对比。
 """.strip()
 
+
+TOOL_PARAM_ZH: dict[str, str] = {
+    "project_code": "项目编号",
+    "month": "年月",
+    "emp_id": "工号",
+    "name": "姓名",
+    "org": "组织",
+    "position": "岗位",
+    "level": "员工层级",
+    "max_seniority": "司龄上限",
+    "min_seniority": "司龄下限",
+    "service_status": "服务状态",
+    "region": "区域",
+    "kind": "财务类型",
+    "eq_type": "设备类型",
+    "eq_code": "设备编号",
+    "category": "专业类别",
+}
+
+TOOL_DESC_ZH: dict[str, str] = {
+    "考勤": "考勤记录",
+    "排班": "排班月报",
+    "收费": "项目/人员财务",
+    "设备": "设备台账",
+    "服务期": "服务期边",
+    "项目列表": "项目主数据",
+    "人员": "人员属性",
+    "项目从属": "子项目",
+    "项目续签": "上一期",
+    "证书": "持证记录",
+}
+
+ANALYSIS_TOOLS_TEXT = """
+- 聚合统计(数据源="${步骤id}", 统计指标={"名称":"sum(字段名)"}) -> 对依赖步骤的行做 sum/avg/count/max/min 汇总
+- 缺勤分析(服务期数据源="${步骤id}", 考勤数据源="${步骤id}") -> 在册/考勤/缺勤对比
+- 项目缺口分析(项目列表数据源="${步骤id}", 服务期数据源="${步骤id}") -> 服务中但无人员服务记录的项目清单
+- 交集分析(数据源步骤=["${步骤id}", ...], 关键字段="工号", 行过滤条件={"平时加班": ">0", ...}) -> 跨步骤条件交集
+""".strip()
+
+
+def _graph_tools_text() -> str:
+    lines: list[str] = []
+    for tool, fn in RETRIEVAL_TEMPLATES.items():
+        sig = inspect.signature(fn)
+        params: list[str] = []
+        for name, p in sig.parameters.items():
+            if name in {"columns", "self"}:
+                continue
+            zh = TOOL_PARAM_ZH.get(name, name)
+            optional = p.default is not inspect.Parameter.empty
+            params.append(f"{zh}?" if optional else zh)
+        fields = "、".join(RETRIEVAL_TOOL_FIELDS.get(tool, {}))
+        desc = TOOL_DESC_ZH.get(tool, "")
+        lines.append(f"- {tool}({', '.join(params)}) -> {desc};返回字段: {fields}")
+    return "\n".join(lines)
+
+
+TOOL_SEMANTICS_TEXT = """
+工具选择语义(重要):
+- “服务期”不等于项目服务状态;统计“服务中项目数”必须用 项目列表(服务状态=\"服务中\")。
+- 统计人数按人员属性时用 人员 + 聚合统计 count(工号);统计“持证人数”用 证书 + count(distinct 工号)。
+- 参数与字段必须严格来自工具签名和返回字段,不要发明不存在的参数。
+- 各工具的 RETURN 字段以工具实际返回为准;涉及项目时优先用“项目编号”字段计数/去重。
+- 多个时间段求交集用 交集分析;连续月份逐月查询后再求交。
+""".strip()
+
 _STATIC_COVERAGE = "2026-01 至 2026-04"
 _COVERAGE_CACHE: dict = {"ts": 0.0, "text": ""}
 _COVERAGE_TTL = 60.0
@@ -65,12 +136,12 @@ def coverage_text() -> str:
         return _COVERAGE_CACHE["text"]
     text = _STATIC_COVERAGE
     try:
-        from neo4j import GraphDatabase
-        s = get_settings()
-        with GraphDatabase.driver(s.neo4j_uri, auth=(s.neo4j_user, s.neo4j_password)) as d:
-            rec = d.execute_query(
+        from ..db import get_driver
+        d = get_driver()
+        with d.session() as sess:
+            rec = list(sess.run(
                 "MATCH (n:考勤) RETURN min(n.年月) AS mn, max(n.年月) AS mx"
-            ).records
+            ))
         if rec and rec[0]["mn"]:
             text = f"{rec[0]['mn']} 至 {rec[0]['mx']}"
     except Exception:  # noqa: BLE001  Neo4j 不可用时回退静态
@@ -93,7 +164,15 @@ def build_schema_text(include_tools: bool = True) -> str:
         + ";超出范围没有数据,回答时说明\"数据未覆盖该时间\",不要凭空假设其他年份。\n\n"
     )
     if include_tools:
-        base += _TOOLS_TEXT + "\n\n"
+        base += (
+            "【可用查询工具】\n"
+            + _graph_tools_text()
+            + "\n"
+            + ANALYSIS_TOOLS_TEXT
+            + "\n\n"
+            + TOOL_SEMANTICS_TEXT
+            + "\n\n"
+        )
     return base + derived_schema_text()


+ 206 - 47
src/knowledge_agent/api.py

@@ -14,12 +14,20 @@
 from __future__ import annotations
 
 import json
+import re
 import time
+import traceback
+from contextlib import asynccontextmanager
+from datetime import datetime, timezone
+from pathlib import Path
 from typing import AsyncIterator
+from uuid import uuid4
+from zoneinfo import ZoneInfo
 
 from fastapi import FastAPI
 from fastapi.middleware.cors import CORSMiddleware
-from fastapi.responses import StreamingResponse
+from fastapi.responses import FileResponse, StreamingResponse
+from fastapi.staticfiles import StaticFiles
 from langgraph.checkpoint.memory import InMemorySaver
 from langgraph.types import Command
 from pydantic import BaseModel
@@ -27,7 +35,20 @@ from pydantic import BaseModel
 from .agent.graph import build_agent_graph
 
 
-app = FastAPI(title="申勤物业知识助手", version="0.1.0")
+@asynccontextmanager
+async def lifespan(_: FastAPI):
+    from .agent.embedding import preload_model
+
+    try:
+        preload_model()
+        print("Qwen3-Embedding-0.6B 模型已在服务启动时预加载", flush=True)
+    except Exception as exc:  # noqa: BLE001
+        # 模型加载失败不应阻塞服务启动;请求时会再次尝试并返回更完整错误。
+        print(f"Qwen3 模型预加载失败,将在首次请求时重试:{exc}", flush=True)
+    yield
+
+
+app = FastAPI(title="申勤物业知识助手", version="0.1.0", lifespan=lifespan)
 app.add_middleware(
     CORSMiddleware,
     allow_origins=["*"],
@@ -37,11 +58,19 @@ app.add_middleware(
 
 # 全局共享图:状态按 thread_id 隔离(InMemorySaver),多请求并发安全
 _graph = build_agent_graph(checkpointer=InMemorySaver())
+API_LOG_DIR = Path(__file__).resolve().parents[2] / "api_log"
+HTML_DIR = Path(__file__).resolve().parents[2] / "html"
+OUTPUT_DIR = Path(__file__).resolve().parents[2] / "output"
+
+
+@app.get("/health")
+async def health():
+    return {"status": "ok", "service": "knowledge-agent"}
 
 # 节点 → 中文处理阶段说明(SSE progress 事件携带,前端可直接展示)
 NODE_LABELS: dict[str, str] = {
     "understand": "正在理解问题(分类 + 槽位抽取)",
-    "chat": "正在回复",
+    "chat": "正在生成回答",
     "reuse_check": "正在判断是否可复用历史回答",
     "answer_reuse": "正在基于历史回答推导答案",
     "ground": "正在把问题实体对齐到知识图谱",
@@ -75,18 +104,57 @@ def _config(thread_id: str) -> dict:
     return {"configurable": {"thread_id": thread_id}}
 
 
+def _safe_thread_id(thread_id: str) -> str:
+    return re.sub(r"[^A-Za-z0-9_.-]+", "_", str(thread_id or "default"))[:64] or "default"
+
+
+def _write_api_log(endpoint: str, thread_id: str, request: dict, state: dict,
+                   elapsed_sec: float | None = None) -> None:
+    """将请求入参、完整处理 state 和最终回答写入 api_log/*.json。"""
+    try:
+        API_LOG_DIR.mkdir(parents=True, exist_ok=True)
+        ts = datetime.now(ZoneInfo("Asia/Shanghai")).isoformat(timespec="milliseconds")
+        fname = (
+            f"{ts.replace(':', '-')}_{_safe_thread_id(thread_id)}_{uuid4().hex[:8]}.json"
+        )
+        record = {
+            "timestamp": ts,
+            "endpoint": endpoint,
+            "request": request,
+            "answer": state.get("answer") or state.get("chat_answer"),
+            "elapsed_sec": elapsed_sec,
+            "state": state,
+        }
+        path = API_LOG_DIR / fname
+        path.write_text(json.dumps(record, ensure_ascii=False, indent=2, default=str),
+                        encoding="utf-8")
+    except Exception as exc:  # noqa: BLE001
+        # 日志失败不应影响接口响应
+        print(f"api_log 写入失败: {exc}", flush=True)
+
+
+def _write_api_error(endpoint: str, thread_id: str, request: dict, exc: Exception,
+                     elapsed_sec: float | None = None) -> None:
+    """请求异常也写日志,便于排查服务中断。"""
+    _write_api_log(endpoint, thread_id, request, {
+        "status": "error",
+        "error": str(exc),
+        "traceback": traceback.format_exc(),
+    }, elapsed_sec)
+
+
 def _answer_payload(thread_id: str, st: dict, elapsed: float) -> dict:
     return {
         "status": "ok",
         "thread_id": thread_id,
         "category": st.get("category"),
         "chat_answer": st.get("chat_answer"),
+        "answer": st.get("answer") or st.get("chat_answer"),
         "slots": st.get("slots", {}),
         "grounded": st.get("grounded", {}),
         "capability": st.get("capability", {}),
         "plan": st.get("plan", {}),
         "subgraph": st.get("subgraph", {}),
-        "answer": st.get("answer"),
         "rounds": st.get("rounds", []),
         "elapsed_sec": round(elapsed, 2),
     }
@@ -94,7 +162,8 @@ def _answer_payload(thread_id: str, st: dict, elapsed: float) -> dict:
 
 async def _astream_run(thread_id: str, query: str,
                        auto_confirm: bool,
-                       enable_reuse: bool = True) -> AsyncIterator[dict]:
+                       enable_reuse: bool = True,
+                       endpoint: str = "/ask") -> AsyncIterator[dict]:
     """用 graph.astream 跑完整流程(含 interrupt 自动/等待确认),产出事件。
 
     事件类型:
@@ -102,16 +171,29 @@ async def _astream_run(thread_id: str, query: str,
       {"type": "confirm", "message": ..., "options": [...]}  需要人工确认
       {"type": "done", "state": {...}}                流程完成,完整状态
     """
+    t0 = time.monotonic()
     config = _config(thread_id)
     inp: object = {"question": query, "user_id": "api", "enable_reuse": enable_reuse}
     while True:
         interrupted: object | None = None
-        async for update in _graph.astream(inp, config, stream_mode="updates"):
-            for node, payload in update.items():
-                if node == "__interrupt__":
-                    interrupted = payload
-                    continue
-                yield {"type": "node", "node": node, "payload": payload}
+        async for item in _graph.astream(inp, config, stream_mode=["updates", "custom"]):
+            if isinstance(item, tuple) and len(item) == 2:
+                mode, payload = item
+            elif isinstance(item, dict):
+                mode, payload = "updates", item
+            else:
+                continue
+            if mode == "custom":
+                if isinstance(payload, dict) and payload.get("type") == "answer_chunk":
+                    yield {"type": "chunk", "text": str(payload.get("text", ""))}
+                continue
+            if not isinstance(payload, dict):
+                continue
+            if "__interrupt__" in payload:
+                interrupted = payload["__interrupt__"]
+                continue
+            for node, p in payload.items():
+                yield {"type": "node", "node": node, "payload": p}
         if interrupted is None:
             break
         if not auto_confirm:
@@ -122,12 +204,18 @@ async def _astream_run(thread_id: str, query: str,
             return
         inp = Command(resume="确认")
     st = await _graph.aget_state(config)
-    yield {"type": "done", "state": st.values or {}}
+    state = st.values or {}
+    _write_api_log(endpoint, thread_id, {
+        "query": query,
+        "auto_confirm": auto_confirm,
+        "reuse_check": enable_reuse,
+    }, state, round(time.monotonic() - t0, 3))
+    yield {"type": "done", "state": state}
 
 
 def _interrupt_value(payload) -> dict:
     """从 astream 的 __interrupt__ 更新中提取中断值 dict(兼容 Interrupt 对象/元组/list)。"""
-    item = payload[0] if isinstance(payload, list) and payload else payload
+    item = payload[0] if isinstance(payload, (list, tuple)) and payload else payload
     if hasattr(item, "value"):
         value = item.value
     elif isinstance(item, tuple) and item:
@@ -137,18 +225,32 @@ def _interrupt_value(payload) -> dict:
     return value if isinstance(value, dict) else {}
 
 
-async def _astream_resume(thread_id: str, reply: str) -> AsyncIterator[dict]:
+async def _astream_resume(thread_id: str, reply: str,
+                          endpoint: str = "/threads/resume") -> AsyncIterator[dict]:
     """恢复被 interrupt 的会话(resume 后若再次中断,返回 confirm 等待用户)。"""
+    t0 = time.monotonic()
     config = _config(thread_id)
     inp: object = Command(resume=reply)
     while True:
         interrupted: object | None = None
-        async for update in _graph.astream(inp, config, stream_mode="updates"):
-            for node, payload in update.items():
-                if node == "__interrupt__":
-                    interrupted = payload
-                    continue
-                yield {"type": "node", "node": node, "payload": payload}
+        async for item in _graph.astream(inp, config, stream_mode=["updates", "custom"]):
+            if isinstance(item, tuple) and len(item) == 2:
+                mode, payload = item
+            elif isinstance(item, dict):
+                mode, payload = "updates", item
+            else:
+                continue
+            if mode == "custom":
+                if isinstance(payload, dict) and payload.get("type") == "answer_chunk":
+                    yield {"type": "chunk", "text": str(payload.get("text", ""))}
+                continue
+            if not isinstance(payload, dict):
+                continue
+            if "__interrupt__" in payload:
+                interrupted = payload["__interrupt__"]
+                continue
+            for node, p in payload.items():
+                yield {"type": "node", "node": node, "payload": p}
         if interrupted is None:
             break
         intr = _interrupt_value(interrupted)
@@ -157,7 +259,10 @@ async def _astream_resume(thread_id: str, reply: str) -> AsyncIterator[dict]:
                "options": intr.get("options", [])}
         return
     st = await _graph.aget_state(config)
-    yield {"type": "done", "state": st.values or {}}
+    state = st.values or {}
+    _write_api_log(endpoint, thread_id, {"reply": reply}, state,
+                   round(time.monotonic() - t0, 3))
+    yield {"type": "done", "state": state}
 
 
 @app.post("/ask")
@@ -165,11 +270,26 @@ async def ask(req: AskRequest):
     t0 = time.monotonic()
     last_state: dict = {}
     confirm_msg: dict | None = None
-    async for evt in _astream_run(req.thread_id, req.query, req.auto_confirm, req.reuse_check):
-        if evt["type"] == "done":
-            last_state = evt["state"]
-        elif evt["type"] == "confirm":
-            confirm_msg = evt
+    try:
+        async for evt in _astream_run(req.thread_id, req.query, req.auto_confirm, req.reuse_check,
+                                      endpoint="/ask"):
+            if evt["type"] == "done":
+                last_state = evt["state"]
+            elif evt["type"] == "confirm":
+                confirm_msg = evt
+    except Exception as exc:  # noqa: BLE001
+        elapsed = round(time.monotonic() - t0, 3)
+        _write_api_error("/ask", req.thread_id, {
+            "query": req.query,
+            "auto_confirm": req.auto_confirm,
+            "reuse_check": req.reuse_check,
+        }, exc, elapsed)
+        return {
+            "status": "error",
+            "thread_id": req.thread_id,
+            "message": str(exc),
+            "elapsed_sec": elapsed,
+        }
     if confirm_msg is not None:
         confirm_msg["status"] = "need_confirm"
         confirm_msg["thread_id"] = req.thread_id
@@ -183,22 +303,40 @@ async def ask_stream(req: AskRequest):
     """SSE:event: progress(节点级进度,answer 节点带增量文本);event: confirm;event: done。"""
     async def gen():
         t0 = time.monotonic()
-        async for evt in _astream_run(req.thread_id, req.query, req.auto_confirm, req.reuse_check):
-            if evt["type"] == "node":
-                data = {"node": evt["node"],
-                        "label": NODE_LABELS.get(evt["node"], evt["node"])}
-                if evt["node"] == "answer":
-                    data["answer"] = (evt["payload"] or {}).get("answer")
-                yield f"event: progress\ndata: {json.dumps(data, ensure_ascii=False)}\n\n"
-            elif evt["type"] == "confirm":
-                confirm_data = json.dumps(
-                    {"message": evt["message"], "options": evt["options"]},
-                    ensure_ascii=False,
-                )
-                yield f"event: confirm\ndata: {confirm_data}\n\n"
-            elif evt["type"] == "done":
-                final = _answer_payload(req.thread_id, evt["state"], time.monotonic() - t0)
-                yield f"event: done\ndata: {json.dumps(final, ensure_ascii=False)}\n\n"
+        try:
+            async for evt in _astream_run(req.thread_id, req.query, req.auto_confirm,
+                                          req.reuse_check, endpoint="/ask/stream"):
+                if evt["type"] == "chunk":
+                    yield (f"event: answer_chunk\ndata: "
+                           f"{json.dumps({'text': evt['text']}, ensure_ascii=False)}\n\n")
+                elif evt["type"] == "node":
+                    data = {"node": evt["node"],
+                            "label": NODE_LABELS.get(evt["node"], evt["node"])}
+                    if evt["node"] == "answer":
+                        data["answer"] = (evt["payload"] or {}).get("answer")
+                    elif evt["node"] == "chat":
+                        data["answer"] = ((evt["payload"] or {}).get("answer")
+                                          or (evt["payload"] or {}).get("chat_answer"))
+                    yield f"event: progress\ndata: {json.dumps(data, ensure_ascii=False)}\n\n"
+                elif evt["type"] == "confirm":
+                    confirm_data = json.dumps(
+                        {"message": evt["message"], "options": evt["options"]},
+                        ensure_ascii=False,
+                    )
+                    yield f"event: confirm\ndata: {confirm_data}\n\n"
+                elif evt["type"] == "done":
+                    final = _answer_payload(req.thread_id, evt["state"],
+                                            time.monotonic() - t0)
+                    yield f"event: done\ndata: {json.dumps(final, ensure_ascii=False)}\n\n"
+        except Exception as exc:  # noqa: BLE001
+            elapsed = round(time.monotonic() - t0, 3)
+            _write_api_error("/ask/stream", req.thread_id, {
+                "query": req.query,
+                "auto_confirm": req.auto_confirm,
+                "reuse_check": req.reuse_check,
+            }, exc, elapsed)
+            yield (f"event: error\ndata: "
+                   f"{json.dumps({'message': str(exc)}, ensure_ascii=False)}\n\n")
 
     return StreamingResponse(gen(), media_type="text/event-stream")
 
@@ -208,11 +346,23 @@ async def resume(thread_id: str, body: ResumeRequest):
     t0 = time.monotonic()
     last_state: dict = {}
     confirm_msg: dict | None = None
-    async for evt in _astream_resume(thread_id, body.reply):
-        if evt["type"] == "done":
-            last_state = evt["state"]
-        elif evt["type"] == "confirm":
-            confirm_msg = evt
+    try:
+        async for evt in _astream_resume(thread_id, body.reply,
+                                         endpoint=f"/threads/{thread_id}/resume"):
+            if evt["type"] == "done":
+                last_state = evt["state"]
+            elif evt["type"] == "confirm":
+                confirm_msg = evt
+    except Exception as exc:  # noqa: BLE001
+        elapsed = round(time.monotonic() - t0, 3)
+        _write_api_error(f"/threads/{thread_id}/resume", thread_id,
+                         {"reply": body.reply}, exc, elapsed)
+        return {
+            "status": "error",
+            "thread_id": thread_id,
+            "message": str(exc),
+            "elapsed_sec": elapsed,
+        }
     if confirm_msg is not None:
         confirm_msg["status"] = "need_confirm"
         confirm_msg["thread_id"] = thread_id
@@ -232,6 +382,15 @@ async def history(thread_id: str):
     }
 
 
+@app.get("/", include_in_schema=False)
+async def root():
+    return FileResponse(HTML_DIR / "knowledge_graph_3d.html")
+
+app.mount("/html", StaticFiles(directory=str(HTML_DIR), html=True), name="frontend-html")
+app.mount("/output", StaticFiles(directory=str(OUTPUT_DIR), html=False), name="frontend-output")
+app.mount("/", StaticFiles(directory=str(HTML_DIR), html=True), name="frontend")
+
+
 def run(host: str = "127.0.0.1", port: int = 8000) -> None:
     import uvicorn
     uvicorn.run(app, host=host, port=port)

+ 5 - 1
src/knowledge_agent/db.py

@@ -14,5 +14,9 @@ def get_driver():
     global _driver
     if _driver is None:
         s = get_settings()
-        _driver = GraphDatabase.driver(s.neo4j_uri, auth=(s.neo4j_user, s.neo4j_password))
+        _driver = GraphDatabase.driver(
+            s.neo4j_uri,
+            auth=(s.neo4j_user, s.neo4j_password),
+            connection_timeout=3.0,   # 连接失败快速返回,避免启动探测长时间重试
+        )
     return _driver

+ 1 - 2
src/knowledge_agent/graph/__init__.py

@@ -1,6 +1,5 @@
-"""全量知识图谱构建:读取 12 类 Excel(每类可多份文件)并写入 Neo4j。"""
+"""全量知识图谱构建:读取 15 类 Excel(每类可多份文件)并写入 Neo4j。"""
 
 from .pipeline import build_knowledge_graph
 
 __all__ = ["build_knowledge_graph"]
-

+ 62 - 6
src/knowledge_agent/graph/builder.py

@@ -6,9 +6,9 @@ from collections import defaultdict
 
 from neo4j import GraphDatabase
 
-from .schemas import (Area, Attendance, Bid, Certificate, Equipment, Inspection,
-                      Person, Procurement, Project, ProjectArea,
-                      ProjectFinance, Record, Schedule, Staffing)
+from .schemas import (AccountBalance, Area, Attendance, Bid, Certificate, Equipment,
+                      Inspection, MonthlySnapshot, Person, Procurement, Project,
+                      ProjectArea, ProjectFinance, Record, Schedule, Staffing)
 
 
 def _run(driver, query: str, **params) -> None:
@@ -119,6 +119,34 @@ def create_finance(driver, project_finance: list[ProjectFinance], attendance: li
     return len(project_finance) + len(attendance)
 
 
+def create_monthly_snapshots(driver, records: list[MonthlySnapshot]) -> int:
+    for s in records:
+        _run(driver, """
+            MERGE (x:月度快照 {项目编号:$proj, 年月:$month})
+            SET x.项目名称 = $proj_name, x.在岗人数 = $headcount,
+                x.排班人次 = $schedule_count, x.考勤人次 = $attendance_count,
+                x.开票金额 = $invoice_amount, x.收款金额 = $receipt_amount, x.备注 = $remark
+            """, proj=s.project_code, month=s.month, proj_name=s.project_name,
+            headcount=s.headcount, schedule_count=s.schedule_count,
+            attendance_count=s.attendance_count, invoice_amount=s.invoice_amount,
+            receipt_amount=s.receipt_amount, remark=s.remark)
+    return len(records)
+
+
+def create_account_balances(driver, records: list[AccountBalance]) -> int:
+    for r in records:
+        _run(driver, """
+            MERGE (x:科目余额 {项目编号:$proj, 期间:$period, 科目编码:$account_code})
+            SET x.项目名称 = $proj_name, x.科目名称 = $account_name,
+                x.借方发生额 = $debit_amount, x.贷方发生额 = $credit_amount,
+                x.期末余额 = $closing_balance, x.备注 = $remark
+            """, proj=r.project_code, period=r.period, account_code=r.account_code,
+            proj_name=r.project_name, account_name=r.account_name,
+            debit_amount=r.debit_amount, credit_amount=r.credit_amount,
+            closing_balance=r.closing_balance, remark=r.remark)
+    return len(records)
+
+
 def create_bids(driver, records: list[Bid]) -> int:
     for b in records:
         _run(driver, """
@@ -216,6 +244,8 @@ def add_display_props(driver) -> int:
         ("MATCH (n:考勤) SET n.display = n.年月",),
         ("MATCH (n:排班月报) SET n.display = n.年月",),
         ("MATCH (n:财务) SET n.display = n.年月",),
+        ("MATCH (n:月度快照) SET n.display = n.年月",),
+        ("MATCH (n:科目余额) SET n.display = n.科目名称",),
         ("MATCH (n:投标记录) SET n.display = toString(n.年份)",),
         ("MATCH (n:岗位编制) SET n.display = n.岗位",),
         ("MATCH (n:设备) SET n.display = n.名称",),
@@ -304,6 +334,24 @@ def link_finance(driver, project_finance: list[ProjectFinance], attendance: list
     return count
 
 
+def link_monthly_snapshots(driver, records: list[MonthlySnapshot]) -> int:
+    for s in records:
+        _run(driver, """
+            MATCH (p:项目 {编号:$proj}), (x:月度快照 {项目编号:$proj, 年月:$month})
+            MERGE (p)-[:月度]->(x)
+            """, proj=s.project_code, month=s.month)
+    return len(records)
+
+
+def link_account_balances(driver, records: list[AccountBalance]) -> int:
+    for r in records:
+        _run(driver, """
+            MATCH (p:项目 {编号:$proj}), (x:科目余额 {项目编号:$proj, 期间:$period, 科目编码:$account_code})
+            MERGE (p)-[:科目]->(x)
+            """, proj=r.project_code, period=r.period, account_code=r.account_code)
+    return len(records)
+
+
 def link_bids(driver, records: list[Bid]) -> int:
     for b in records:
         _run(driver, "MATCH (p:项目 {编号:$proj}), (x:投标记录 {项目编号:$proj, 年份:$year}) "
@@ -393,7 +441,7 @@ def link_certificates(driver, records: list[Certificate]) -> int:
 def derive_service_periods(driver, records: dict[str, list[Record]], warnings: list[str]) -> int:
     """由考勤/排班的连续月份推导 服务于 边。"""
     pairs: dict[tuple[str, str], set[str]] = defaultdict(set)
-    for rec in records.get("考勤与人员财务", []) + records.get("排班明细", []):
+    for rec in records.get("考勤与人员财务", []) + records.get("排班月报", []):
         if rec.emp_id and rec.project_code and rec.month:
             pairs[(rec.emp_id, rec.project_code)].add(rec.month)
 
@@ -430,14 +478,18 @@ def build_all(driver, records: dict[str, list[Record]]) -> dict:
     persons = records["人员信息"]
     attendance = records["考勤与人员财务"]
     project_finance = records["项目月度财务"]
+    snapshots = records["月度快照"]
+    account_balances = records["科目余额"]
 
     # 阶段一:全部节点
     nodes = {
         "项目": create_projects(driver, projects),
         "人员": create_persons(driver, persons),
         "考勤": create_attendance(driver, attendance),
-        "排班月报": create_schedules(driver, records["排班明细"]),
+        "排班月报": create_schedules(driver, records["排班月报"]),
         "财务": create_finance(driver, project_finance, attendance),
+        "月度快照": create_monthly_snapshots(driver, snapshots),
+        "科目余额": create_account_balances(driver, account_balances),
         "投标记录": create_bids(driver, records["投标记录"]),
         "岗位编制": create_staffing(driver, records["岗位编制"]),
         "设备": create_equipment(driver, records["设备信息"]),
@@ -453,8 +505,10 @@ def build_all(driver, records: dict[str, list[Record]]) -> dict:
         "项目负责人": link_project_managers(driver, projects),
         "服务期(直接填写)": link_person_service(driver, persons),
         "有考勤": link_attendance(driver, attendance),
-        "有排班": link_schedules(driver, records["排班明细"]),
+        "有排班": link_schedules(driver, records["排班月报"]),
         "月度财务": link_finance(driver, project_finance, attendance),
+        "月度快照": link_monthly_snapshots(driver, snapshots),
+        "科目余额": link_account_balances(driver, account_balances),
         "投标": link_bids(driver, records["投标记录"]),
         "编制": link_staffing(driver, records["岗位编制"]),
         "设备关系": link_equipment(driver, records["设备信息"]),
@@ -491,6 +545,8 @@ def validate_references(driver) -> list[str]:
         ("MATCH (a:考勤) WHERE NOT (a)-[:所属项目]->(:项目) RETURN count(a) AS n", "考勤缺项目节点"),
         ("MATCH (a:排班月报) WHERE NOT (a)<-[:有排班]-(:人员) RETURN count(a) AS n", "排班缺人员节点"),
         ("MATCH (f:财务 {财务类型:'项目财务'}) WHERE NOT (f)-[:经办人]->(:人员) RETURN count(f) AS n", "项目财务缺经办人"),
+        ("MATCH (s:月度快照) WHERE NOT (s)<-[:月度]-(:项目) RETURN count(s) AS n", "月度快照缺项目节点"),
+        ("MATCH (a:科目余额) WHERE NOT (a)<-[:科目]-(:项目) RETURN count(a) AS n", "科目余额缺项目节点"),
         ("MATCH (b:投标记录) WHERE NOT (b)-[:经办人]->(:人员) RETURN count(b) AS n", "投标记录缺经办人"),
         ("MATCH (i:检查记录) WHERE NOT (i)-[:检查人]->(:人员) RETURN count(i) AS n", "检查记录缺检查人"),
         ("MATCH (e:设备) WHERE NOT (e)-[:责任人]->(:人员) RETURN count(e) AS n", "设备缺责任人"),

+ 2 - 2
src/knowledge_agent/graph/pipeline.py

@@ -1,4 +1,4 @@
-"""图谱构建入口:接收 12 类文件数组(每类可多份),校验并写入 Neo4j。"""
+"""图谱构建入口:接收 15 类文件数组(每类可多份),校验并写入 Neo4j。"""
 
 from __future__ import annotations
 
@@ -19,7 +19,7 @@ def build_knowledge_graph(
     neo4j_password: str | None = None,
     clear_first: bool = False,
 ) -> dict[str, Any]:
-    """按 12 类文件数组构建知识图谱。
+    """按 15 类文件数组构建知识图谱。
 
     config: {"项目信息": [文件...], "项目月度财务": [...], ...}
     """

+ 3 - 3
src/knowledge_agent/graph/reader.py

@@ -1,4 +1,4 @@
-"""读取 12 类 Excel(每类可多份文件),解析为类型化记录并做字段校验。"""
+"""读取 15 类 Excel(每类可多份文件),解析为类型化记录并做字段校验。"""
 
 from __future__ import annotations
 
@@ -22,7 +22,7 @@ class ValidationIssue:
 
 
 def _read_rows(path: Path) -> tuple[list[str], list[tuple[int, dict[str, str]]]]:
-    df = pd.read_excel(path, dtype=str)
+    df = pd.read_csv(path, dtype=str, encoding="utf-8-sig", keep_default_na=False)
     df.columns = [norm_header(c) for c in df.columns]
     headers = list(df.columns)
     rows: list[tuple[int, dict[str, str]]] = []
@@ -74,7 +74,7 @@ def parse_category(category: str, paths: list[Path], issues: list[ValidationIssu
 
 
 def load_all(config: dict[str, Any]) -> tuple[dict[str, list[Record]], list[ValidationIssue]]:
-    """config: {类别名: [文件路径...]},支持 12 类。"""
+    """config: {类别名: [文件路径...]},支持 15 类。"""
     issues: list[ValidationIssue] = []
     result: dict[str, list[Record]] = {}
     for category, model in CATEGORIES.items():

+ 71 - 3
src/knowledge_agent/graph/schemas.py

@@ -1,4 +1,4 @@
-"""12 类模板数据的字段定义与解析。"""
+"""15 类模板数据的字段定义与解析。"""
 
 from __future__ import annotations
 
@@ -295,6 +295,72 @@ class ProjectFinance(Record):
         return to_float(v)
 
 
+class MonthlySnapshot(Record):
+    project_code: str = ""
+    project_name: str = ""
+    month: str = ""
+    headcount: float | None = None
+    schedule_count: float | None = None
+    attendance_count: float | None = None
+    invoice_amount: float | None = None
+    receipt_amount: float | None = None
+    remark: str = ""
+
+    columns = {
+        "项目编号": "project_code", "项目名称": "project_name", "年月": "month",
+        "在岗人数": "headcount", "排班人次": "schedule_count", "考勤人次": "attendance_count",
+        "开票金额": "invoice_amount", "收款金额": "receipt_amount", "备注": "remark",
+    }
+
+    @classmethod
+    def required(cls) -> list[str]:
+        return ["project_code", "month"]
+
+    @field_validator("month", mode="before")
+    @classmethod
+    def _m(cls, v):
+        return norm_month(v)
+
+    @field_validator("headcount", "schedule_count", "attendance_count", "invoice_amount",
+                     "receipt_amount", mode="before")
+    @classmethod
+    def _n(cls, v):
+        return to_float(v)
+
+
+class AccountBalance(Record):
+    project_code: str = ""
+    project_name: str = ""
+    period: str = ""
+    account_code: str = ""
+    account_name: str = ""
+    debit_amount: float | None = None
+    credit_amount: float | None = None
+    closing_balance: float | None = None
+    remark: str = ""
+
+    columns = {
+        "项目编号": "project_code", "项目名称": "project_name", "期间": "period",
+        "科目编码": "account_code", "科目名称": "account_name",
+        "借方发生额": "debit_amount", "贷方发生额": "credit_amount",
+        "期末余额": "closing_balance", "备注": "remark",
+    }
+
+    @classmethod
+    def required(cls) -> list[str]:
+        return ["project_code", "period", "account_code"]
+
+    @field_validator("period", mode="before")
+    @classmethod
+    def _m(cls, v):
+        return norm_month(v)
+
+    @field_validator("debit_amount", "credit_amount", "closing_balance", mode="before")
+    @classmethod
+    def _n(cls, v):
+        return to_float(v)
+
+
 class Bid(Record):
     project_code: str = ""
     project_name: str = ""
@@ -531,14 +597,16 @@ class Certificate(Record):
         return ["emp_id", "cert_name"]
 
 
-# 12 类模板:类名 → 说明
+# 15 类模板:类名 → 说明
 CATEGORIES: dict[str, type[Record]] = {
     "项目信息": Project,
     "项目月度财务": ProjectFinance,
+    "月度快照": MonthlySnapshot,
+    "科目余额": AccountBalance,
     "投标记录": Bid,
     "人员信息": Person,
     "考勤与人员财务": Attendance,
-    "排班明细": Schedule,
+    "排班月报": Schedule,
     "岗位编制": Staffing,
     "设备信息": Equipment,
     "采购与维保": Procurement,

+ 34 - 3
src/knowledge_agent/meta/render.py

@@ -3,6 +3,7 @@
 from __future__ import annotations
 
 import matplotlib
+from matplotlib.patches import FancyArrowPatch
 
 matplotlib.use("Agg")
 import matplotlib.pyplot as plt
@@ -36,6 +37,7 @@ def _layout_pos() -> dict:
         "月度快照": (4.2, 1.8),
         "科目余额": (4.2, 0.0),
         "投标记录": (4.2, -1.8),
+        "检查记录": (4.2, -3.6),
         "采购记录": (-4.2, -5.2),
         "维保合同": (4.2, -5.2),
         "供应商": (0, -6.4),
@@ -79,11 +81,40 @@ def render(out_path: str = "meta_graph_v7.png") -> str:
     labels = {n: n if not g.nodes[n]["suggested"] else f"{n}\n(建议)" for n in g.nodes}
     nx.draw_networkx_labels(g, pos, labels=labels, font_size=12,
                             font_family=fp.get_name(), font_color="white", ax=ax)
-    nx.draw_networkx_edges(g, pos, arrows=True, arrowstyle="-|>", arrowsize=18,
-                           edge_color="#666666", width=1.6, ax=ax)
-    nx.draw_networkx_edge_labels(g, pos, edge_labels={e: d["label"] for e, d in g.edges.items()},
+    normal_edges = [(u, v) for u, v in g.edges if u != v]
+    nx.draw_networkx_edges(g, pos, edgelist=normal_edges, arrows=True, arrowstyle="-|>",
+                           arrowsize=18, edge_color="#666666", width=1.6, ax=ax)
+    nx.draw_networkx_edge_labels(g, pos,
+                                 edge_labels={e: d["label"] for e, d in g.edges.items() if e[0] != e[1]},
                                  font_size=8, font_family=fp.get_name(), ax=ax)
 
+    # 项目自环:包含 / 续签自,分别用上下弧线画出,避免重叠后看不清
+    self_relations = [
+        (r.source, r.target, f"{r.rel_type}\n({r.key})")
+        for r in RELATIONS
+        if r.source == r.target
+    ]
+    for i, (u, v, label) in enumerate(self_relations):
+        rad = 0.48 if i % 2 == 0 else -0.48
+        x, y = pos[u]
+        ax.annotate(
+            "",
+            xy=(x + 0.14, y + (0.38 if rad > 0 else -0.38)),
+            xytext=(x - 0.14, y + (0.38 if rad > 0 else -0.38)),
+            arrowprops=dict(
+                arrowstyle="-|>",
+                color="#C55A11" if i else "#2E75B6",
+                lw=2.5,
+                connectionstyle=f"arc3,rad={rad}",
+                mutation_scale=20,
+            ),
+        )
+        label_text = label.replace("\n", " ")
+        ax.text(x + (0.45 if rad > 0 else -0.45), y + (0.62 if rad > 0 else -0.62),
+                label_text, fontsize=8, fontfamily=fp.get_name(), ha="center", va="center",
+                color="#C55A11" if i else "#2E75B6",
+                bbox={"facecolor": "white", "edgecolor": "none", "alpha": 0.75})
+
     # 图例
     legend_items = [plt.Line2D([0], [0], marker="o", color="w", markerfacecolor=c,
                                markersize=12, label=k) for k, c in colors.items()]

+ 7 - 8
src/knowledge_agent/meta/schema.py

@@ -49,8 +49,8 @@ ENTITIES: list[EntitySpec] = [
         "财务类型(项目财务/人员财务) / 年月 / "
         "项目财务: 开票金额、收款金额;人员财务: 餐费补助、加班超时费、国定加班费、值班费、税后工资(可选)",
     ),
-    EntitySpec("科目余额", "财务部", "项目 × 会计科目 × 期间:科目编码/名称、借方/贷方发生额、期末余额",
-               active=False),
+    EntitySpec("科目余额", "财务部",
+               "项目编号 / 期间 / 科目编码 / 科目名称 / 借方发生额 / 贷方发生额 / 期末余额 / 备注"),
     EntitySpec("投标记录", "市场部", "项目 × 年份:招标/投标/中标、中标结果、中标日期、文档路径"),
     EntitySpec("岗位编制", "运营部", "项目 × 岗位:预算编制、项目编制、标准工时人数、在岗人数"),
     EntitySpec(
@@ -59,15 +59,14 @@ ENTITIES: list[EntitySpec] = [
         "出厂日期 / 启用日期 / 出厂编号 / 完好状况 / 原值",
     ),
     EntitySpec("考勤", "人事部", "年月 + 1-31号具体考勤情况(月度记录)"),
-    EntitySpec("排班月报", "人事部", "年月 + 1-31号班次(与考勤同构)", suggested=True),
+    EntitySpec("排班月报", "人事部", "年月 + 1-31号班次(与考勤同构)"),
     EntitySpec("供应商", "采购部", "供应商名称/类别/联系人/联系电话"),
     EntitySpec("维保合同", "采购部", "维保类别/维保单位/合同年限/维保费用/标书费用/合同费用"),
     EntitySpec("采购记录", "采购部", "品类/数量/单价/金额/月份(耗材、固定资产等)"),
     EntitySpec("检查记录", "运营部", "项目编号/检查类型/检查日期/检查得分/问题描述/整改情况/整改完成日期/检查人工号"),
     EntitySpec(
         "月度快照", "财务部",
-        "年月 + 项目月度汇总(人数/排班/考勤/收费等,聚合层)",
-        suggested=True, active=False,
+        "项目编号 / 年月 / 在岗人数 / 排班人次 / 考勤人次 / 开票金额 / 收款金额 / 备注",
     ),
 ]
 
@@ -98,7 +97,7 @@ RELATIONS: list[RelationSpec] = [
     RelationSpec("维保合同", "供应商", "维保单位", "维保单位名称", "N:1"),
     RelationSpec("维保合同", "人员", "经办人", "经办人工号", "N:1"),
     RelationSpec("项目", "岗位编制", "编制", "项目编号 + 岗位", "1:N"),
-    RelationSpec("项目", "科目余额", "科目", "项目编号 + 期间", "1:N"),
+    RelationSpec("项目", "科目余额", "科目", "项目编号 + 期间 + 科目编码", "1:N"),
     # 人员 ↔ 考勤:月事实边
     RelationSpec("人员", "考勤", "有考勤", "工号 + 年月", "1:N"),
     RelationSpec("人员", "证书", "持有", "工号 + 证书名称", "1:N",
@@ -113,8 +112,8 @@ RELATIONS: list[RelationSpec] = [
     # 人员 ↔ 排班(建议节点)
     RelationSpec("人员", "排班月报", "有排班", "工号 + 年月", "1:N"),
     RelationSpec("排班月报", "项目", "所属项目", "项目简称 + 年月", "N:1"),
-    # 项目 → 月度快照(建议聚合节点)
-    RelationSpec("项目", "月度快照", "月度", "项目简称 + 年月", "1:N"),
+    # 项目 → 月度快照(聚合节点)
+    RelationSpec("项目", "月度快照", "月度", "项目编号 + 年月", "1:N"),
     # 设备 ↔ 项目
     RelationSpec("设备", "项目", "所属项目", "管理处名称", "N:1"),
     RelationSpec("设备", "人员", "责任人", "设备责任人工号", "N:1"),

+ 48 - 6
src/knowledge_agent/retrieval/templates.py

@@ -2,6 +2,7 @@
 
 from __future__ import annotations
 
+import re
 from dataclasses import dataclass, field
 from typing import Any
 
@@ -44,7 +45,10 @@ TOOL_FIELDS: dict[str, dict[str, str]] = {
                "项目": "p.简称", "开始": "s.开始", "结束": "s.结束"},
     "项目列表": {"项目编号": "p.编号", "项目名称": "p.名称", "项目": "p.简称",
                   "服务状态": "p.服务状态", "起止时间": "p.项目起止时间",
-                  "上级项目编号": "p.上级项目编号"},
+                  "上级项目编号": "p.上级项目编号", "合同金额": "p.合同金额",
+                  "年化合同额": "p.年化合同额", "合同面积": "p.合同面积",
+                  "甲方名称": "p.甲方名称", "项目地址": "p.项目地址",
+                  "项目负责人": "p.项目负责人"},
     "人员": {"工号": "e.工号", "姓名": "e.姓名", "组织名称": "e.组织名称",
              "岗位名称": "e.岗位名称", "司龄": "e.司龄", "入职日期": "e.入职日期",
              "职级": "e.职级", "员工层级": "e.员工层级", "性别": "e.性别",
@@ -56,13 +60,30 @@ TOOL_FIELDS: dict[str, dict[str, str]] = {
                   "上一期编号": "prev.编号", "当前期时间": "c.起止时间"},
 }
 
+
+# 各工具主节点在 Cypher 中的别名,用于元数据驱动兜底映射。
+TOOL_ALIASES: dict[str, str] = {
+    "考勤": "a",
+    "排班": "s",
+    "收费": "f",
+    "设备": "e",
+    "服务期": "s",
+    "项目列表": "p",
+    "人员": "e",
+    "证书": "c",
+    "项目从属": "c",
+    "项目续签": "c",
+}
+
 TOOL_DEFAULT_ORDER: dict[str, list[str]] = {
     "考勤": ["姓名", "工号", "年月", "上班天数", "平时加班", "国定加班", "餐费", "加班超时费", "值班费"],
     "排班": ["姓名", "工号", "年月", "每日班次"],
     "收费": ["项目编号", "工号", "年月", "开票金额", "收款金额", "餐费", "加班超时费", "值班费", "税后工资"],
     "设备": ["项目编号", "设备编号", "类型", "名称", "位置", "状况", "原值"],
     "服务期": ["姓名", "工号", "项目编号", "项目名称", "项目", "开始", "结束"],
-    "项目列表": ["项目编号", "项目名称", "项目", "服务状态", "起止时间", "上级项目编号"],
+    "项目列表": ["项目编号", "项目名称", "项目", "服务状态", "起止时间",
+                  "上级项目编号", "合同金额", "年化合同额", "合同面积",
+                  "甲方名称", "项目地址", "项目负责人"],
     "人员": ["工号", "姓名", "组织名称", "岗位名称", "司龄", "入职日期", "职级", "员工层级",
              "性别", "政治面貌", "联系电话", "出生日期"],
     "证书": ["姓名", "工号", "证书名称", "专业类别", "证书类别"],
@@ -74,10 +95,27 @@ TOOL_DEFAULT_ORDER: dict[str, list[str]] = {
 def _build_return(tool: str, columns: list[str] | None) -> str:
     """按需构建 RETURN 子句;columns 为空时返回该工具默认全字段。"""
     fm = TOOL_FIELDS.get(tool, {})
-    keys = [k for k in (columns or TOOL_DEFAULT_ORDER.get(tool, [])) if k in fm]
-    if not keys:
-        keys = TOOL_DEFAULT_ORDER.get(tool, [])
-    return ", ".join(f"{fm[k]} AS {k}" for k in keys if k in fm)
+    requested = columns or TOOL_DEFAULT_ORDER.get(tool, list(fm))
+    alias = TOOL_ALIASES.get(tool)
+    exprs: list[str] = []
+    seen: set[str] = set()
+    for k in requested:
+        k = str(k).strip()
+        if not k or k in seen:
+            continue
+        if k in fm:
+            exprs.append(f"{fm[k]} AS {k}")
+            seen.add(k)
+            continue
+        # 元数据驱动兜底:字段名与图属性同名,且是安全标识符时自动映射。
+        if alias and re.fullmatch(r"[\w\u4e00-\u9fa5]+", k):
+            exprs.append(f"{alias}.{k} AS {k}")
+            seen.add(k)
+    if not exprs:
+        for k in TOOL_DEFAULT_ORDER.get(tool, []):
+            if k in fm:
+                exprs.append(f"{fm[k]} AS {k}")
+    return ", ".join(exprs)
 
 
 def query_attendance(project_code: str | None = None, month: str | None = None,
@@ -176,9 +214,13 @@ def query_service_period(emp_id: str | None = None,
 
 def query_projects(service_status: str | None = None,
                    region: str | None = None,
+                   project_code: str | None = None,
                    columns: list[str] | None = None) -> QueryResult:
     """项目主数据查询:按服务状态/区域过滤(统计“服务中项目数”用本工具)。"""
     cond, params = [], {}
+    if project_code:
+        cond.append("p.编号 = $project_code")
+        params["project_code"] = project_code
     if service_status:
         if isinstance(service_status, list):
             cond.append("p.服务状态 IN $statuses")

Деякі файли не було показано, через те що забагато файлів було змінено